Related Experiment Video
Updated: May 1, 2026


Augmenting Large Language Models via Vector Embeddings to Improve Domain-Specific Responsiveness
Published on: December 6, 2024
Adaptation of machine translation for multilingual information retrieval in the medical domain
Pavel Pecina1, Ondřej Dušek1, Lorraine Goeuriot2
1Institute of Formal and Applied Linguistics, Faculty of Mathematics and Physics, Charles University in Prague, Malostranské nám. 25, 118 00 Prague 1, Czech Republic.

Objective:
We investigate machine translation (MT) of user search queries in the context of cross-lingual information retrieval (IR) in the medical domain. The main focus is on techniques to adapt MT to increase translation quality; however, we also explore MT adaptation to improve effectiveness of cross-lingual IR.
Methods And Data:
Our MT system is Moses, a state-of-the-art phrase-based statistical machine translation system. The IR system is based on the BM25 retrieval model implemented in the Lucene search engine. The MT techniques employed in this work include in-domain training and tuning, intelligent training data selection, optimization of phrase table configuration, compound splitting, and exploiting synonyms as translation variants. The IR methods include morphological normalization and using multiple translation variants for query expansion. The experiments are performed and thoroughly evaluated on three language pairs: Czech-English, German-English, and French-English. MT quality is evaluated on data sets created within the Khresmoi project and IR effectiveness is tested on the CLEF eHealth 2013 data sets.
Results:
The search query translation results achieved in our experiments are outstanding - our systems outperform not only our strong baselines, but also Google Translate and Microsoft Bing Translator in direct comparison carried out on all the language pairs. The baseline BLEU scores increased from 26.59 to 41.45 for Czech-English, from 23.03 to 40.82 for German-English, and from 32.67 to 40.82 for French-English. This is a 55% improvement on average. In terms of the IR performance on this particular test collection, a significant improvement over the baseline is achieved only for French-English. For Czech-English and German-English, the increased MT quality does not lead to better IR results.
Conclusions:
Most of the MT techniques employed in our experiments improve MT of medical search queries. Especially the intelligent training data selection proves to be very successful for domain adaptation of MT. Certain improvements are also obtained from German compound splitting on the source language side. Translation quality, however, does not appear to correlate with the IR performance - better translation does not necessarily yield better retrieval. We discuss in detail the contribution of the individual techniques and state-of-the-art features and provide future research directions.
More Related Videos
 05:47
Evidence-based Knowledge Synthesis and Hypothesis Validation: Navigating Biomedical Knowledge Bases via Explainable AI and Agentic Systems
Published on: June 13, 2025
 07:50
A Metadata Extraction Approach for Clinical Case Reports to Enable Advanced Understanding of Biomedical Concepts
Published on: September 20, 2018
Related Concept Videos
 01:31
Translation
 01:31
Translation
01:31Translation
Translation Produces the Building Blocks of Life
Proteins are...
01:31Translation
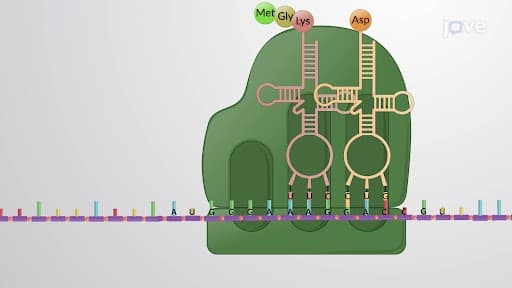
Translation is the process of synthesizing proteins from the genetic information carried by messenger RNA (mRNA). Following transcription, it constitutes the final step in the expression of genes. This process is carried out by ribosomes, complexes of protein and specialized RNA molecules. Ribosomes, transfer RNA (tRNA), and other proteins produce a chain of amino acids—the polypeptide—as the end product of translation.
Translation Produces the Building Blocks of...
 02:07
Improving Translational Accuracy
02:07Improving Translational Accuracy