Related Experiment Video
Updated: Apr 30, 2026

Modeling the Size Spectrum for Macroinvertebrates and Fishes in Stream Ecosystems
Published on: July 30, 2019
ESTIMATION METHOD OF THE HOMODYNED K-DISTRIBUTION BASED ON THE MEAN INTENSITY AND TWO LOG-MOMENTS
François Destrempes1, Jonathan Porée2, Guy Cloutier3
1Laboratory of Biorheology and Medical Ultrasonics, University of Montreal Hospital Research Center (CRCHUM), Montréal, Québec, H2L-2W5 Canada.

Abstract:
The homodyned K-distribution appears naturally in the context of random walks and provides a useful model for the distribution of the received intensity in a wide range of non-Gaussian scattering configurations, including medical ultrasonics. An estimation method for the homodyned K-distribution based on the first moment of the intensity and two log-moments (XU method), namely the X and U-statistics previously studied in the special case of the K-distribution, is proposed as an alternative to a method based on the first three moments of the intensity (MI method) or the amplitude (MA method), and a method based on the signal-to-noise ratio (SNR), the skewness and the kurtosis of two fractional orders of the amplitude (labeled RSK method). Properties of the X and U statistics for the homodyned K-distribution are proved, except for one conjecture. Using those properties, an algorithm based on the bisection method for monotonous functions was developed. The algorithm has a geometric rate of convergence. Various tests were performed to study the behavior of the estimators. It was shown with simulated data samples that the estimations of the parameters 1/α and 1/(κ + 1) of the homodyned K-distribution are preferable to the direct estimations of the clustering parameter α and the structure parameter κ (with respective relative root mean squared errors (RMSEs) of 0.63 and 0.13 as opposed to 1.04 and 4.37, when N = 1000). Tests on simulated ultrasound images with only diffuse scatterers (up to 10 per resolution cell) indicated that the XU estimator is overall more reliable than the other three estimators for the estimation of 1/α, with relative RMSEs of 0.79 (MI), 0.61 (MA), 0.53 (XU) and 0.67 (RSK). For the parameter 1/(κ + 1), the relative RMSEs were equal to 0.074 (MI), 0.075 (MA), 0.069 (XU) and 0.100 (RSK). In the case of a large number of scatterers (11 to 20 per resolution cell), the relative RMSEs of 1/α were equal to 1.43 (MI), 1.27 (MA), 1.25 (XU) and 1.33 (RSK), and the relative RMSEs of 1/(κ + 1) were equal to 0.14 (MI), 0.16 (MA), 0.17 (XU) and 0.20 (RSK). The four methods were also tested on simulated ultrasound images with a variable density of periodic scatterers to test images with a coherent component. The addition of noise on ultrasound images was also studied. Results showed that the XU estimator was overall better than the three other ones. Finally, on the simulated ultrasound images, the average computation times per image were equal to 6.0 ms (MI), 8.0 ms (MA), 6.8 ms (XU) and 500 ms (RSK). Thus, a fast, reliable, and novel algorithm for the estimation of the homodyned K-distribution was proposed.
More Related Videos
 10:05
Measurement & Analysis of the Temporal Discrimination Threshold Applied to Cervical Dystonia
Published on: January 27, 2018
 09:12
A Quantitative Fluorescence Microscopy-based Single Liposome Assay for Detecting the Compositional Inhomogeneity Between Individual Liposomes
Published on: December 13, 2019
Related Concept Videos
 01:23
Test for Homogeneity
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
On...
 01:26
Distributions to Estimate Population Parameter
 01:14
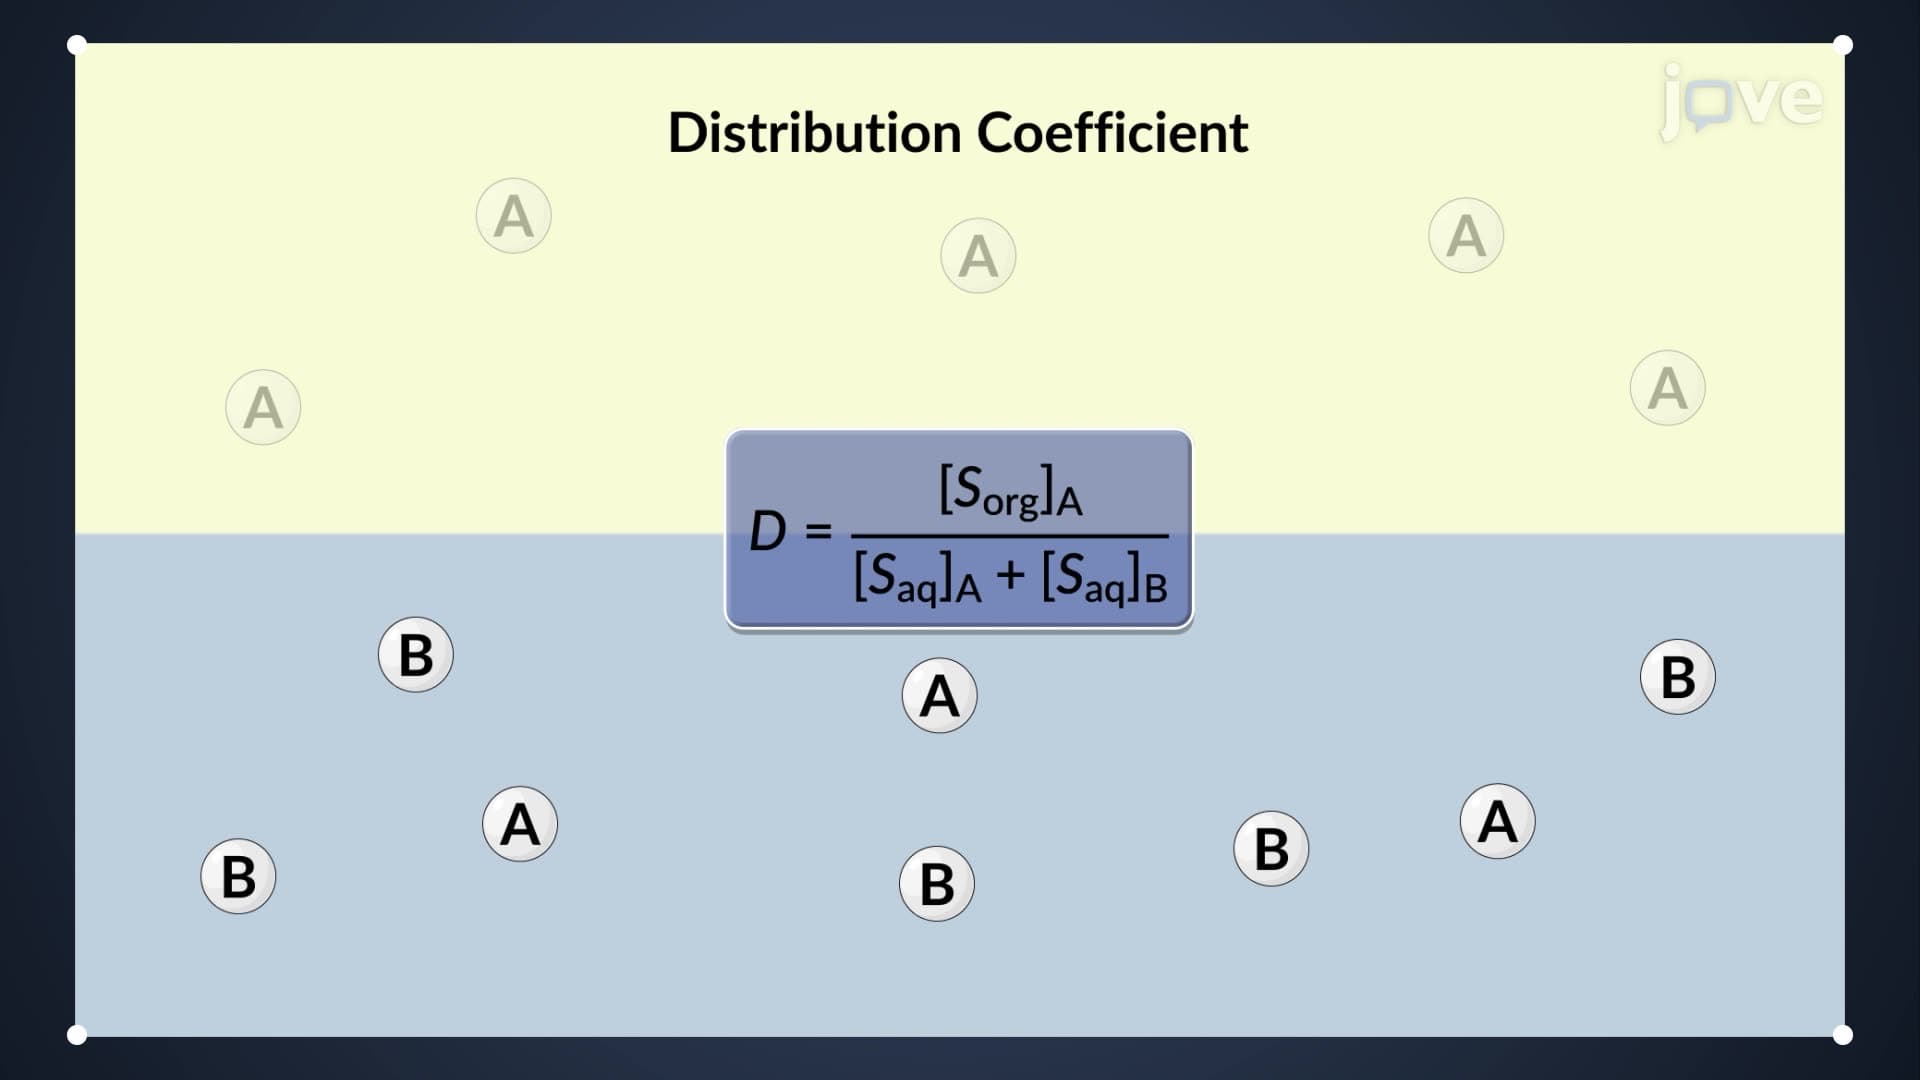
Extraction: Partition and Distribution Coefficients
For extracting a solute from an aqueous phase into an...
 01:25
Choosing Between z and t Distribution
 01:21
Testing a Claim about Mean: Unknown Population SD
Estimating a population mean requires the samples to be approximately normally distributed. The data should be collected from the randomly selected samples having no sampling bias. There is no specific requirement for sample size. But if the sample size is less than 30, and we don't know the population standard deviation, a different approach is used;...