Related Experiment Video
Updated: Apr 19, 2026
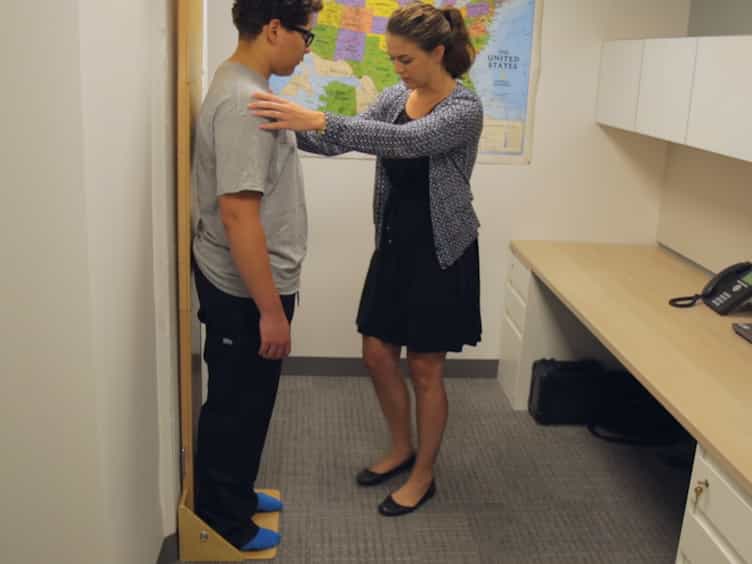

Assessment of Child Anthropometry in a Large Epidemiologic Study
Published on: February 2, 2017
Regional disparities in obesity prevalence in the United States: A spatial regime analysis
Candice A Myers1, Tim Slack, Corby K Martin
1Pennington Biomedical Research Center, Baton Rouge, Louisiana, USA.

Objective:
Significant clusters of high- and low-obesity counties have been demonstrated across the United States (US). This study examined regional disparities in obesity prevalence and differences in the related structural characteristics across regions of the US.
Methods:
Drawing on model-based estimates from the Centers for Disease Control and Prevention, regional differences in county-level adult obesity prevalence (percent of the adult population [≥ 20 years] that was obese [BMI ≥ 30 kg/m(2) ] within a county, 2009) were assessed with a LISA (Local Indicators of Spatial Association) analysis to identify geographic concentrations of high and low obesity levels. Regional regime analysis was utilized to identify factors that were differentially associated with obesity prevalence between regions of the US.
Results:
High- and low-obesity county clusters and the effect of a number of county-level characteristics on obesity prevalence differed significantly by region. These included the positive effect of African American populations in the South, the negative effect of Hispanic populations in the Northeast, and the positive effect of unemployed workers in the Midwest and West.
Conclusions:
Our findings suggest the need for public health policies and interventions that account for different regional characteristics underlying obesity prevalence variation across the US.
Related Concept Videos
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:24
Obesity
 01:52
Regression Toward the Mean
 01:25
Statistical Methods for Analyzing Epidemiological Data
 01:29
Bias in Epidemiological Studies
 01:12
Coefficient of Correlation
If you suspect a linear relationship between x and y, then r can measure how strong the linear relationship is.
What the VALUE of r tells us:
The value of r is always between –1 and +1: –1 ≤ r ≤ 1.
The size of the correlation r indicates the...