Related Experiment Video
Updated: Apr 10, 2026

Transcranial Direct Current Stimulation tDCS of Wernicke's and Broca's Areas in Studies of Language Learning and Word Acquisition
Published on: July 13, 2019
Understanding Zipf's law of word frequencies through sample-space collapse in sentence formation
Stefan Thurner1, Rudolf Hanel2, Bo Liu2
1Section for Science of Complex Systems, CeMSIIS, Medical University of Vienna, Spitalgasse 23, 1090 Vienna, Austria Santa Fe Institute, 1399 Hyde Park Road, Santa Fe, NM 87501, USA IIASA, Schlossplatz 1, 2361 Laxenburg, Austria stefan.thurner@meduniwien.ac.at.

Abstract:
The formation of sentences is a highly structured and history-dependent process. The probability of using a specific word in a sentence strongly depends on the 'history' of word usage earlier in that sentence. We study a simple history-dependent model of text generation assuming that the sample-space of word usage reduces along sentence formation, on average. We first show that the model explains the approximate Zipf law found in word frequencies as a direct consequence of sample-space reduction. We then empirically quantify the amount of sample-space reduction in the sentences of 10 famous English books, by analysis of corresponding word-transition tables that capture which words can follow any given word in a text. We find a highly nested structure in these transition tables and show that this 'nestedness' is tightly related to the power law exponents of the observed word frequency distributions. With the proposed model, it is possible to understand that the nestedness of a text can be the origin of the actual scaling exponent and that deviations from the exact Zipf law can be understood by variations of the degree of nestedness on a book-by-book basis. On a theoretical level, we are able to show that in the case of weak nesting, Zipf's law breaks down in a fast transition. Unlike previous attempts to understand Zipf's law in language the sample-space reducing model is not based on assumptions of multiplicative, preferential or self-organized critical mechanisms behind language formation, but simply uses the empirically quantifiable parameter 'nestedness' to understand the statistics of word frequencies.
More Related Videos
 05:22
Dissociation of the Confounding Influences of Expectancy and Integrative Difficulty Residing in Anomalous Sentences in Event-related Potential Studies
Published on: May 9, 2019
 08:08
Comparing the Frequency Effect Between the Lexical Decision and Naming Tasks in Chinese
Published on: April 1, 2016
Related Concept Videos
 01:15
Sampling Theorem
 01:15
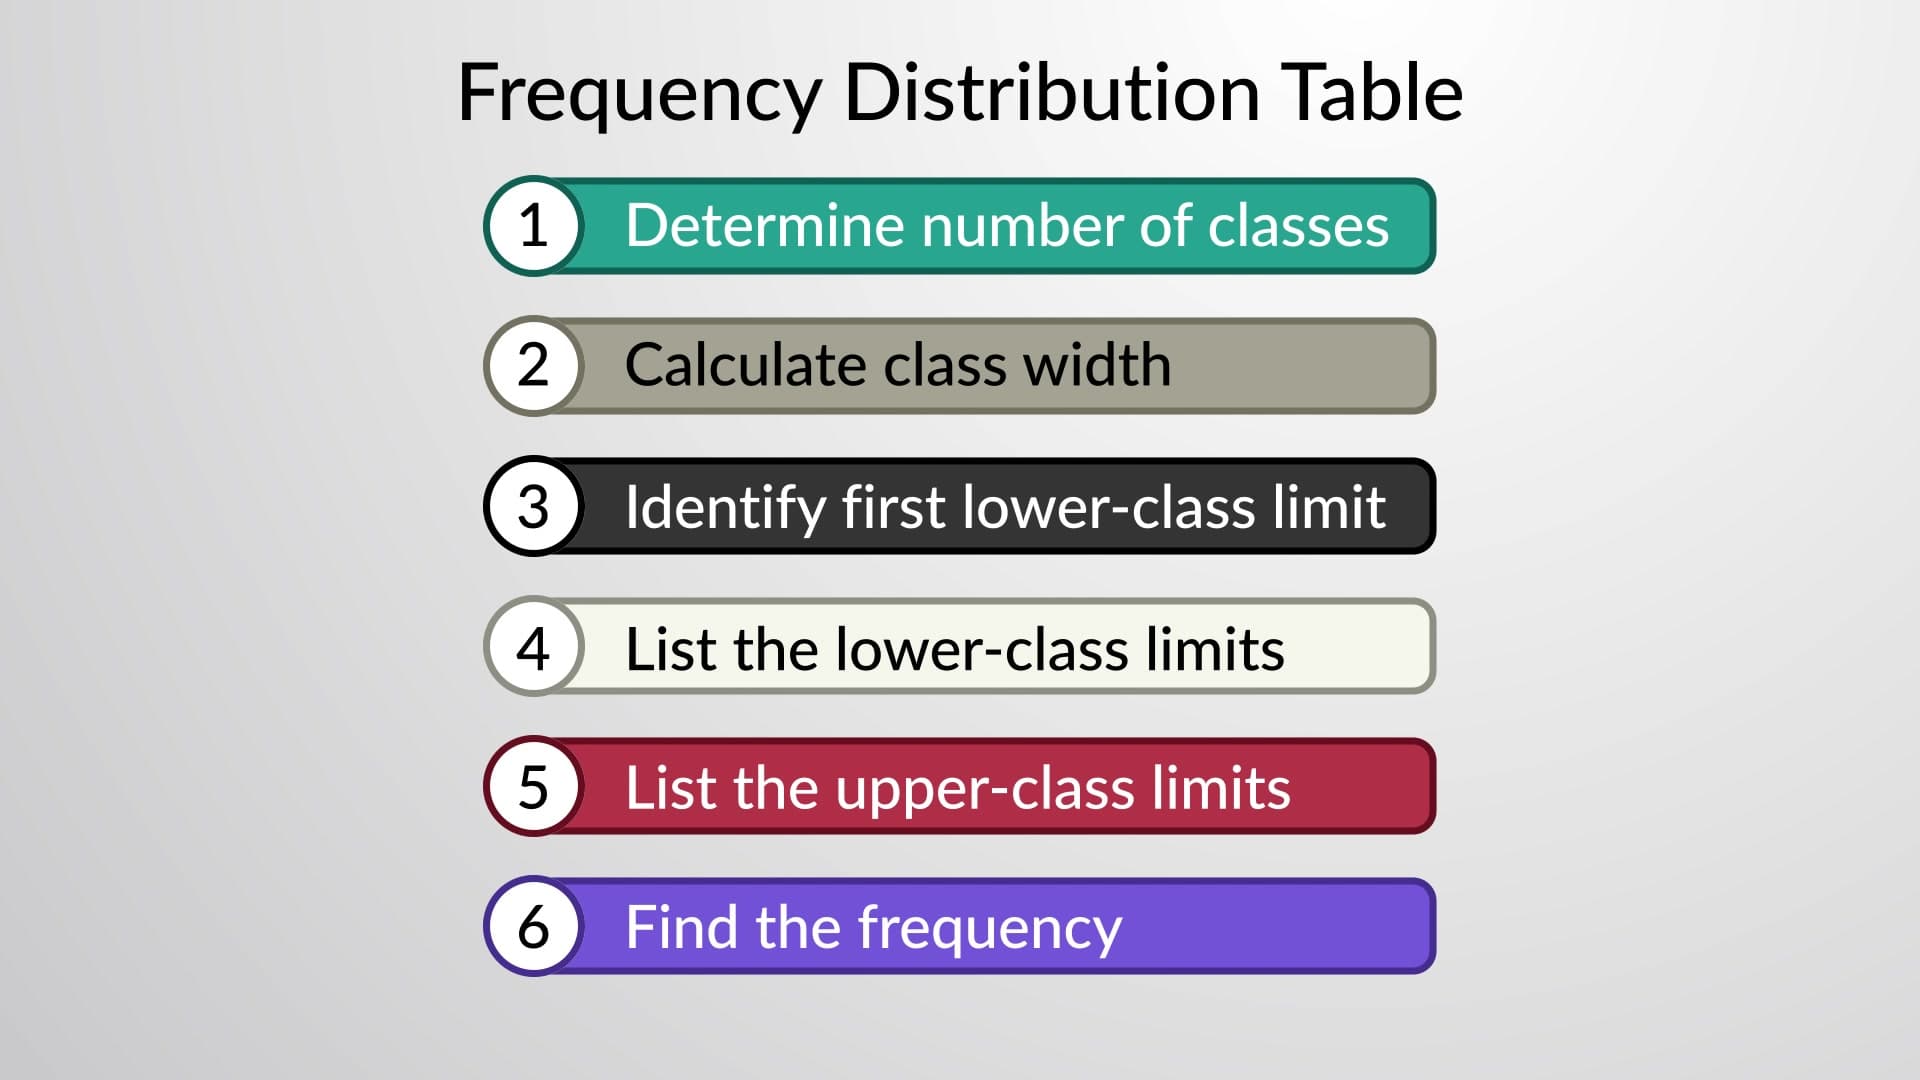
Construction of Frequency Distribution
First, make a table with two columns—one with the title of the data that needs to be organized, and the other column for frequency. [Draw a third column for tally marks if needed]. Then, take a look at the items given in the data set and decide if an ungrouped frequency distribution table or a grouped frequency distribution table would be more suitable. If there are large sets of different values, then it is...
 01:09
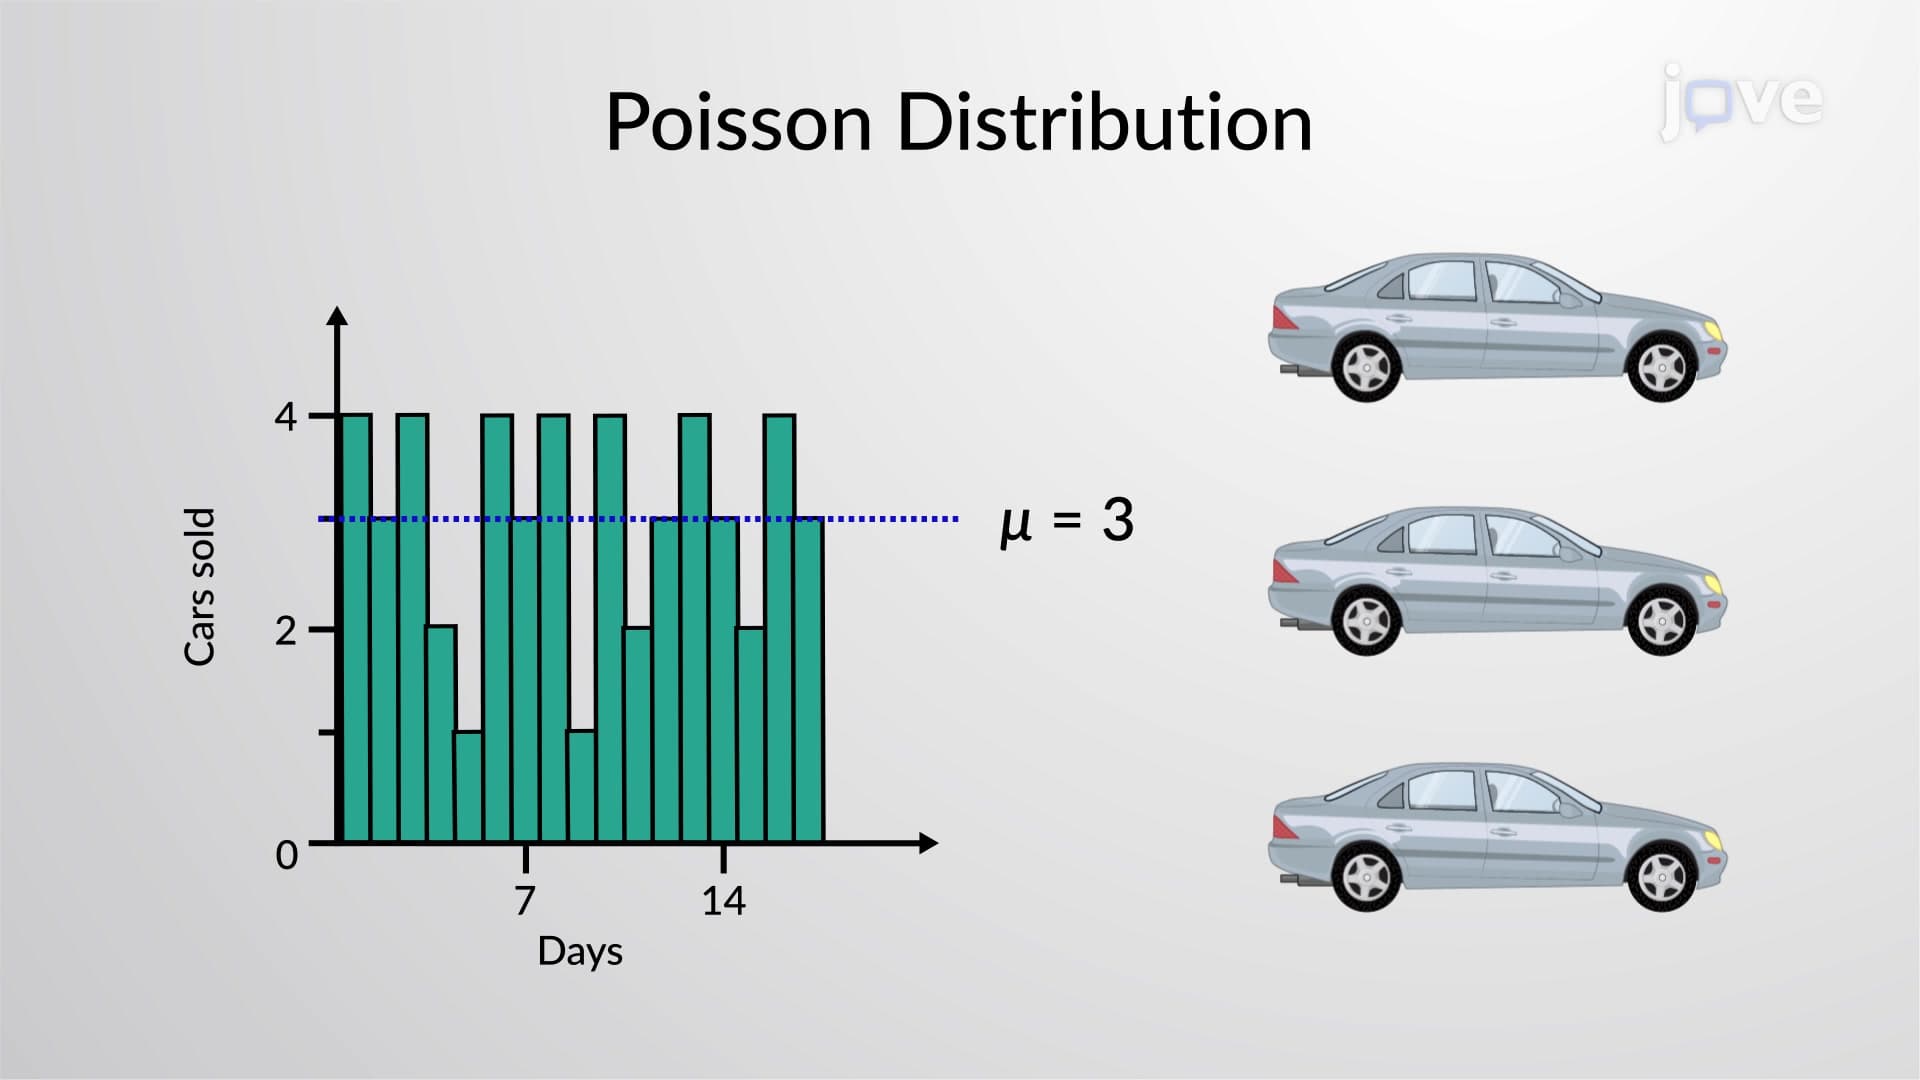
Poisson Probability Distribution
The...
 01:08
Determination of Expected Frequency
 01:19
Expected Frequencies in Goodness-of-Fit Tests
 01:24
Components of Language