Related Experiment Video
Updated: Jan 26, 2026

Non-Destructive Evaluation of Regional Cell Density Within Tumor Aggregates Following Drug Treatment
Published on: June 21, 2022
Boosting drug named entity recognition using an aggregate classifier
Ioannis Korkontzelos1, Dimitrios Piliouras1, Andrew W Dowsey2
1National Centre for Text Mining (NaCTeM), School of Computer Science, The University of Manchester, Manchester Institute of Biotechnology, 131 Princess Street, Manchester M1 7DN, United Kingdom.

Objective:
Drug named entity recognition (NER) is a critical step for complex biomedical NLP tasks such as the extraction of pharmacogenomic, pharmacodynamic and pharmacokinetic parameters. Large quantities of high quality training data are almost always a prerequisite for employing supervised machine-learning techniques to achieve high classification performance. However, the human labour needed to produce and maintain such resources is a significant limitation. In this study, we improve the performance of drug NER without relying exclusively on manual annotations.
Methods:
We perform drug NER using either a small gold-standard corpus (120 abstracts) or no corpus at all. In our approach, we develop a voting system to combine a number of heterogeneous models, based on dictionary knowledge, gold-standard corpora and silver annotations, to enhance performance. To improve recall, we employed genetic programming to evolve 11 regular-expression patterns that capture common drug suffixes and used them as an extra means for recognition.
Materials:
Our approach uses a dictionary of drug names, i.e. DrugBank, a small manually annotated corpus, i.e. the pharmacokinetic corpus, and a part of the UKPMC database, as raw biomedical text. Gold-standard and silver annotated data are used to train maximum entropy and multinomial logistic regression classifiers.
Results:
Aggregating drug NER methods, based on gold-standard annotations, dictionary knowledge and patterns, improved the performance on models trained on gold-standard annotations, only, achieving a maximum F-score of 95%. In addition, combining models trained on silver annotations, dictionary knowledge and patterns are shown to achieve comparable performance to models trained exclusively on gold-standard data. The main reason appears to be the morphological similarities shared among drug names.
Conclusion:
We conclude that gold-standard data are not a hard requirement for drug NER. Combining heterogeneous models build on dictionary knowledge can achieve similar or comparable classification performance with that of the best performing model trained on gold-standard annotations.
Related Concept Videos
 02:21
Naming Enantiomers
 03:35
Classifying Matter by Composition
According to its composition, the matter can be classified into two broad categories — pure substances and mixtures.
A pure substance is a form of matter that has a constant composition throughout with uniform properties. For example, any sample of sucrose has the same composition and same physical properties, such as melting point, color, and sweetness, regardless of the source from which it is isolated.
A mixture is composed of two or...
 01:19
Naming Skeletal Muscles
The key factors used in naming muscles include:
 02:49
Classifying Matter by State
 01:11
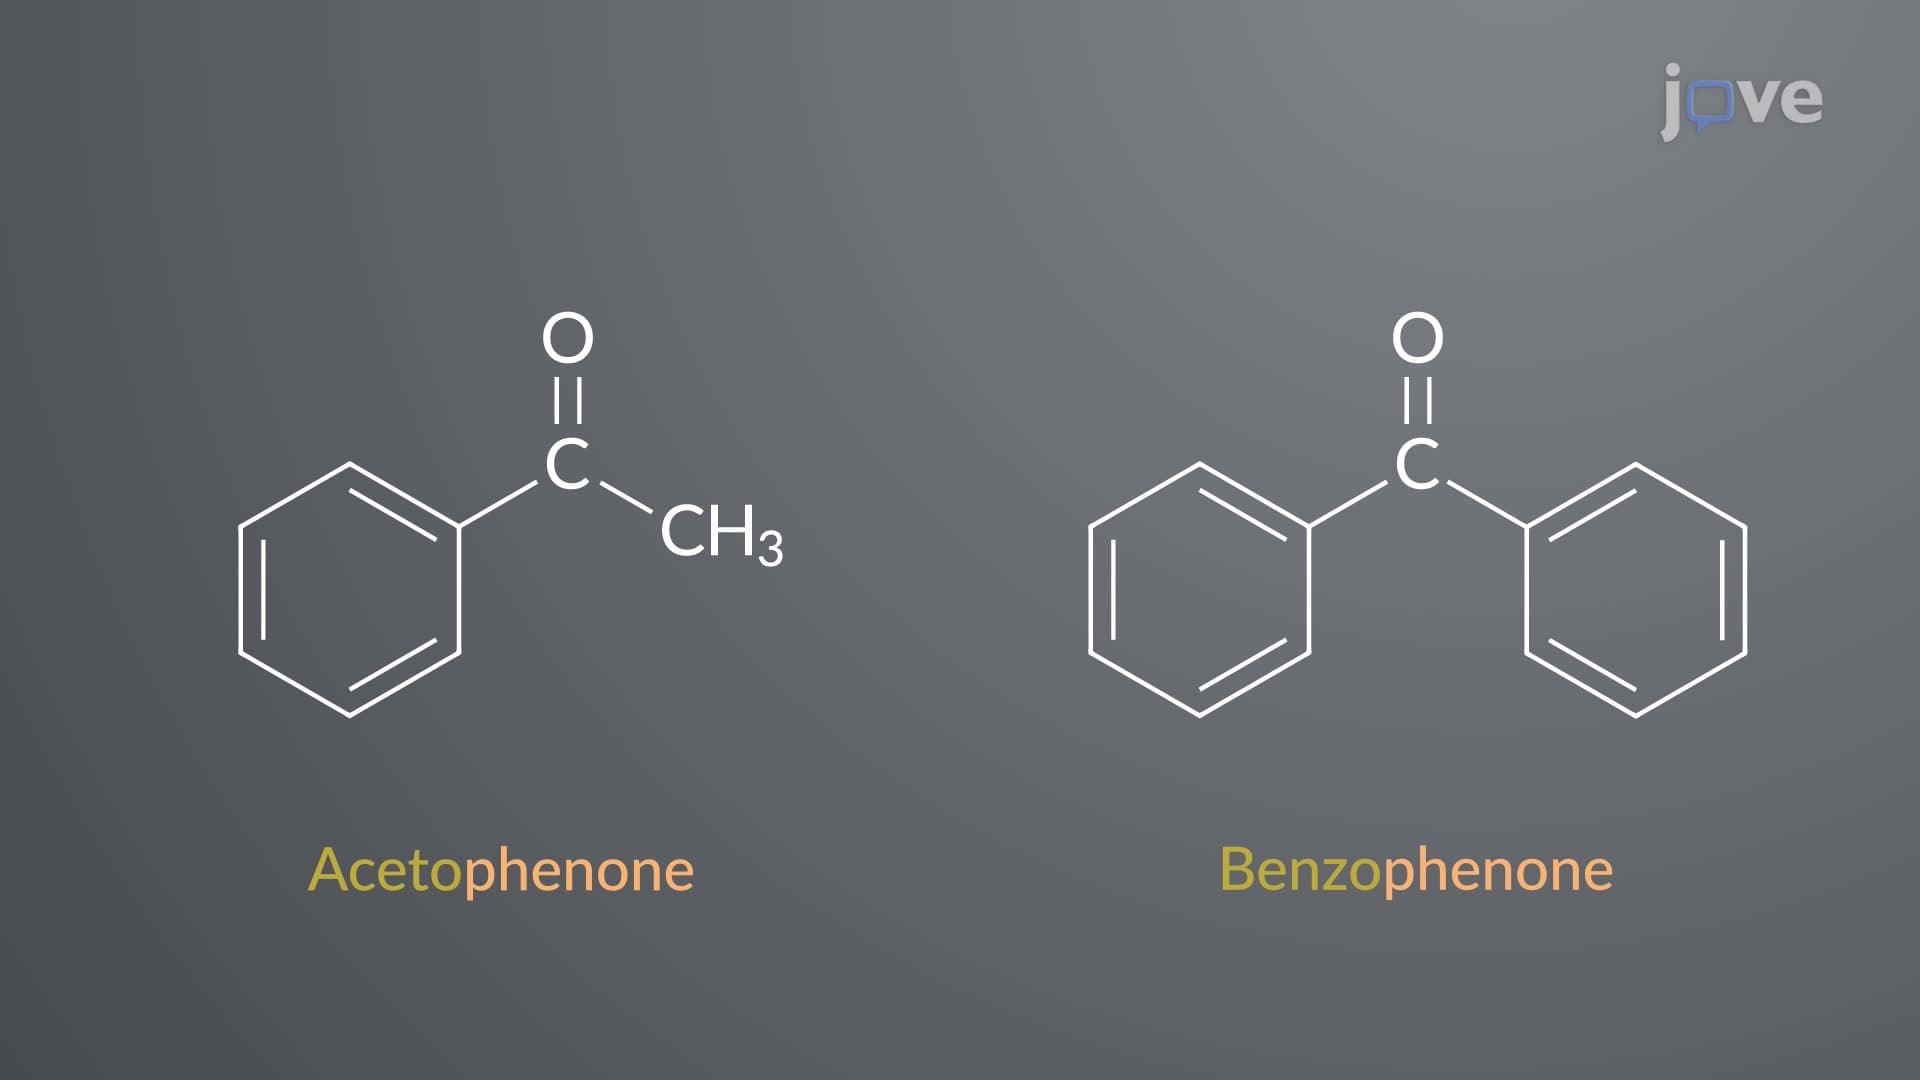
Common Names of Aldehydes and Ketones
Common names of aldehydes are derived from the names of their corresponding acid. For instance, the two-carbon aldehyde–acetaldehyde derives its name from the corresponding acid–acetic acid. Similarly, formaldehyde derives its name from formic acid and benzaldehyde from benzoic acid.
Aliphatic ketones are named by suffixing the word “ketone” to the...
 00:59
How Data are Classified: Numerical Data
Quantitative data may be either discrete or continuous. All quantitative data that take on only specific numerical...