Related Experiment Video
Updated: Apr 7, 2026
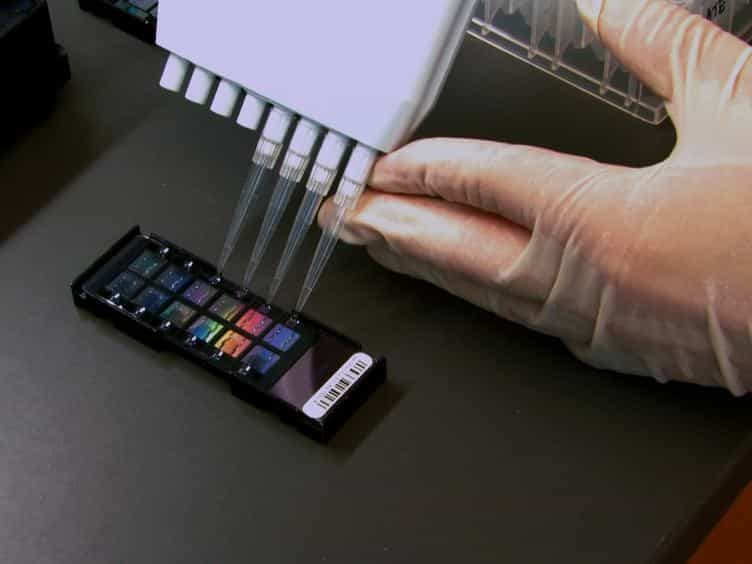

Infinium Assay for Large-scale SNP Genotyping Applications
Published on: November 19, 2013
Scanning and Filling: Ultra-Dense SNP Genotyping Combining Genotyping-By-Sequencing, SNP Array and Whole-Genome
Davoud Torkamaneh1, Francois Belzile1
1Département de Phytologie and Institut de Biologie Intégrative et des Systèmes (IBIS), Université Laval, Quebec City, QC, Canada.

Abstract:
Genotyping-by-sequencing (GBS) represents a highly cost-effective high-throughput genotyping approach. By nature, however, GBS is subject to generating sizeable amounts of missing data and these will need to be imputed for many downstream analyses. The extent to which such missing data can be tolerated in calling SNPs has not been explored widely. In this work, we first explore the use of imputation to fill in missing genotypes in GBS datasets. Importantly, we use whole genome resequencing data to assess the accuracy of the imputed data. Using a panel of 301 soybean accessions, we show that over 62,000 SNPs could be called when tolerating up to 80% missing data, a five-fold increase over the number called when tolerating up to 20% missing data. At all levels of missing data examined (between 20% and 80%), the resulting SNP datasets were of uniformly high accuracy (96-98%). We then used imputation to combine complementary SNP datasets derived from GBS and a SNP array (SoySNP50K). We thus produced an enhanced dataset of >100,000 SNPs and the genotypes at the previously untyped loci were again imputed with a high level of accuracy (95%). Of the >4,000,000 SNPs identified through resequencing 23 accessions (among the 301 used in the GBS analysis), 1.4 million tag SNPs were used as a reference to impute this large set of SNPs on the entire panel of 301 accessions. These previously untyped loci could be imputed with around 90% accuracy. Finally, we used the 100K SNP dataset (GBS + SoySNP50K) to perform a GWAS on seed oil content within this collection of soybean accessions. Both the number of significant marker-trait associations and the peak significance levels were improved considerably using this enhanced catalog of SNPs relative to a smaller catalog resulting from GBS alone at ≤20% missing data. Our results demonstrate that imputation can be used to fill in both missing genotypes and untyped loci with very high accuracy and that this leads to more powerful genetic analyses.
Related Concept Videos
 03:00
Next-generation Sequencing
Next-Generation Sequencing Methods
Although all next-generation methods use different technologies, they all share a set of standard features....
 01:11
Genome-wide Association Studies-GWAS
GWAS does not require the identification of the target gene involved in...
 01:05
Single Nucleotide Polymorphisms-SNPs
 01:57
Sanger Sequencing
 03:21
RNA-seq
Before the discovery of RNA-seq, microarray-based methods and Sanger sequencing were used for transcriptome analysis. However, while...