Related Experiment Video
Updated: Mar 27, 2026
Applying an eMASS Customization Program as a Research Tool to Evaluate Consumer Benefits
Published on: September 27, 2019
Abstract: Evaluation of Test Statistics for Robust Structural Equation Modeling With Nonnormal Missing Data
Xin Tong1, Zhiyong Zhang1, Ke-Hai Yuan1
1a Department of Psychology , University of Notre Dame.

Abstract:
Traditional structural equation modeling (SEM) techniques have trouble dealing with incomplete and/or nonnormal data that are often encountered in practice. Yuan and Zhang (2011a) developed a two-stage procedure for SEM to handle nonnormal missing data and proposed four test statistics for overall model evaluation. Although these statistics have been shown to work well with complete data, their performance for incomplete data has not been investigated in the context of robust statistics. Focusing on a linear growth curve model, a systematic simulation study is conducted to evaluate the accuracy of the parameter estimates and the performance of five test statistics including the naive statistic derived from normal distribution based maximum likelihood (ML), the Satorra-Bentler scaled chi-square statistic (RML), the mean- and variance-adjusted chi-square statistic (AML), Yuan-Bentler residual-based test statistic (CRADF), and Yuan-Bentler residual-based F statistic (RF). Data are generated and analyzed in R using the package rsem (Yuan & Zhang, 2011b). Based on the simulation study, we can observe the following: (a) The traditional normal distribution-based method cannot yield accurate parameter estimates for nonnormal data, whereas the robust method obtains much more accurate model parameter estimates for nonnormal data and performs almost as well as the normal distribution based method for normal distributed data. (b) With the increase of sample size, or the decrease of missing rate or the number of outliers, the parameter estimates are less biased and the empirical distributions of test statistics are closer to their nominal distributions. (c) The ML test statistic does not work well for nonnormal or missing data. (d) For nonnormal complete data, CRADF and RF work relatively better than RML and AML. (e) For missing completely at random (MCAR) missing data, in almost all the cases, RML and AML work better than CRADF and RF. (f) For nonnormal missing at random (MAR) missing data, CRADF and RF work better than AML. (g) The performance of the robust method does not seem to be influenced by the symmetry of outliers.
More Related Videos
 04:35
Development of an Individual-Tree Basal Area Increment Model using a Linear Mixed-Effects Approach
Published on: July 3, 2020
 09:00
Author Spotlight: Validation of SICOLE-R for Assessing Cognitive and Reading Skills in Spanish-Speaking Children and Its Role in Personalized Education
Published on: August 16, 2024
Related Concept Videos
 01:09
Statistical Methods to Analyze Parametric Data: Student t-Test and Goodness-of-Fit Test
The Student's t-test is a statistical test that examines if there is a statistically significant difference between the means of two groups. This test is instrumental when dealing with...
 01:19
Expected Frequencies in Goodness-of-Fit Tests
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...
 01:28
Introduction to Nonparametric Statistics
One of...
 01:16
Goodness-of-Fit Test
 01:12
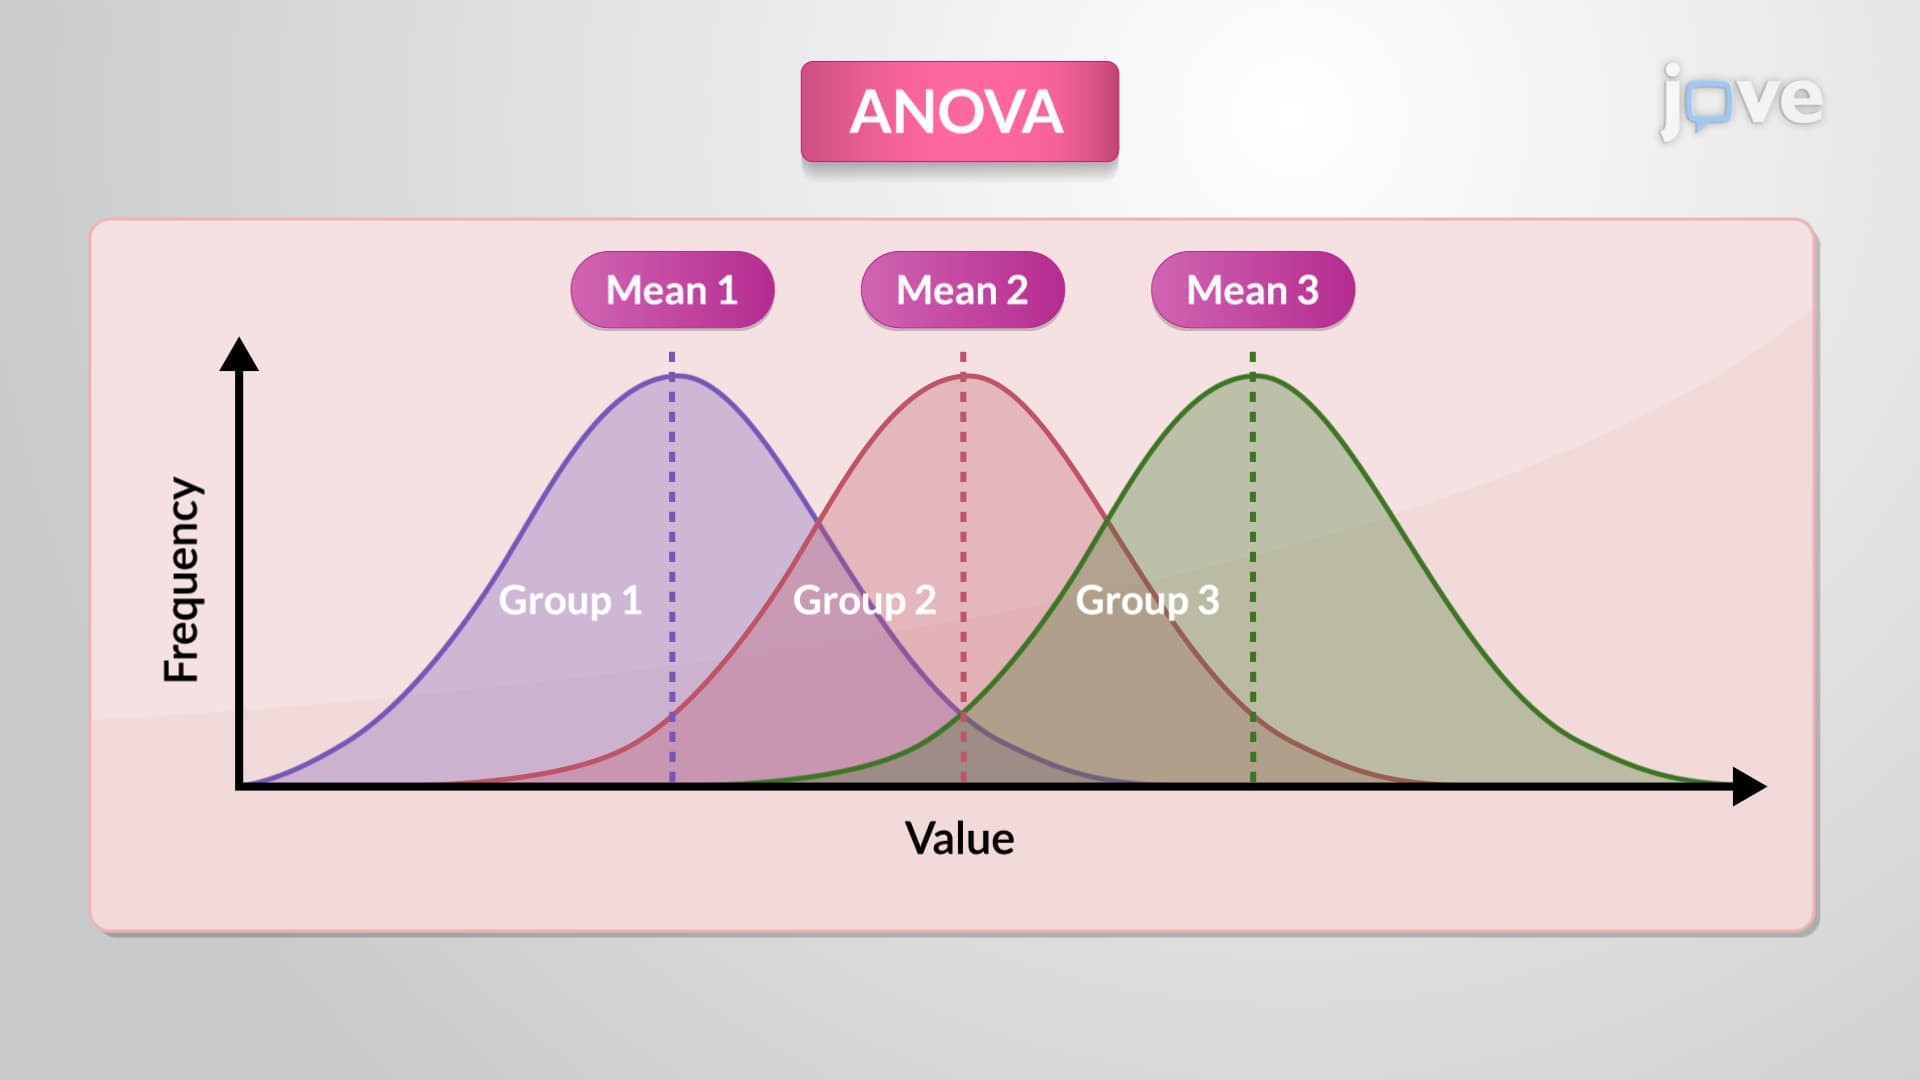
Statistical Methods to Analyze Parametric Data: ANOVA
One-way ANOVA is applied when a single independent variable or factor is scrutinized. It compares...