Understanding covariate shift in model performance

Georgia McGaughey1, W Patrick Walters1, Brian Goldman1

  • 1Modeling & Informatics, Vertex Pharmaceuticals, Boston, MA, USA.

F1000Research
|November 5, 2016
PubMed

Related Concept Videos

Regression Toward the Mean01:52

Regression Toward the Mean

Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
7.3K
Friedman Two-way Analysis of Variance by Ranks01:21

Friedman Two-way Analysis of Variance by Ranks

Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
531
Expected Frequencies in Goodness-of-Fit Tests01:19

Expected Frequencies in Goodness-of-Fit Tests

A goodness-of-fit test is conducted to determine whether the observed frequency values are statistically similar to the frequencies expected for the dataset. Suppose the expected frequencies for a dataset are equal such as when predicting the frequency of any number appearing when casting a die. In that case, the expected frequency is the ratio of the total number of observations (n)  to the number of categories (k).
8.8K
Variability: Analysis01:11

Variability: Analysis

Measures of variability are statistical metrics that reveal the dispersion pattern within a dataset. They are pivotal in biostatistics, providing insights into the heterogeneity within health and biological data. Variability signifies the degree to which data points diverge from one another, helping researchers understand the potential range of values and associated uncertainty within the data.
The range is a simple measure of variability, indicating the difference between the highest and...
609
Contingency Table01:29

Contingency Table

A contingency table provides a way of portraying data that can facilitate calculating probabilities. It is a method of displaying a frequency distribution as a table with rows and columns to show how two variables may be dependent (contingent) upon each other; The table helps determine conditional probabilities quite quickly and can help systematically organize, analyze and quantify data. The table displays sample values concerning two variables that may be dependent or contingent on one...
4.7K
Variation01:19

Variation

An important characteristic of any set of data is the variation in the data. In some data sets, the data values are concentrated closely near the mean; in other data sets, the data values are more widely spread out from the mean. The most common measure of variation, or spread, is the standard deviation, which is the square root of variance.
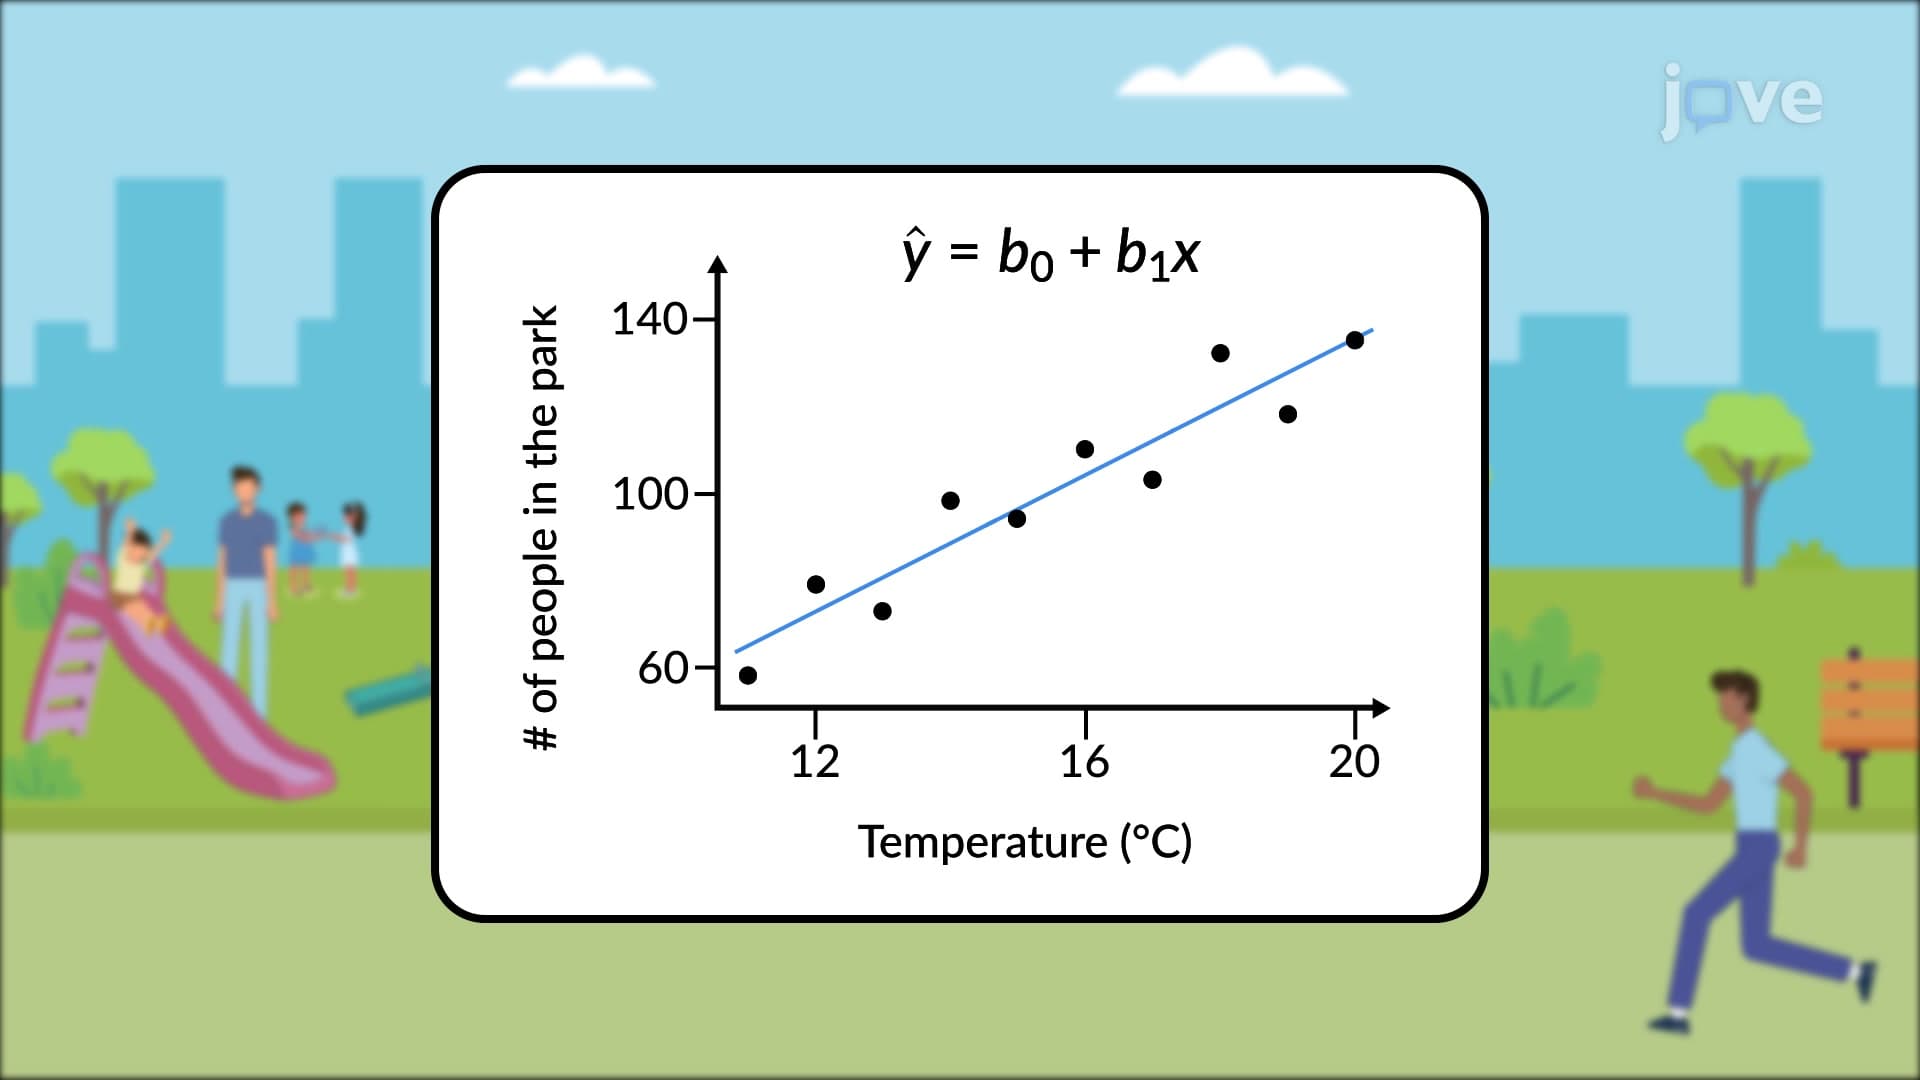
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
8.2K