Local clustering in scale-free networks with hidden variables
Remco van der Hofstad1, A J E M Janssen1, Johan S H van Leeuwaarden1
1Department of Mathematics and Computer Science, Eindhoven University of Technology, P.O. Box 513, 5600MB Eindhoven, The Netherlands.

Abstract:
We investigate the presence of triangles in a class of correlated random graphs in which hidden variables determine the pairwise connections between vertices. The class rules out self-loops and multiple edges. We focus on the regime where the hidden variables follow a power law with exponent τ∈(2,3), so that the degrees have infinite variance. The natural cutoff h_{c} characterizes the largest degrees in the hidden variable models, and a structural cutoff h_{s} introduces negative degree correlations (disassortative mixing) due to the infinite-variance degrees. We show that local clustering decreases with the hidden variable (or degree). We also determine how the average clustering coefficient C scales with the network size N, as a function of h_{s} and h_{c}. For scale-free networks with exponent 2<τ<3 and the default choices h_{s}∼N^{1/2} and h_{c}∼N^{1/(τ-1)} this gives C∼N^{2-τ}lnN for the universality class at hand. We characterize the extremely slow decay of C when τ≈2 and show that for τ=2.1, say, clustering starts to vanish only for networks as large as N=10^{9}.
Related Concept Videos
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:08
Outliers and Influential Points
 01:23
Sampling Plans
Random sampling is a method where each member of the population has an equal chance of being selected for the sample. It involves selecting individuals randomly, often using random number generators or lottery-type methods. For example, when analyzing the properties of a...
 01:09
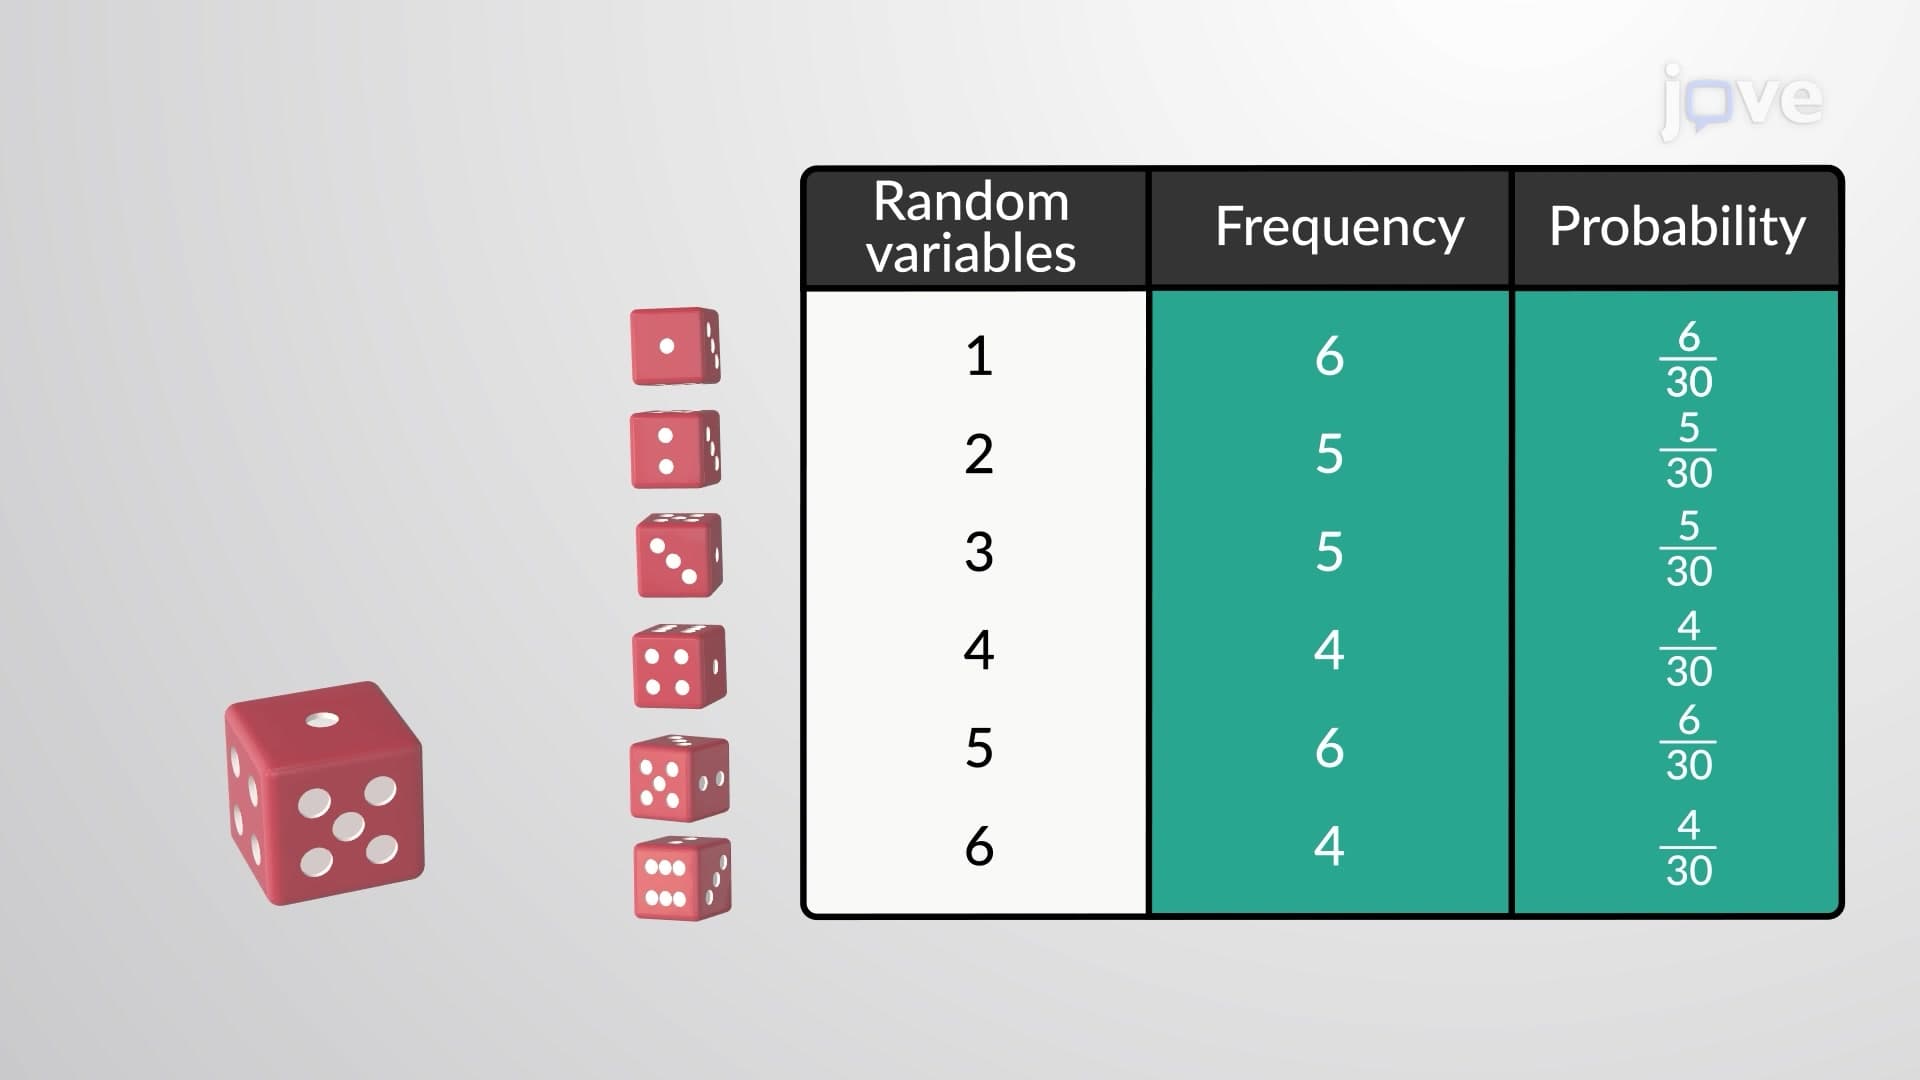
Random Variables
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:11
Variability: Analysis
The range is a simple measure of variability, indicating the difference between the highest and...