Related Experiment Video
Updated: Feb 28, 2026

A Multimodal Wide-Field Fourier-Transform Raman Microscope
Published on: December 30, 2025
Random subsets of structured deterministic frames have MANOVA spectra
Marina Haikin1, Ram Zamir1, Matan Gavish2
1School of Electrical Engineering, Systems Department, Tel Aviv University, Tel Aviv 6997801, Israel.

Abstract:
We draw a random subset of [Formula: see text] rows from a frame with [Formula: see text] rows (vectors) and [Formula: see text] columns (dimensions), where [Formula: see text] and [Formula: see text] are proportional to [Formula: see text] For a variety of important deterministic equiangular tight frames (ETFs) and tight non-ETFs, we consider the distribution of singular values of the [Formula: see text]-subset matrix. We observe that, for large [Formula: see text], they can be precisely described by a known probability distribution-Wachter's MANOVA (multivariate ANOVA) spectral distribution, a phenomenon that was previously known only for two types of random frames. In terms of convergence to this limit, the [Formula: see text]-subset matrix from all of these frames is shown to be empirically indistinguishable from the classical MANOVA (Jacobi) random matrix ensemble. Thus, empirically, the MANOVA ensemble offers a universal description of the spectra of randomly selected [Formula: see text] subframes, even those taken from deterministic frames. The same universality phenomena is shown to hold for notable random frames as well. This description enables exact calculations of properties of solutions for systems of linear equations based on a random choice of [Formula: see text] frame vectors of [Formula: see text] possible vectors and has a variety of implications for erasure coding, compressed sensing, and sparse recovery. When the aspect ratio [Formula: see text] is small, the MANOVA spectrum tends to the well-known Marčenko-Pastur distribution of the singular values of a Gaussian matrix, in agreement with previous work on highly redundant frames. Our results are empirical, but they are exhaustive, precise, and fully reproducible.

Related Concept Videos
 01:21
Friedman Two-way Analysis of Variance by Ranks
 01:09
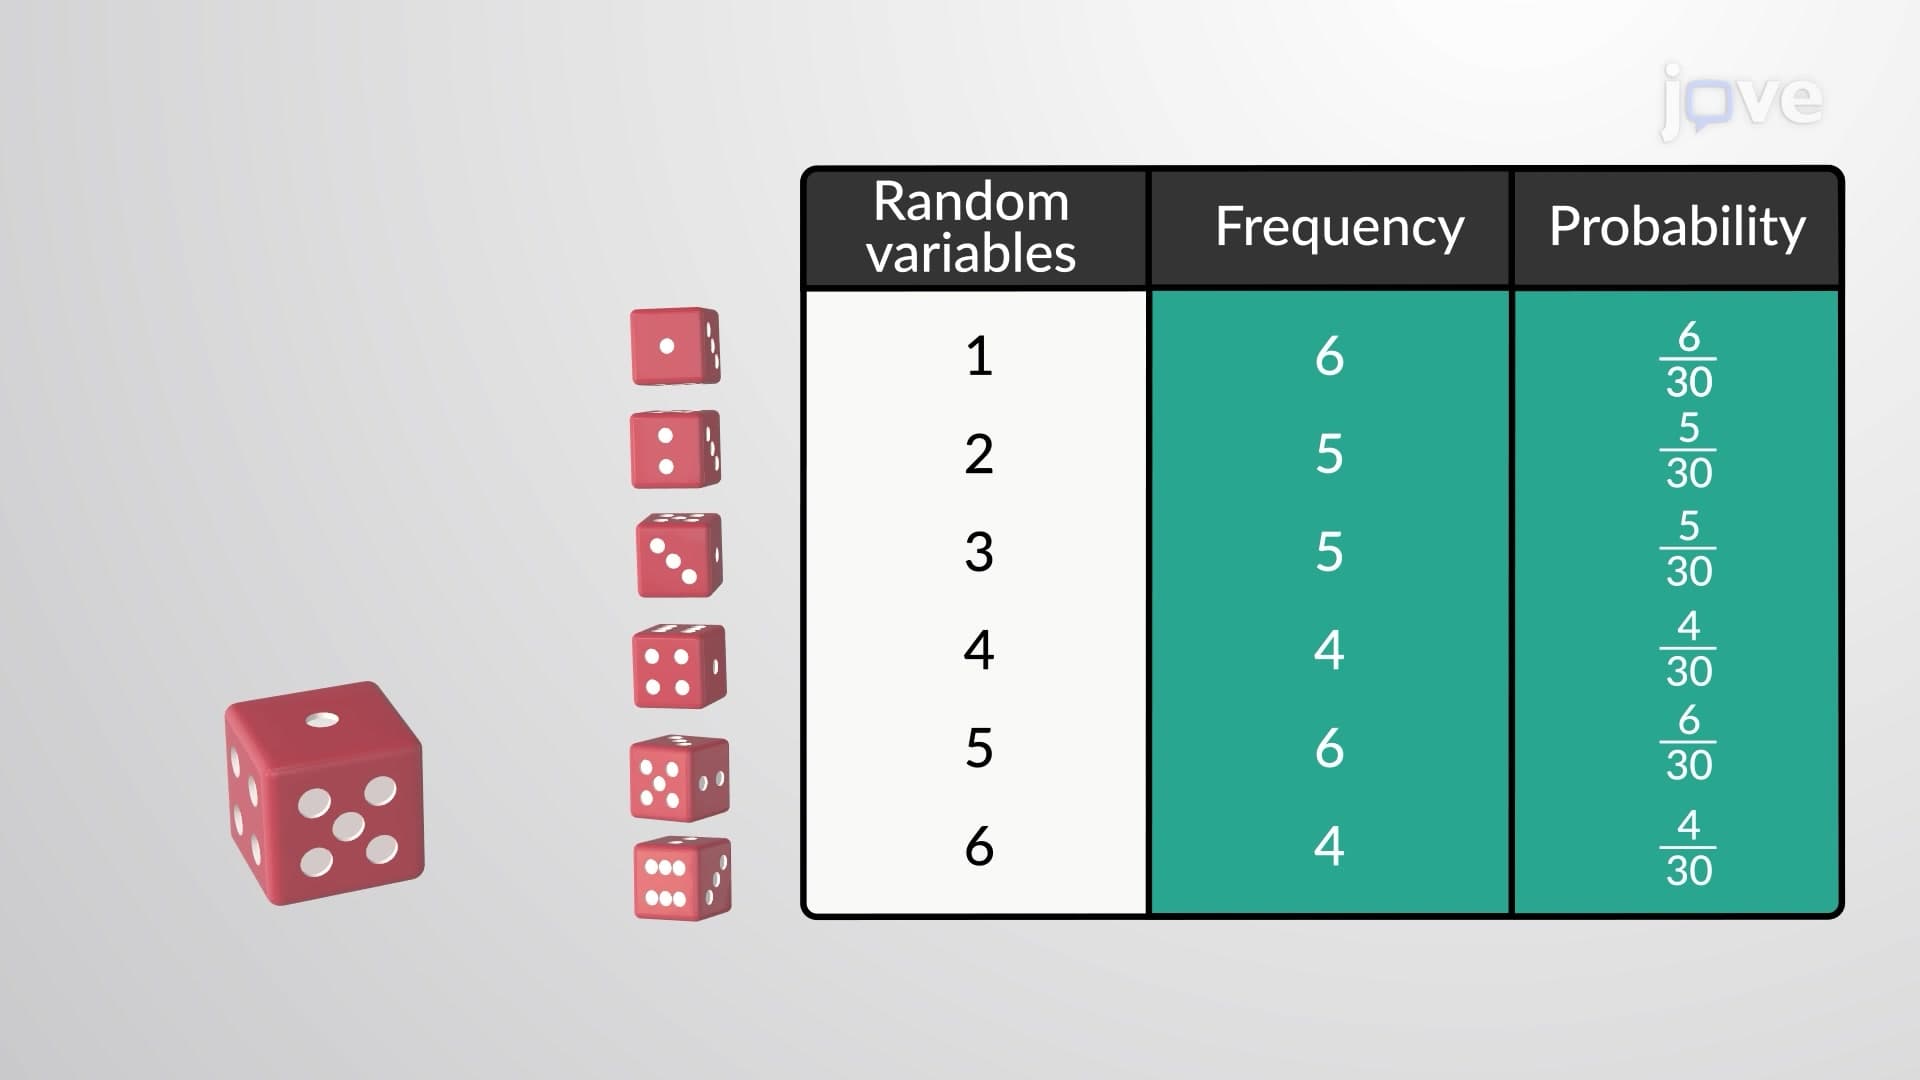
Random Variables
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
 01:11
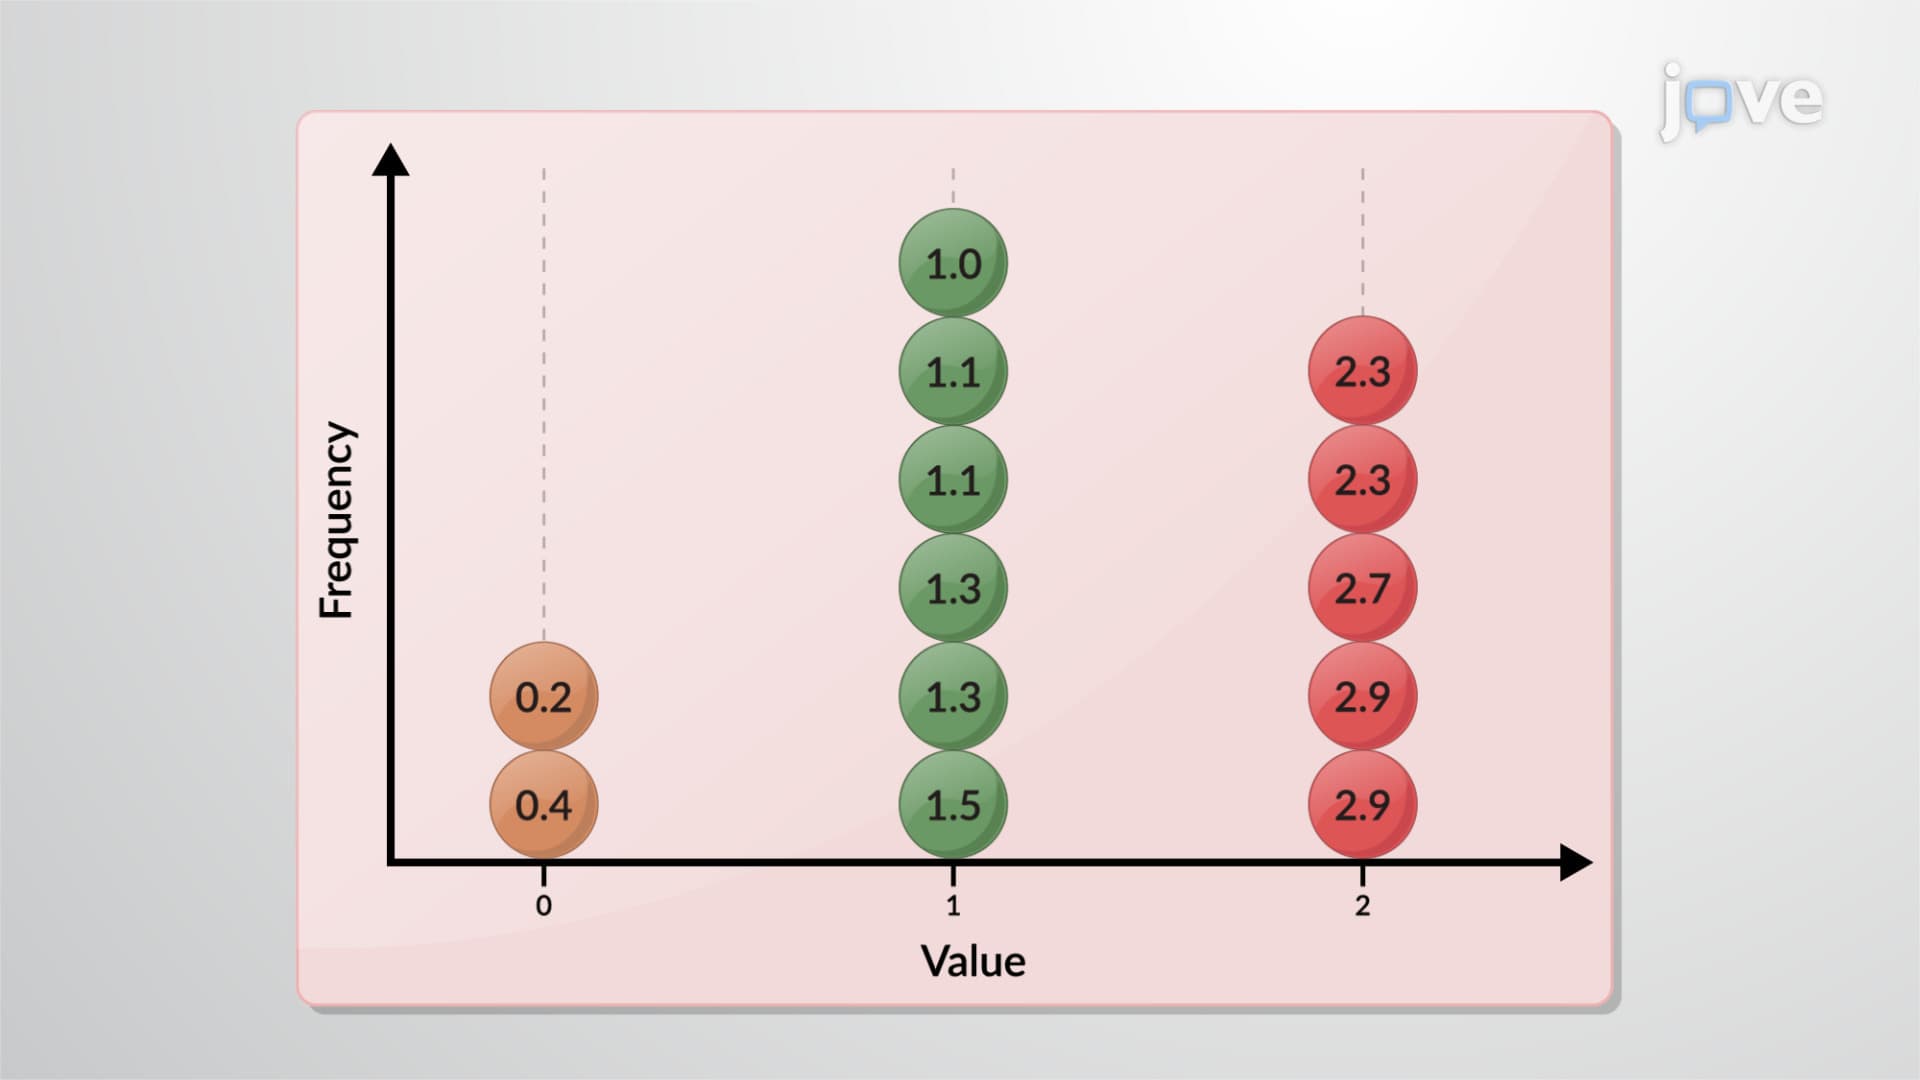
Variability: Analysis
The range is a simple measure of variability, indicating the difference between the highest and...
 01:08
Determination of Expected Frequency
 01:19
Expected Frequencies in Goodness-of-Fit Tests
 01:02
¹H NMR: Interpreting Distorted and Overlapping Signals
As Δν decreases and the signals move closer, the doublets appear increasingly distorted. The intensities of the inner lines increase at the cost of those of the outer lines as the signals are...