Related Experiment Video
Updated: Feb 28, 2026

SUMO-Binding Entities SUBEs as Tools for the Enrichment, Isolation, Identification, and Characterization of the SUMO Proteome in Liver Cancer
Published on: November 1, 2019
DrugSemantics: A corpus for Named Entity Recognition in Spanish Summaries of Product Characteristics
Isabel Moreno1, Ester Boldrini1, Paloma Moreda1
1Department of Software and Computing Systems, University of Alicante, Alicante, Spain.

Abstract:
For the healthcare sector, it is critical to exploit the vast amount of textual health-related information. Nevertheless, healthcare providers have difficulties to benefit from such quantity of data during pharmacotherapeutic care. The problem is that such information is stored in different sources and their consultation time is limited. In this context, Natural Language Processing techniques can be applied to efficiently transform textual data into structured information so that it could be used in critical healthcare applications, being of help for physicians in their daily workload, such as: decision support systems, cohort identification, patient management, etc. Any development of these techniques requires annotated corpora. However, there is a lack of such resources in this domain and, in most cases, the few ones available concern English. This paper presents the definition and creation of DrugSemantics corpus, a collection of Summaries of Product Characteristics in Spanish. It was manually annotated with pharmacotherapeutic named entities, detailed in DrugSemantics annotation scheme. Annotators were a Registered Nurse (RN) and two students from the Degree in Nursing. The quality of DrugSemantics corpus has been assessed by measuring its annotation reliability (overall F=79.33% [95%CI: 78.35-80.31]), as well as its annotation precision (overall P=94.65% [95%CI: 94.11-95.19]). Besides, the gold-standard construction process is described in detail. In total, our corpus contains more than 2000 named entities, 780 sentences and 226,729 tokens. Last, a Named Entity Classification module trained on DrugSemantics is presented aiming at showing the quality of our corpus, as well as an example of how to use it.
More Related Videos
 07:50
A Metadata Extraction Approach for Clinical Case Reports to Enable Advanced Understanding of Biomedical Concepts
Published on: September 20, 2018
 09:20
Cloud-Based Phrase Mining and Analysis of User-Defined Phrase-Category Association in Biomedical Publications
Published on: February 23, 2019
Related Concept Videos
 01:17
Drug Nomenclature
 02:27
Predicting Products: SN1 vs. SN2
With increased substitution on the alkyl halide,...
 01:23
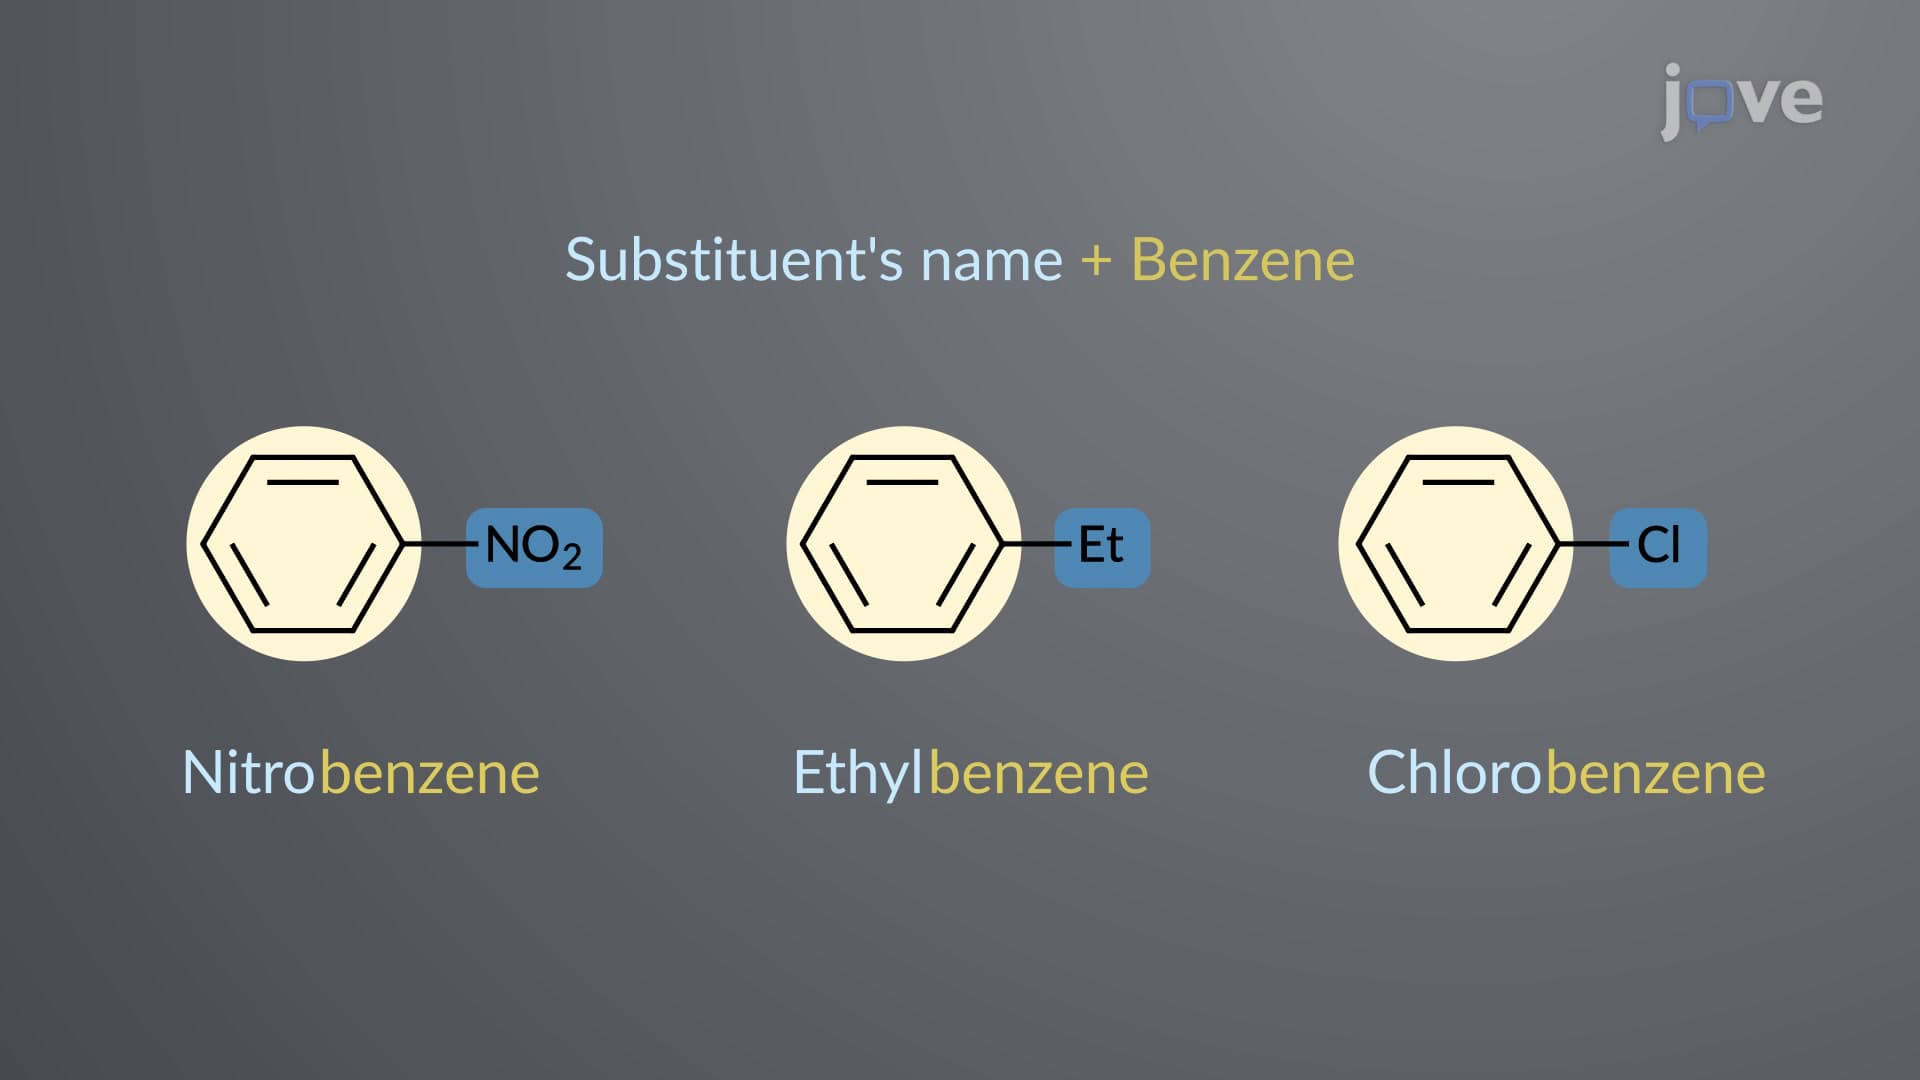
Nomenclature of Aromatic Compounds with a Single Substituent
 02:52
Predicting Products: Substitution vs. Elimination
The following factors can influence the mechanisms competing against each other:
 01:11
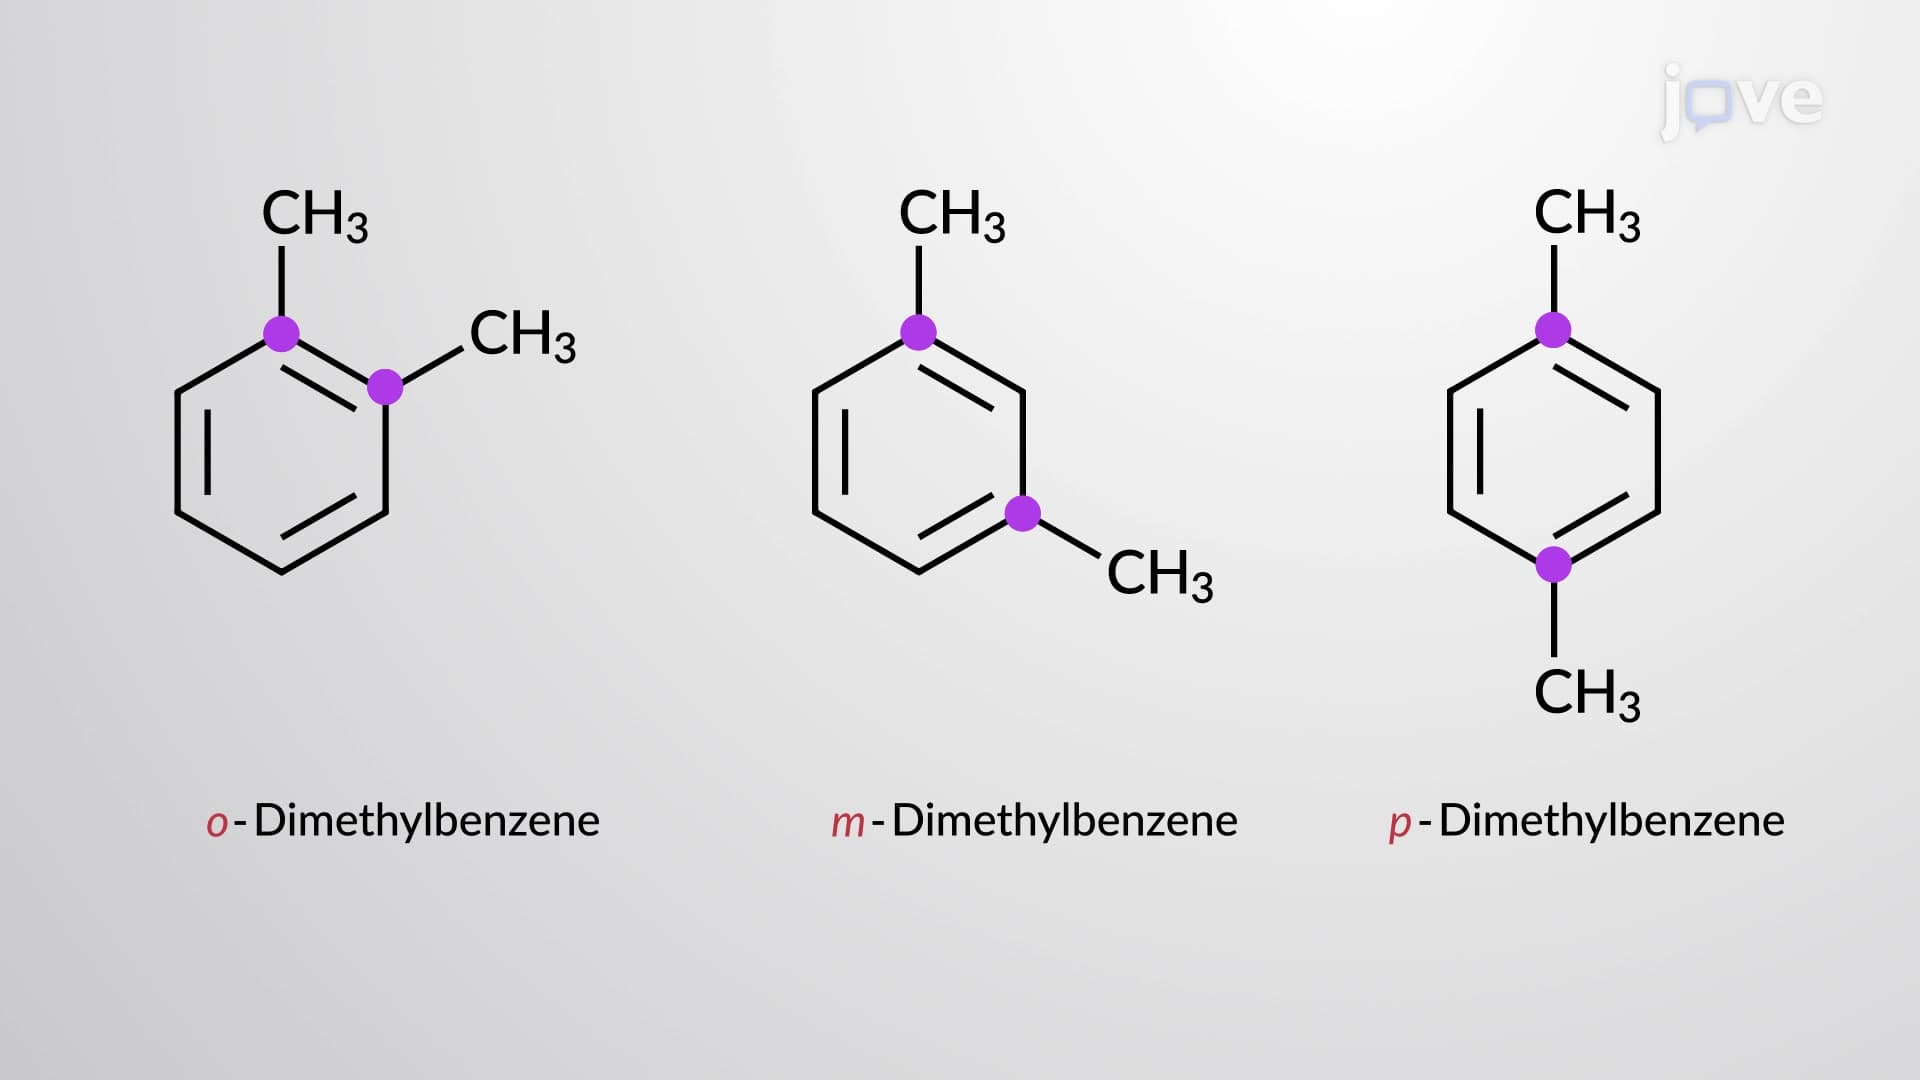
Nomenclature of Aromatic Compounds with Multiple Substituents
For disubstituted benzene derivatives, with two groups attached to the benzene ring, three constitutional isomers are possible. For example, consider dimethyl benzene, often called xylene, where the second methyl group can be substituted at the second, third, or fourth carbon. The relative position of the substituents is represented by prefixes ortho, meta, or...
 02:21
Naming Enantiomers