Related Experiment Video
Updated: Feb 27, 2026
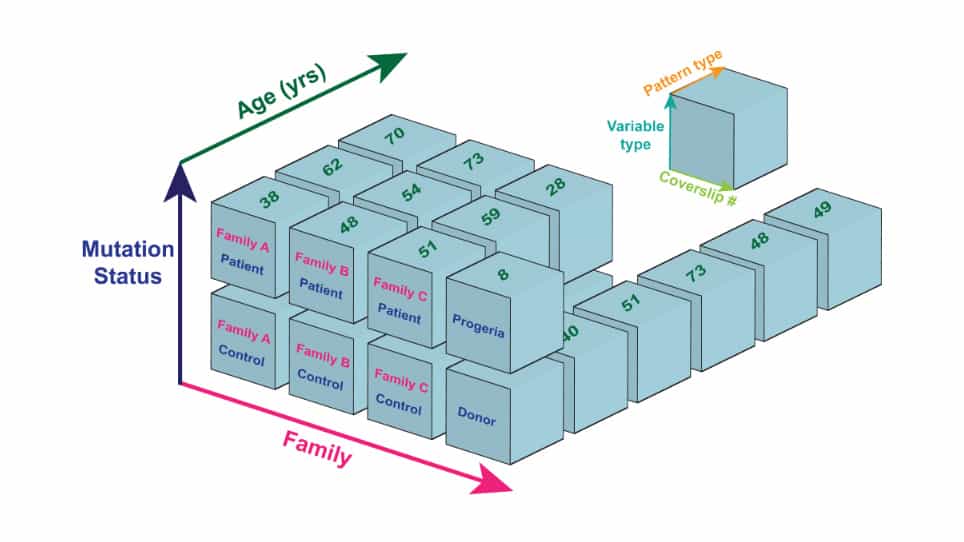

Databases to Efficiently Manage Medium Sized, Low Velocity, Multidimensional Data in Tissue Engineering
Published on: November 22, 2019
Identifiers for the 21st century: How to design, provision, and reuse persistent identifiers to maximize utility and
Julie A McMurry1, Nick Juty2, Niklas Blomberg3
1Department of Medical Informatics and Epidemiology and OHSU Library, Oregon Health & Science University, Portland, Oregon, United States of America.

Abstract:
In many disciplines, data are highly decentralized across thousands of online databases (repositories, registries, and knowledgebases). Wringing value from such databases depends on the discipline of data science and on the humble bricks and mortar that make integration possible; identifiers are a core component of this integration infrastructure. Drawing on our experience and on work by other groups, we outline 10 lessons we have learned about the identifier qualities and best practices that facilitate large-scale data integration. Specifically, we propose actions that identifier practitioners (database providers) should take in the design, provision and reuse of identifiers. We also outline the important considerations for those referencing identifiers in various circumstances, including by authors and data generators. While the importance and relevance of each lesson will vary by context, there is a need for increased awareness about how to avoid and manage common identifier problems, especially those related to persistence and web-accessibility/resolvability. We focus strongly on web-based identifiers in the life sciences; however, the principles are broadly relevant to other disciplines.
Related Concept Videos
 01:29
Modern Molecular Taxonomy
 01:57
Sanger Sequencing