Related Experiment Video
Updated: Feb 24, 2026

A Novel Bayesian Change-point Algorithm for Genome-wide Analysis of Diverse ChIPseq Data Types
Published on: December 10, 2012
Bayesian mixture modeling of significant p values: A meta-analytic method to estimate the degree of contamination
Quentin Frederik Gronau1, Monique Duizer2, Marjan Bakker1
1Department of Psychology, University of Amsterdam.

Abstract:
Publication bias and questionable research practices have long been known to corrupt the published record. One method to assess the extent of this corruption is to examine the meta-analytic collection of significant p values, the so-called p-curve (Simonsohn, Nelson, & Simmons, 2014a). Inspired by statistical research on false-discovery rates, we propose a Bayesian mixture model analysis of the p-curve. Our mixture model assumes that significant p values arise either from the null-hypothesis H₀ (when their distribution is uniform) or from the alternative hypothesis H1 (when their distribution is accounted for by a simple parametric model). The mixture model estimates the proportion of significant results that originate from H₀, but it also estimates the probability that each specific p value originates from H₀. We apply our model to 2 examples. The first concerns the set of 587 significant p values for all t tests published in the 2007 volumes of Psychonomic Bulletin & Review and the Journal of Experimental Psychology: Learning, Memory, and Cognition; the mixture model reveals that p values higher than about .005 are more likely to stem from H₀ than from H₁. The second example concerns 159 significant p values from studies on social priming and 130 from yoked control studies. The results from the yoked controls confirm the findings from the first example, whereas the results from the social priming studies are difficult to interpret because they are sensitive to the prior specification. To maximize accessibility, we provide a web application that allows researchers to apply the mixture model to any set of significant p values. (PsycINFO Database Record
Related Concept Videos
 01:09
Decision Making: P-value Method
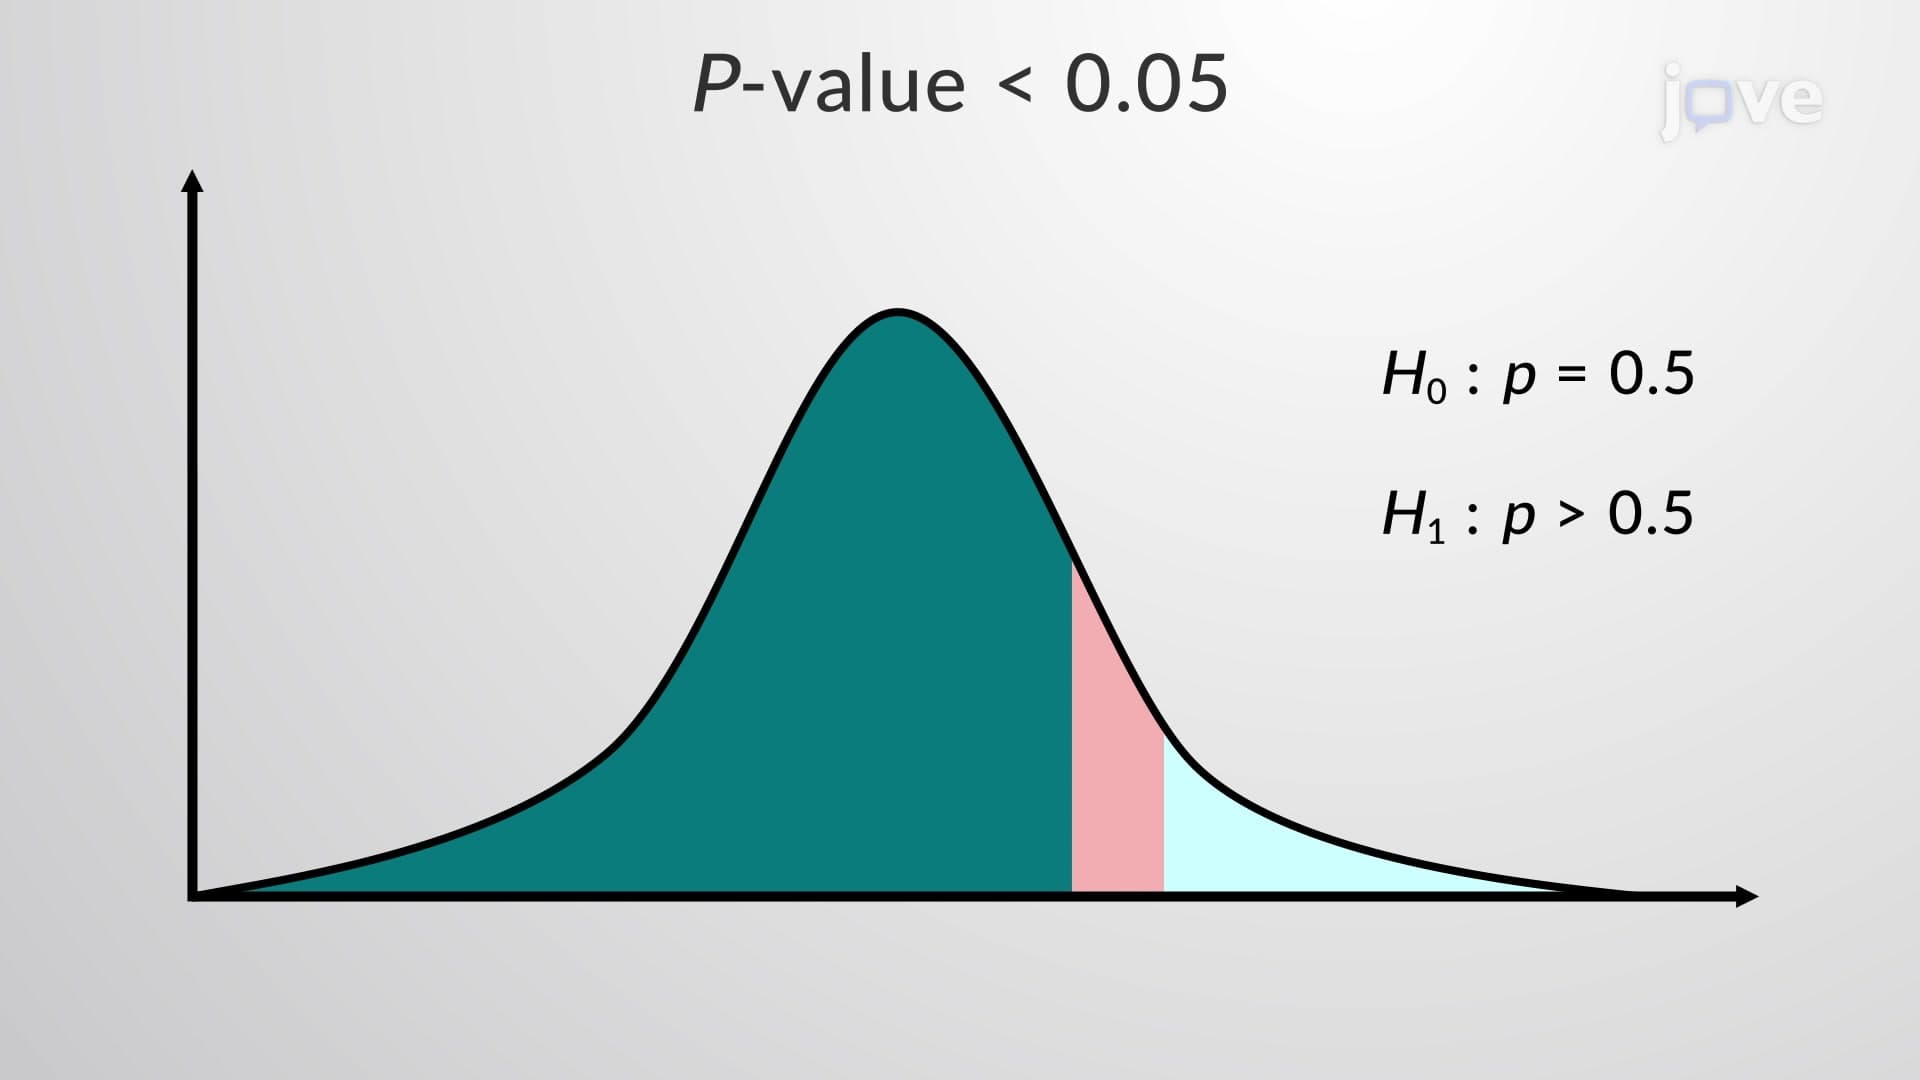
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
 01:10
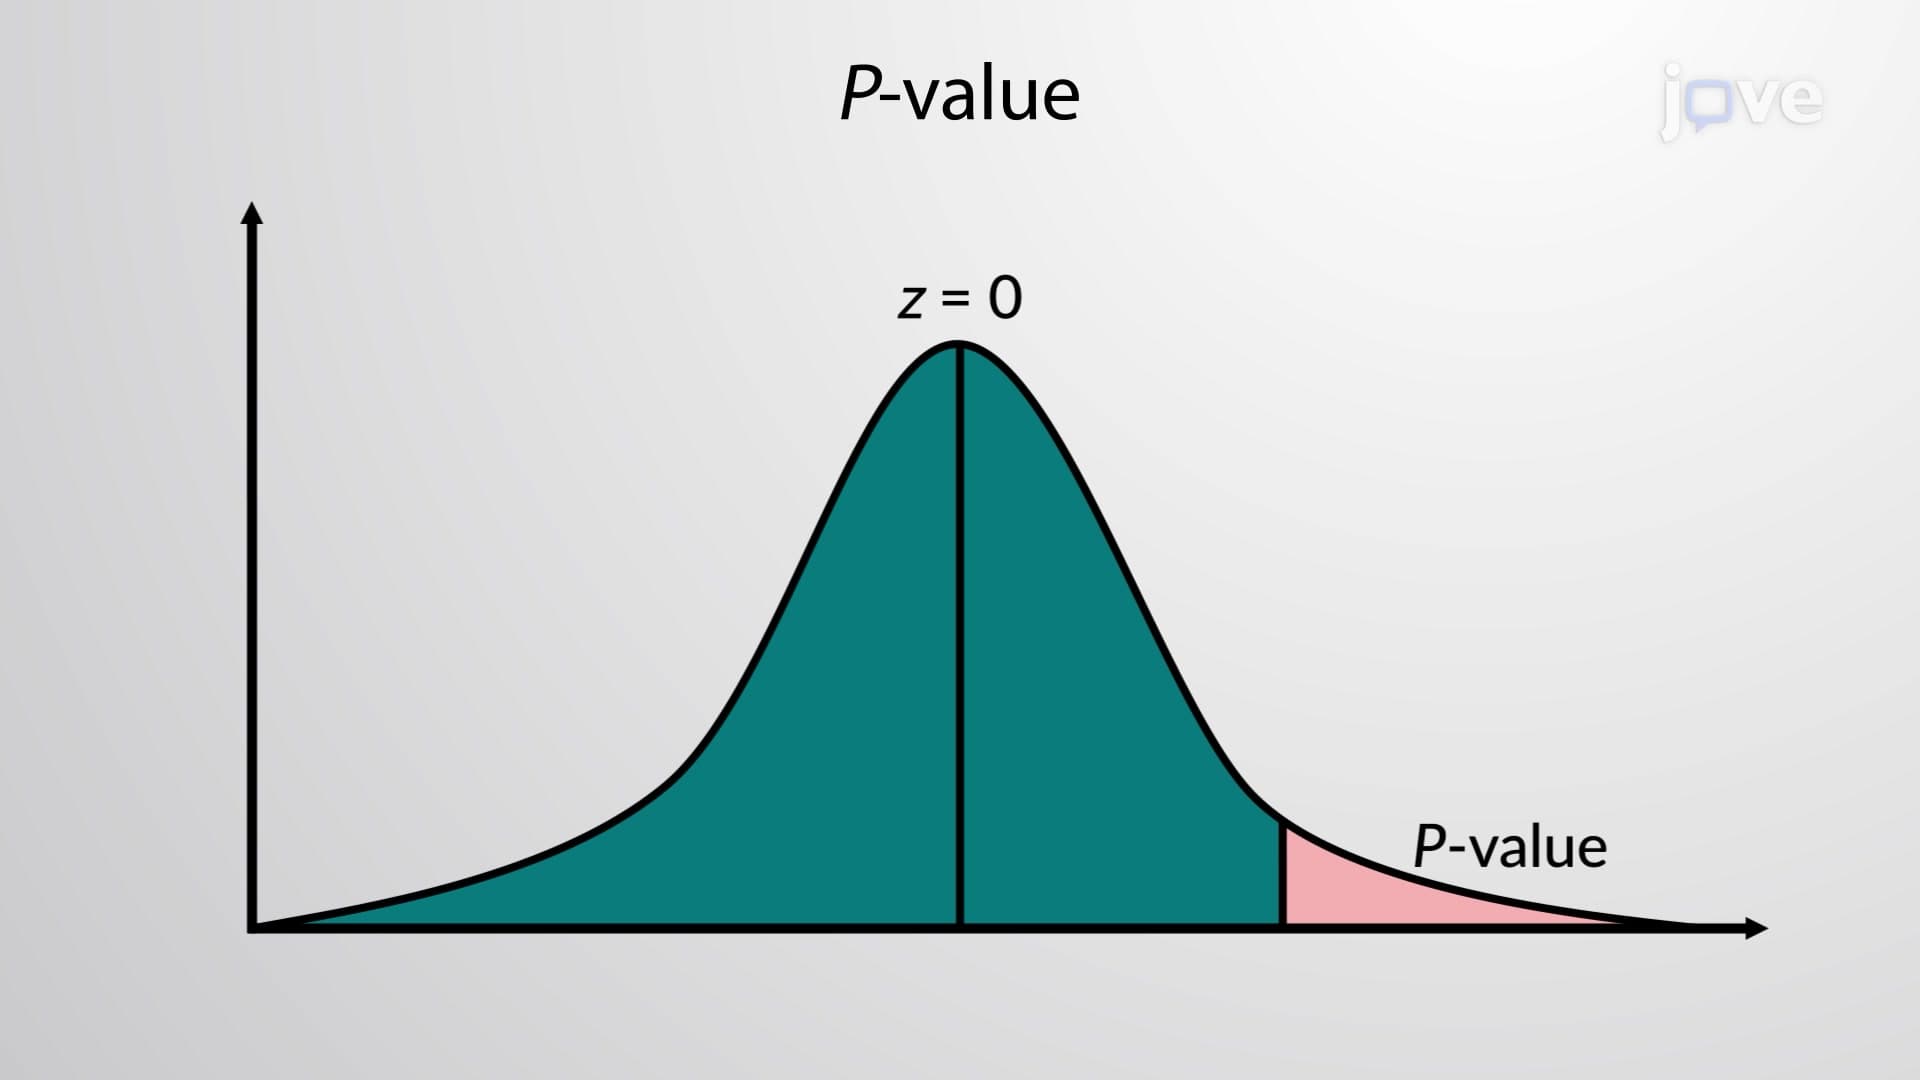
P-value
P-value stands for the probability value. P-value is the probability that, if the null hypothesis is true, the results from another randomly selected sample will be as extreme or more extreme as the results obtained from the given sample.
A large P-value calculated from the data indicates to not reject the null hypothesis. But a higher P-value does not mean that the null hypothesis is true. The smaller the P-value, the more...
 01:10
Bonferroni Test
The means of different samples are first paired in all possible combinations.
The null hypothesis of the...
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
 01:14
Decision Making: Traditional Method
First, a specific claim about the population parameter is decided based on the research question and is stated in a simple form. Further, an opposing statement to this claim is also stated. These statements can act as null and alternative hypotheses, out of which a null hypothesis would be a...