Related Experiment Video
Updated: Feb 20, 2026
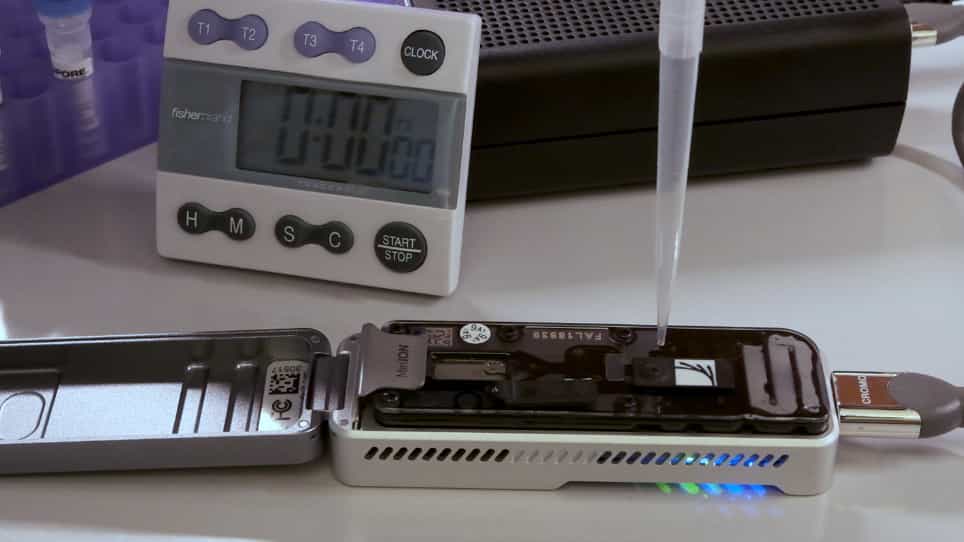
Hybrid De Novo Genome Assembly for the Generation of Complete Genomes of Urinary Bacteria using Short- and Long-read Sequencing Technologies
Published on: August 20, 2021
MegaGTA: a sensitive and accurate metagenomic gene-targeted assembler using iterative de Bruijn graphs
Dinghua Li1, Yukun Huang1, Chi-Ming Leung1,2
1Department of Computer Science, University of Hong Kong, Pokfulam, Hong Kong.

Background:
The recent release of the gene-targeted metagenomics assembler Xander has demonstrated that using the trained Hidden Markov Model (HMM) to guide the traversal of de Bruijn graph gives obvious advantage over other assembly methods. Xander, as a pilot study, indeed has a lot of room for improvement. Apart from its slow speed, Xander uses only 1 k-mer size for graph construction and whatever choice of k will compromise either sensitivity or accuracy. Xander uses a Bloom-filter representation of de Bruijn graph to achieve a lower memory footprint. Bloom filters bring in false positives, and it is not clear how this would impact the quality of assembly. Xander does not keep track of the multiplicity of k-mers, which would have been an effective way to differentiate between erroneous k-mers and correct k-mers.
Results:
In this paper, we present a new gene-targeted assembler MegaGTA, which attempts to improve Xander in different aspects. Quality-wise, it utilizes iterative de Bruijn graphs to take full advantage of multiple k-mer sizes to make the best of both sensitivity and accuracy. Computation-wise, it employs succinct de Bruijn graphs (SdBG) to achieve low memory footprint and high speed (the latter is benefited from a highly efficient parallel algorithm for constructing SdBG). Unlike Bloom filters, an SdBG is an exact representation of a de Bruijn graph. It enables MegaGTA to avoid false-positive contigs and to easily incorporate the multiplicity of k-mers for building better HMM model. We have compared MegaGTA and Xander on an HMP-defined mock metagenomic dataset, and showed that MegaGTA excelled in both sensitivity and accuracy. On a large rhizosphere soil metagenomic sample (327Gbp), MegaGTA produced 9.7-19.3% more contigs than Xander, and these contigs were assigned to 10-25% more gene references. In our experiments, MegaGTA, depending on the number of k-mers used, is two to ten times faster than Xander.
Conclusion:
MegaGTA improves on the algorithm of Xander and achieves higher sensitivity, accuracy and speed. Moreover, it is capable of assembling gene sequences from ultra-large metagenomic datasets. Its source code is freely available at https://github.com/HKU-BAL/megagta .
Related Concept Videos
 03:36
Genome Annotation and Assembly
 03:00
Next-generation Sequencing
Next-Generation Sequencing Methods
Although all next-generation methods use different technologies, they all share a set of standard features....
 01:57
Sanger Sequencing
 01:05
Maxam-Gilbert Sequencing
Challenges of the Maxam-Gilbert Method
The...
 02:02
Genomics
 02:37
Gene Duplication and Divergence
The duplicated copies of the gene are called Paralogs. Paralogs with similar sequences and functions form a gene family. Across several species, a large number of gene families are...