Related Experiment Video
Updated: Feb 8, 2026
Measuring Sensitivity to Viewpoint Change with and without Stereoscopic Cues
Published on: December 4, 2013
On Space-Time Filtering Framework for Matching Human Actions Across Different Viewpoints

Abstract:
Space-time template matching is considered as a promising approach for human action recognition. However, a major drawback of template-based methods is computational overhead due to matching in spatial domain. Recently, space-time correlation-based action filters have been proposed for recognizing human actions in frequency domain. These action filters present reduction in time complexity as Fourier transform-based matching is faster than spatial template matching. However, the utility of such action filters is challenged due to a number of factors: 1) inability to deal with view variations due to implicit lack of support for view-invariance; 2) these filters can be trained only for one action class at a time, and separate filters are required for each action class with increased computational overhead; 3) these filters simply take average of similar action instances and behave no better than average filters; and 4) slightly misaligned action data sets create problems as these filters are not shift-invariant. In this paper, we try to address these shortcomings by proposing an advanced space-time filtering framework for recognizing human actions despite large viewpoint variations. Rather than using crude intensity values, we use 3D tensor structure at each pixel, which characterizes the most common local motion in action sequences. Discrete tensor Fourier transform is then applied to achieve frequency domain representations. Then, we form view clusters from multiple view action data and use space-time correlation filtering to achieve discriminative view representations. These representations are used in an innovative way to achieve action recognition despite viewpoint variations. Extensive experimentation is performed on well-known multiple view action data sets, including IXMAS, WVU, and N-UCLA action data set. A detailed performance comparison with the existing view-invariant action recognition techniques indicates that our approach works equally well for RGB and RGB-D video data with increased accuracy and efficiency.
Related Concept Videos
 01:17
Space-Time Curvature and the General Theory of Relativity
This has been verified in many experiments. However, space and time are no longer absolute. Two observers moving relative to one another do not agree on the length of objects or the passage of time. The mechanics of objects based on Newton's laws of...
 01:17
Sign Test for Matched Pairs
To conduct the sign test, we first calculate the differences in...
 01:27
Passive Filters
Low-Pass Filters
Low-pass filters are designed to transmit signals with frequencies lower than the cutoff frequency, ωc, and attenuate those above it. The cutoff...
 01:25
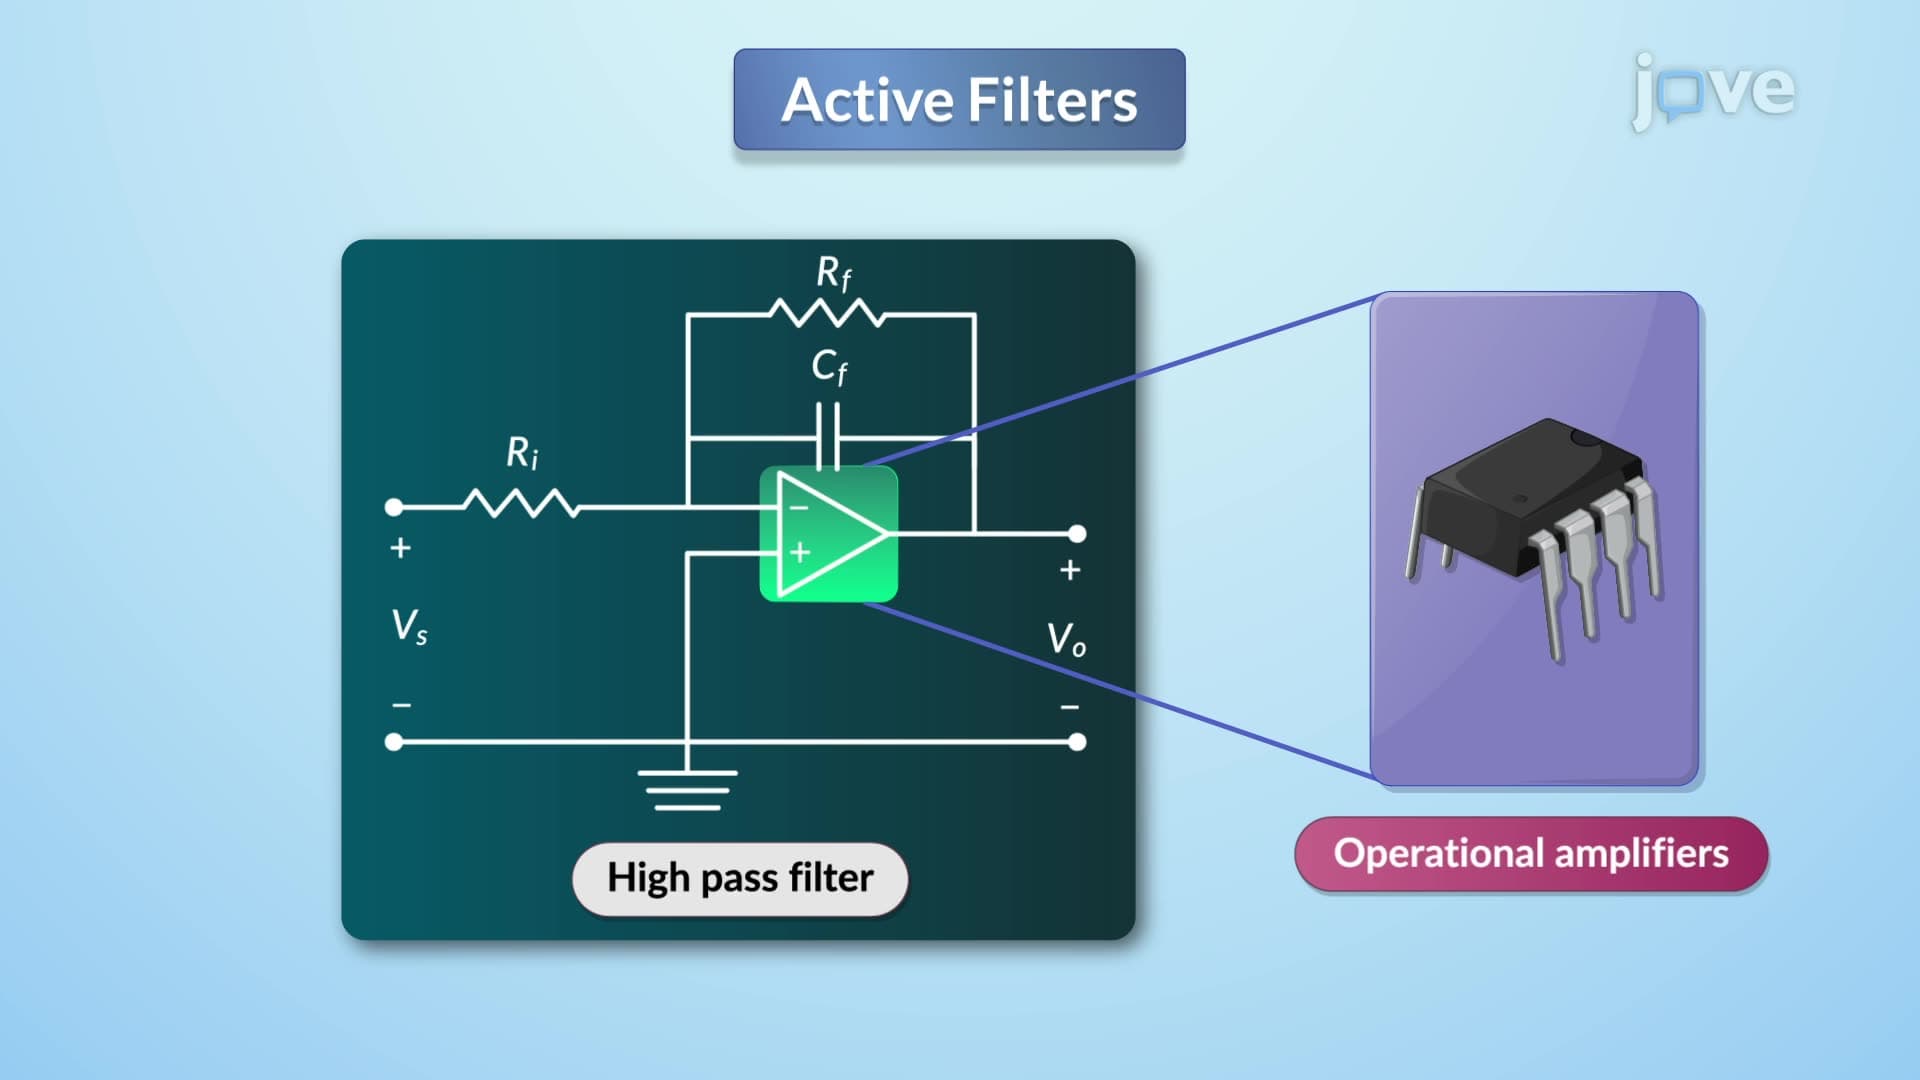
Active Filters
 01:06
Fixed Action Patterns
 01:25
Space Trusses
At the core of a space truss lies the fundamental unit known as the tetrahedron. This structure is composed of six members that form a three-dimensional shape...