Related Experiment Video
Updated: Oct 11, 2026
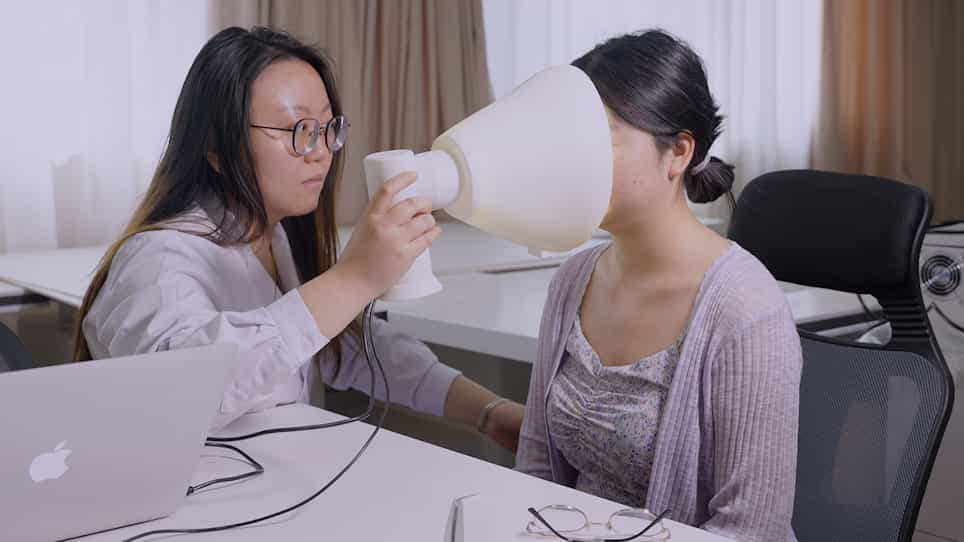

Objectification of Tongue Diagnosis in Traditional Medicine, Data Analysis, and Study Application
Published on: April 14, 2023
Local Feature Enhancement of dino.txt for Training-Free Open-Vocabulary Semantic Segmentation

Abstract:
Open-vocabulary semantic segmentation aims to establish dense pixel-wise correspondences between images and open-ended semantic categories. While most existing methods build upon CLIP's image-text alignment capability, they require substantial architectural modifications to adapt image-level understanding to pixel-level prediction. The recently introduced dino.txt model offers an alternative by employing DINOv2 as its visual backbone, which inherently captures both image-level and pixel-level representations. Through global and local image-text alignment training, dino.txt learns to establish open-vocabulary correspondences, opening up new possibilities for semantic segmentation. To fully exploit dino.txt for this task, we propose FreeD, a training-free approach that enhances pixel-text matching accuracy while preserving global semantics. FreeD achieves this by adaptively refining intermediate features and attention mechanisms based on token-level local similarities. We further introduce FreeDP, which fuses complementary features from multiple vision-language models to achieve more robust segmentation. Extensive experiments on standard benchmarks demonstrate the state-of-the-art performance of our training-free method.