Scalable Consistency in T-Coffee Through Apache Spark and Cassandra Database
Related Experiment Video
Updated: Feb 7, 2026
The Hawaii Protocol for Scientific Monitoring of Coffee Berry Borer: a Model for Coffee Agroecosystems Worldwide
Published on: March 19, 2018
Jordi Lladós1, Fernando Cores1, Fernando Guirado1
1INSPIRES Research Center, Universitat de Lleida , Lleida, Spain .

Abstract:
Next-generation sequencing, also known as high-throughput sequencing, has increased the volume of genetic data processed by sequencers. In the bioinformatic scientific area, highly rated multiple sequence alignment tools, such as MAFFT, ProbCons, and T-Coffee (TC), use the probabilistic consistency as a prior step to the progressive alignment stage to improve the final accuracy. However, such methods are severely limited by the memory required to store the consistency information. Big data processing and persistence techniques are used to manage and store the huge amount of information that is generated. Although these techniques have significant advantages, few biological applications have adopted them. In this article, a novel approach named big data tree-based consistency objective function for alignment evaluation (BDT-Coffee) is presented. BDT-Coffee is based on the integration of consistency information through Cassandra database in TC, previously generated by the MapReduce processing paradigm, to enable large data sets to be processed with the aim of improving the performance and scalability of the original algorithm.
Related Concept Videos
 03:02
Constant Pressure Calorimetry
 01:24
pH
 01:20
Conformity
 03:06
Alkali Metals
Table 1: Properties of the alkali metals
 02:41
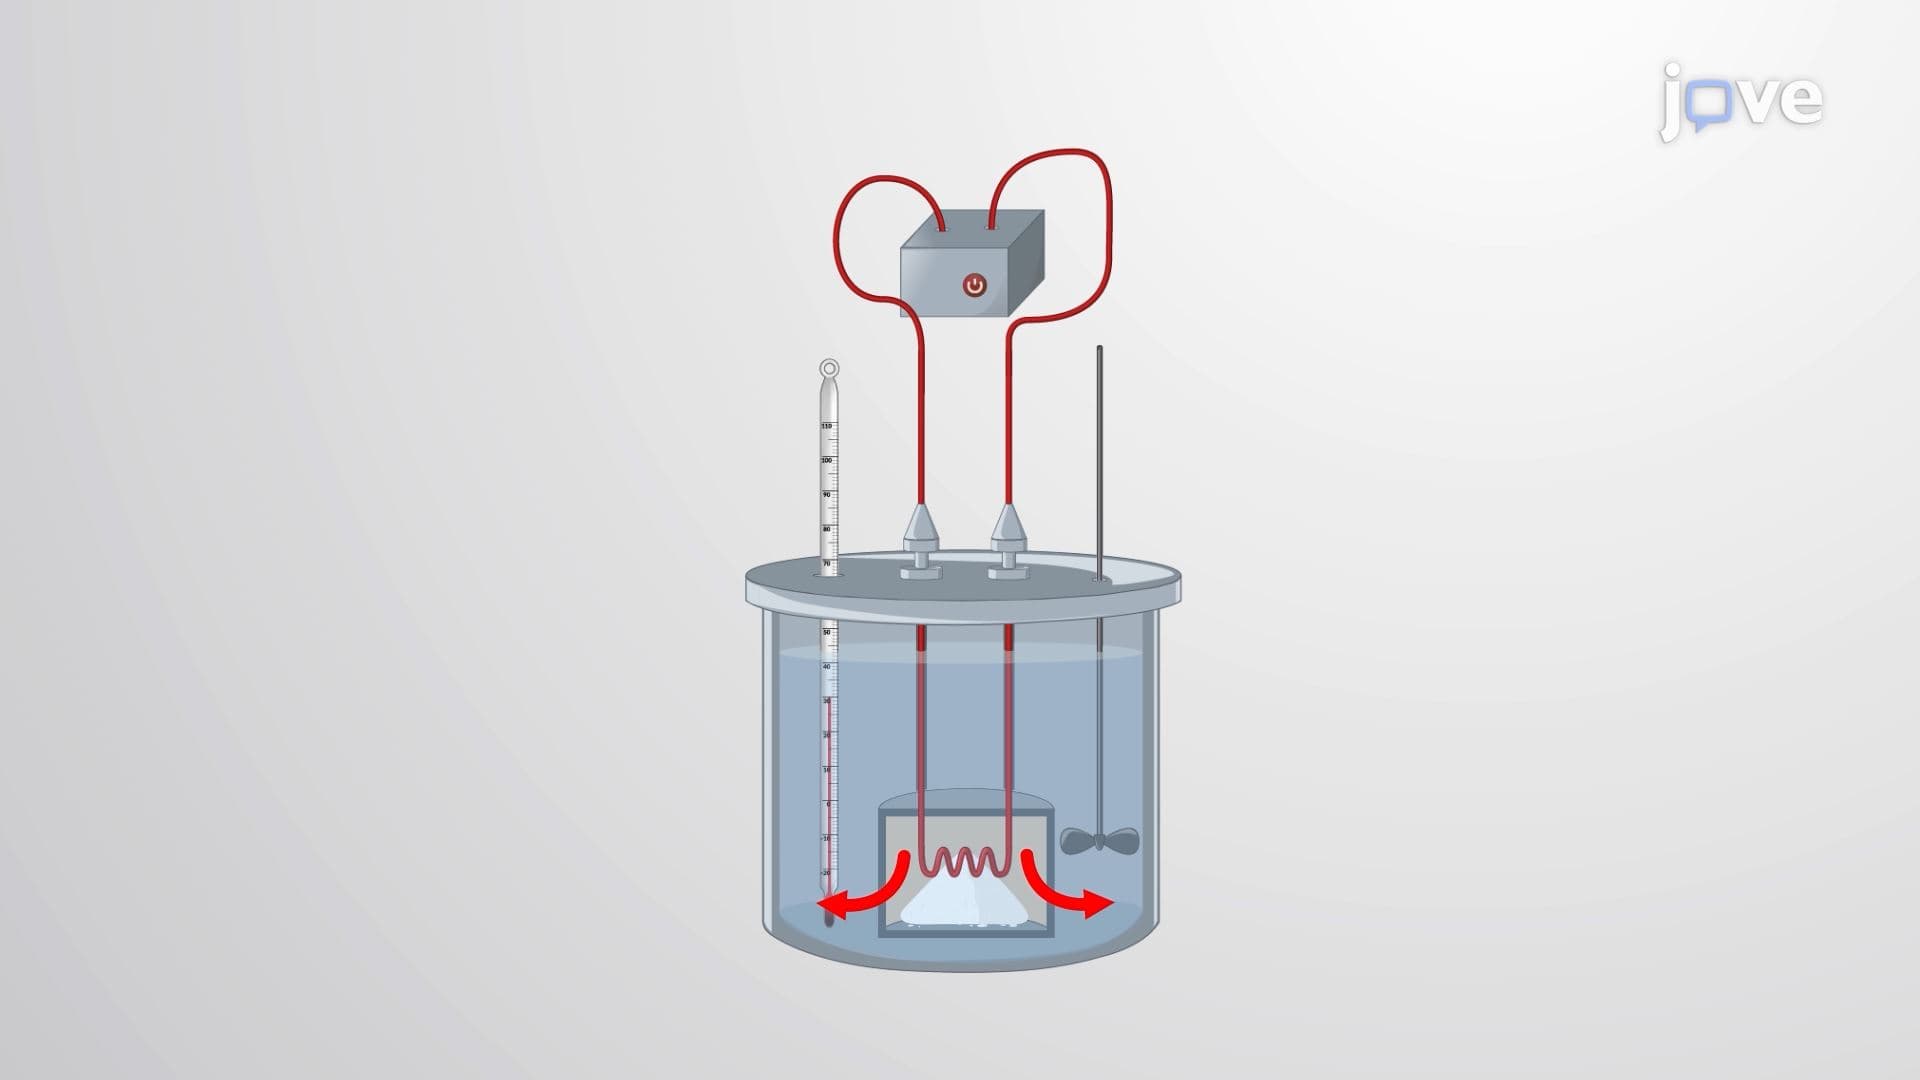
Constant Volume Calorimetry
 02:26
Protein Networks
These interactions can be represented through maps depicting protein-protein interaction networks, represented as nodes and edges. Nodes are circles that are representative of a protein,...