Related Experiment Video
Updated: Feb 7, 2026

Mass Spectrometry-Guided Genome Mining as a Tool to Uncover Novel Natural Products
Published on: March 12, 2020
Benchmarking relief-based feature selection methods for bioinformatics data mining
Ryan J Urbanowicz1, Randal S Olson1, Peter Schmitt1
1Institute for Biomedical Informatics, University of Pennsylvania, Philadelphia, PA 19104, USA.

Abstract:
Modern biomedical data mining requires feature selection methods that can (1) be applied to large scale feature spaces (e.g. 'omics' data), (2) function in noisy problems, (3) detect complex patterns of association (e.g. gene-gene interactions), (4) be flexibly adapted to various problem domains and data types (e.g. genetic variants, gene expression, and clinical data) and (5) are computationally tractable. To that end, this work examines a set of filter-style feature selection algorithms inspired by the 'Relief' algorithm, i.e. Relief-Based algorithms (RBAs). We implement and expand these RBAs in an open source framework called ReBATE (Relief-Based Algorithm Training Environment). We apply a comprehensive genetic simulation study comparing existing RBAs, a proposed RBA called MultiSURF, and other established feature selection methods, over a variety of problems. The results of this study (1) support the assertion that RBAs are particularly flexible, efficient, and powerful feature selection methods that differentiate relevant features having univariate, multivariate, epistatic, or heterogeneous associations, (2) confirm the efficacy of expansions for classification vs. regression, discrete vs. continuous features, missing data, multiple classes, or class imbalance, (3) identify previously unknown limitations of specific RBAs, and (4) suggest that while MultiSURF∗ performs best for explicitly identifying pure 2-way interactions, MultiSURF yields the most reliable feature selection performance across a wide range of problem types.
More Related Videos
 13:44
Project-Based Learning Guidelines for Health Sciences Students: An Analysis with Data Mining and Qualitative Techniques
Published on: December 9, 2022
 09:20
Cloud-Based Phrase Mining and Analysis of User-Defined Phrase-Category Association in Biomedical Publications
Published on: February 23, 2019
Related Concept Videos
 01:25
Selected Data About Geographic Locations
 00:57
Antibiotic Selection
 01:25
Statistical Methods for Analyzing Epidemiological Data
 01:12
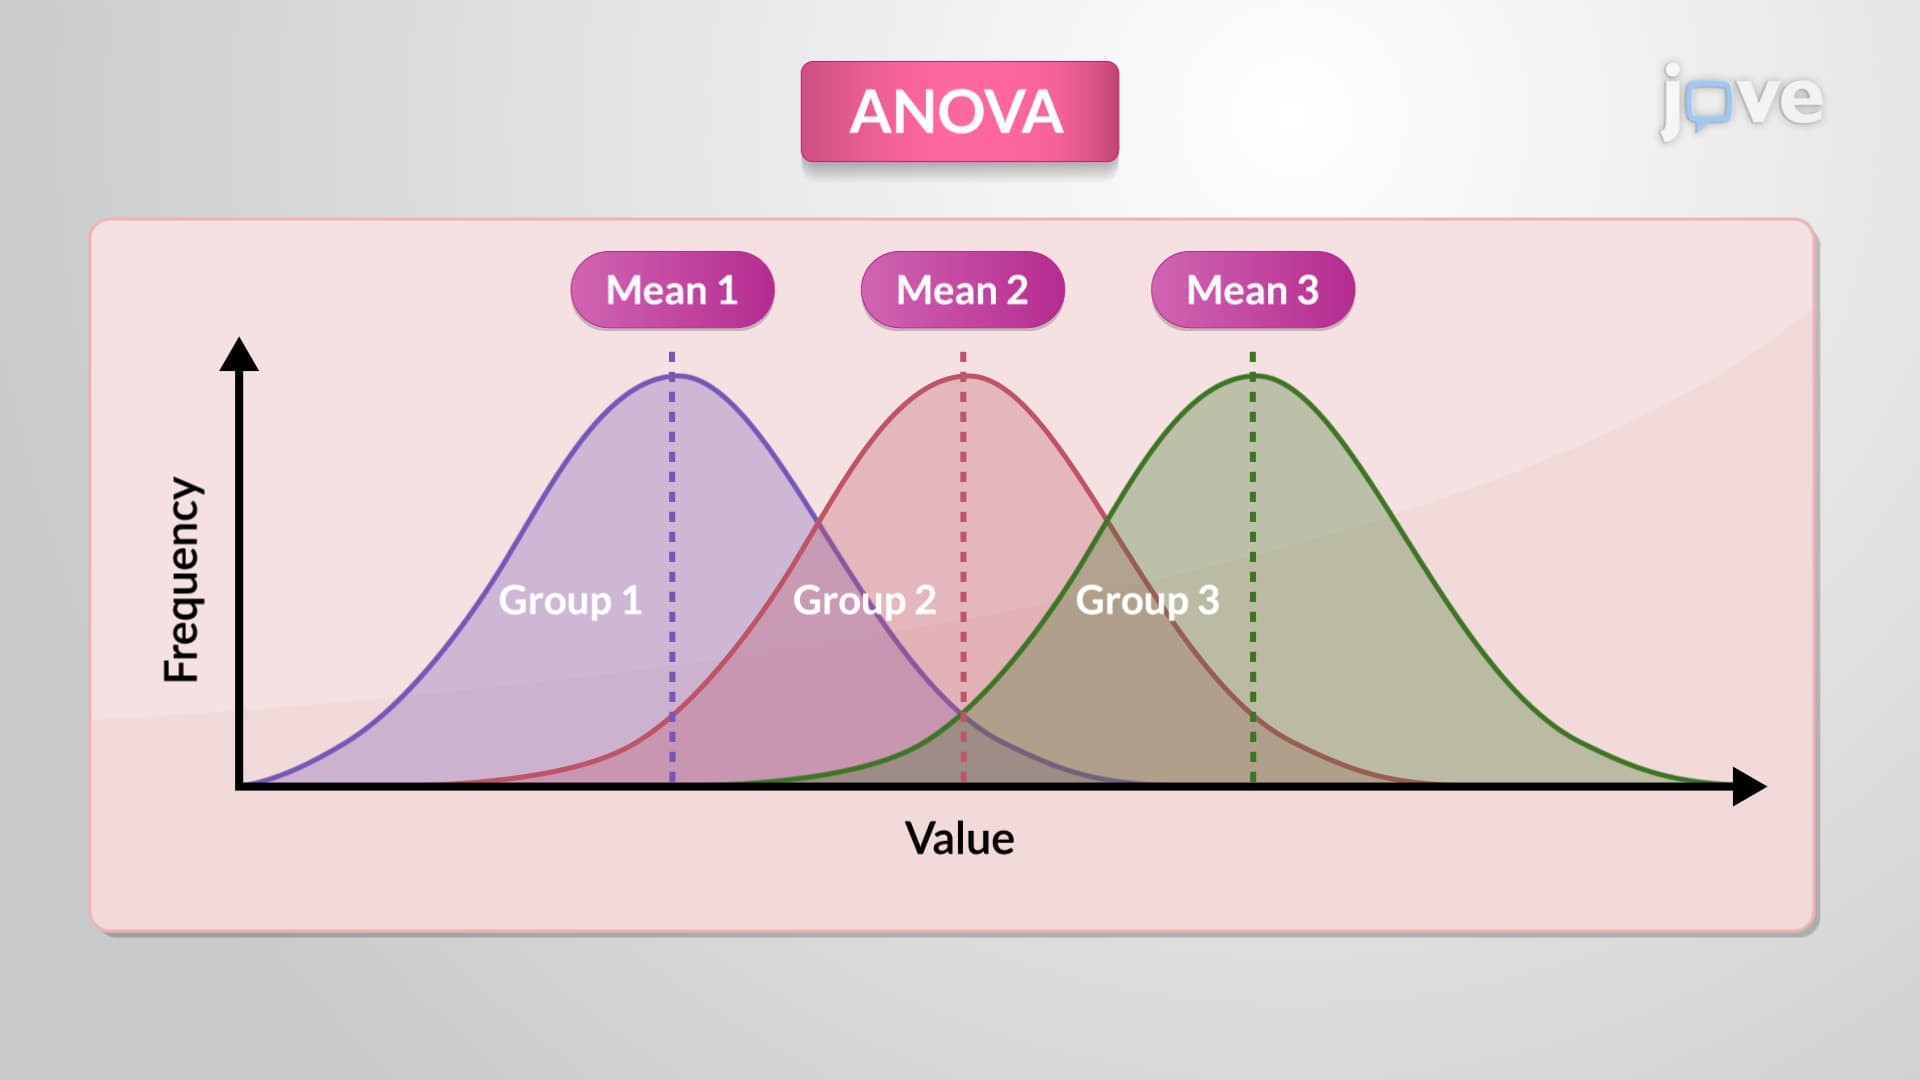
Statistical Methods to Analyze Parametric Data: ANOVA
One-way ANOVA is applied when a single independent variable or factor is scrutinized. It compares...
 01:32
What is Natural Selection?
 01:11
How Data are Classified: Categorical Data
Data are classified based on whether they are measurable or not. Categorical data cannot be measured; instead, it can be divided into categories. For example, if Y denotes a person's party affiliation, some examples of Y include...