Subject level clustering using a negative binomial model for small transcriptomic studies
Related Experiment Video
Updated: Feb 1, 2026
Studying Triple Negative Breast Cancer Using Orthotopic Breast Cancer Model
Published on: March 20, 2020
Qian Li1,2, Janelle R Noel-MacDonnell3, Devin C Koestler4
1Department of Biostatistics and Bioinformatics, Moffitt Cancer Center, 12902 Magnolia Drive, Tampa, FL, 33612, USA.

Background:
Unsupervised clustering represents one of the most widely applied methods in analysis of high-throughput 'omics data. A variety of unsupervised model-based or parametric clustering methods and non-parametric clustering methods have been proposed for RNA-seq count data, most of which perform well for large samples, e.g. N ≥ 500. A common issue when analyzing limited samples of RNA-seq count data is that the data follows an over-dispersed distribution, and thus a Negative Binomial likelihood model is often used. Thus, we have developed a Negative Binomial model-based (NBMB) clustering approach for application to RNA-seq studies.
Results:
We have developed a Negative Binomial Model-Based (NBMB) method to cluster samples using a stochastic version of the expectation-maximization algorithm. A simulation study involving various scenarios was completed to compare the performance of NBMB to Gaussian model-based or Gaussian mixture modeling (GMM). NBMB was also applied for the clustering of two RNA-seq studies; type 2 diabetes study (N = 96) and TCGA study of ovarian cancer (N = 295). Simulation results showed that NBMB outperforms GMM applied with different transformations in majority of scenarios with limited sample size. Additionally, we found that NBMB outperformed GMM for small clusters distance regardless of sample size. Increasing total number of genes with fixed proportion of differentially expressed genes does not change the outperformance of NBMB, but improves the overall performance of GMM. Analysis of type 2 diabetes and ovarian cancer tumor data with NBMB found good agreement with the reported disease subtypes and the gene expression patterns. This method is available in an R package on CRAN named NB.MClust.
Conclusion:
Use of Negative Binomial model based clustering is advisable when clustering over dispersed RNA-seq count data.
Related Concept Videos
 01:30
The Binomial Theorem
 01:15
Binomial Probability Distribution
The outcomes of a binomial experiment fit a binomial probability distribution. A statistical experiment can be classified as a binomial experiment if the following conditions are met:
There are a fixed number of trials. Think of trials as repetitions of an experiment. The letter n denotes the number of trials.
There are only two possible outcomes,...
 01:15
Bioavailability Study Design: Healthy Subjects Versus Patients
 01:30
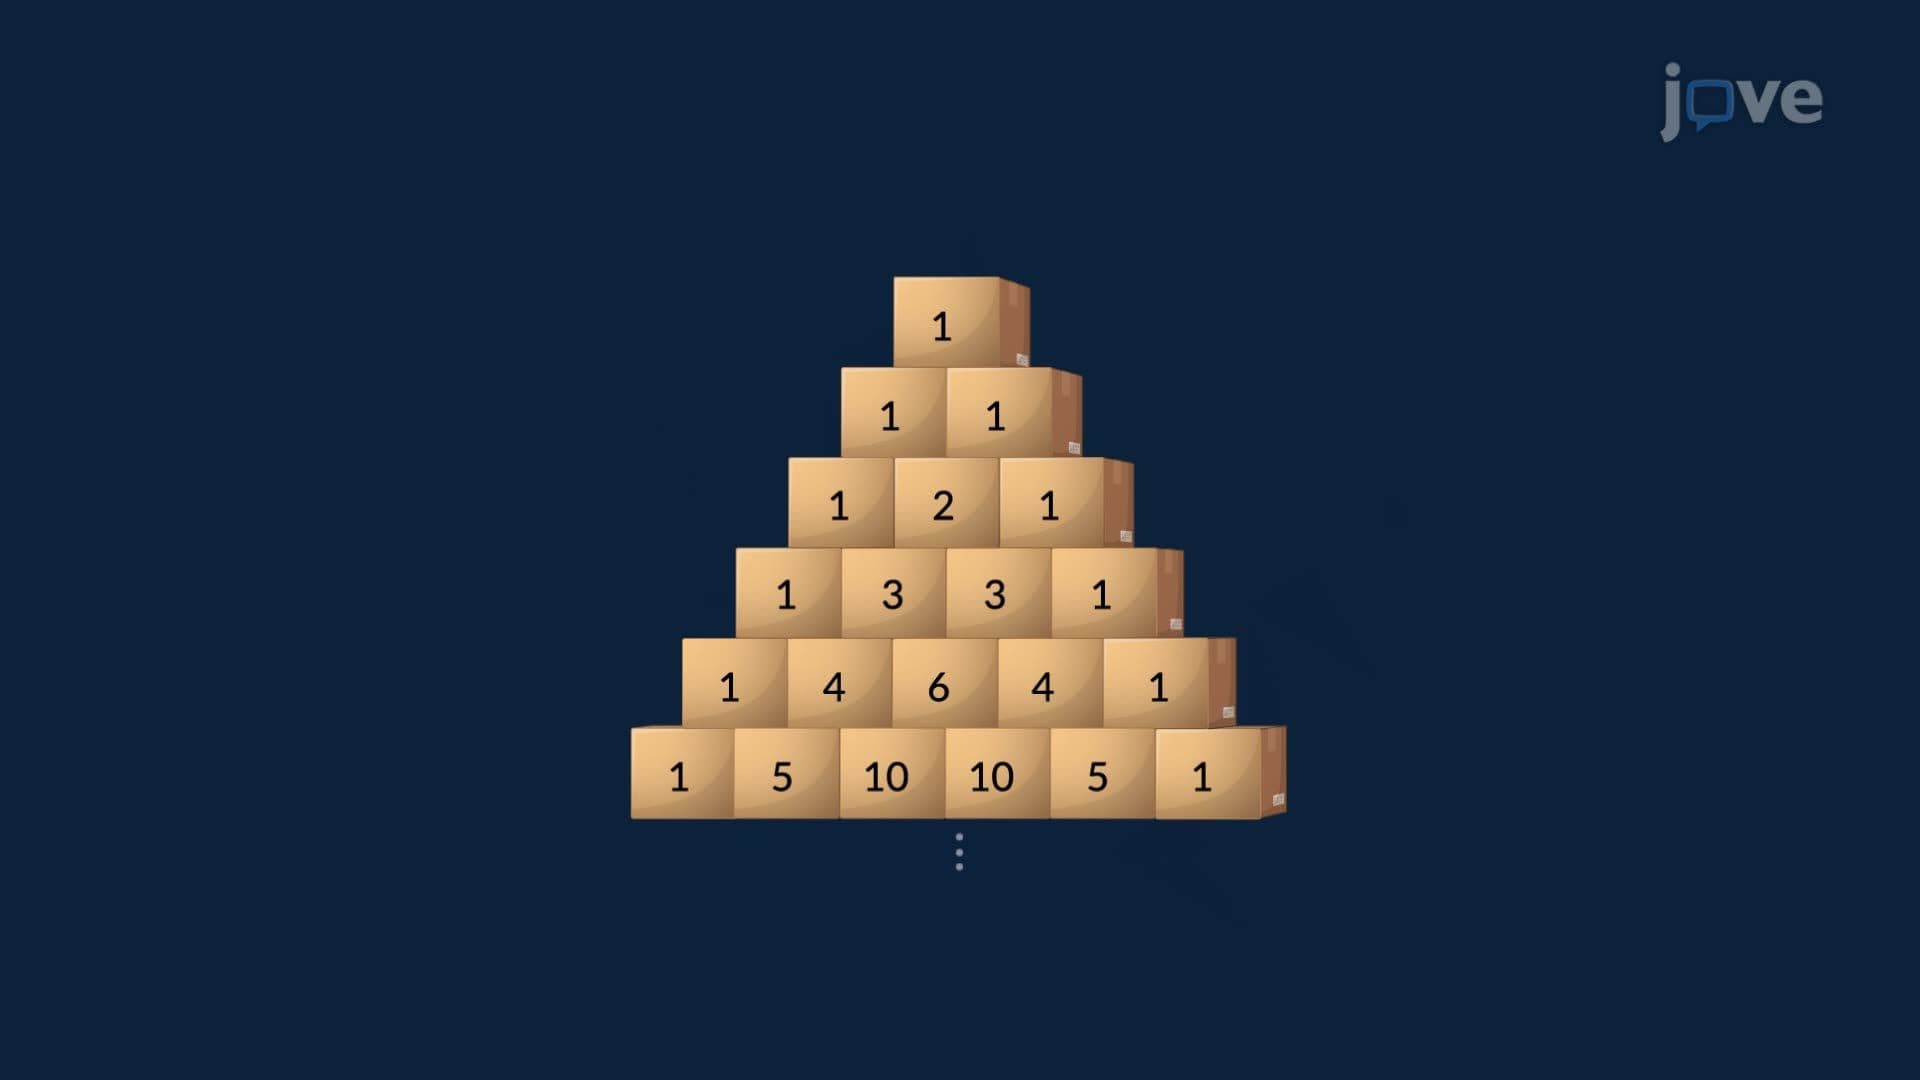
Binomial Expansion Using Pascal's Triangle
 01:23
Negative Regulator Molecules
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...