
Model for Predicting the pH of Foods Comprising Mixtures of Tomatoes and Low-Acid Ingredients
G M Sapers1, J G Phillips1, A M Divito1
1Eastern Regional Research Center2, Philadelphia, Pennsylvania 19118.

Abstract:
The possibility of predicting the pH of home-canned foods comprising mixtures of tomatoes and low-acid ingredients was investigated. A quadratic model representing multi-component mixtures of tomatoes and nine low-acid ingredients, combined in various proportions, was tested. A 19-term equation for pH prediction, generated from the data, yielded a correlation coefficient of 0.9998 and a standard error of 0.11 pH unit. Tomato acidity was an important determinant of product pH. The equation was validated by comparing the predicted and observed pH of 55 representative products. Good agreement between these pH values was obtained. Criteria for recognition of low-acid products were established.
Related Concept Videos
 03:27
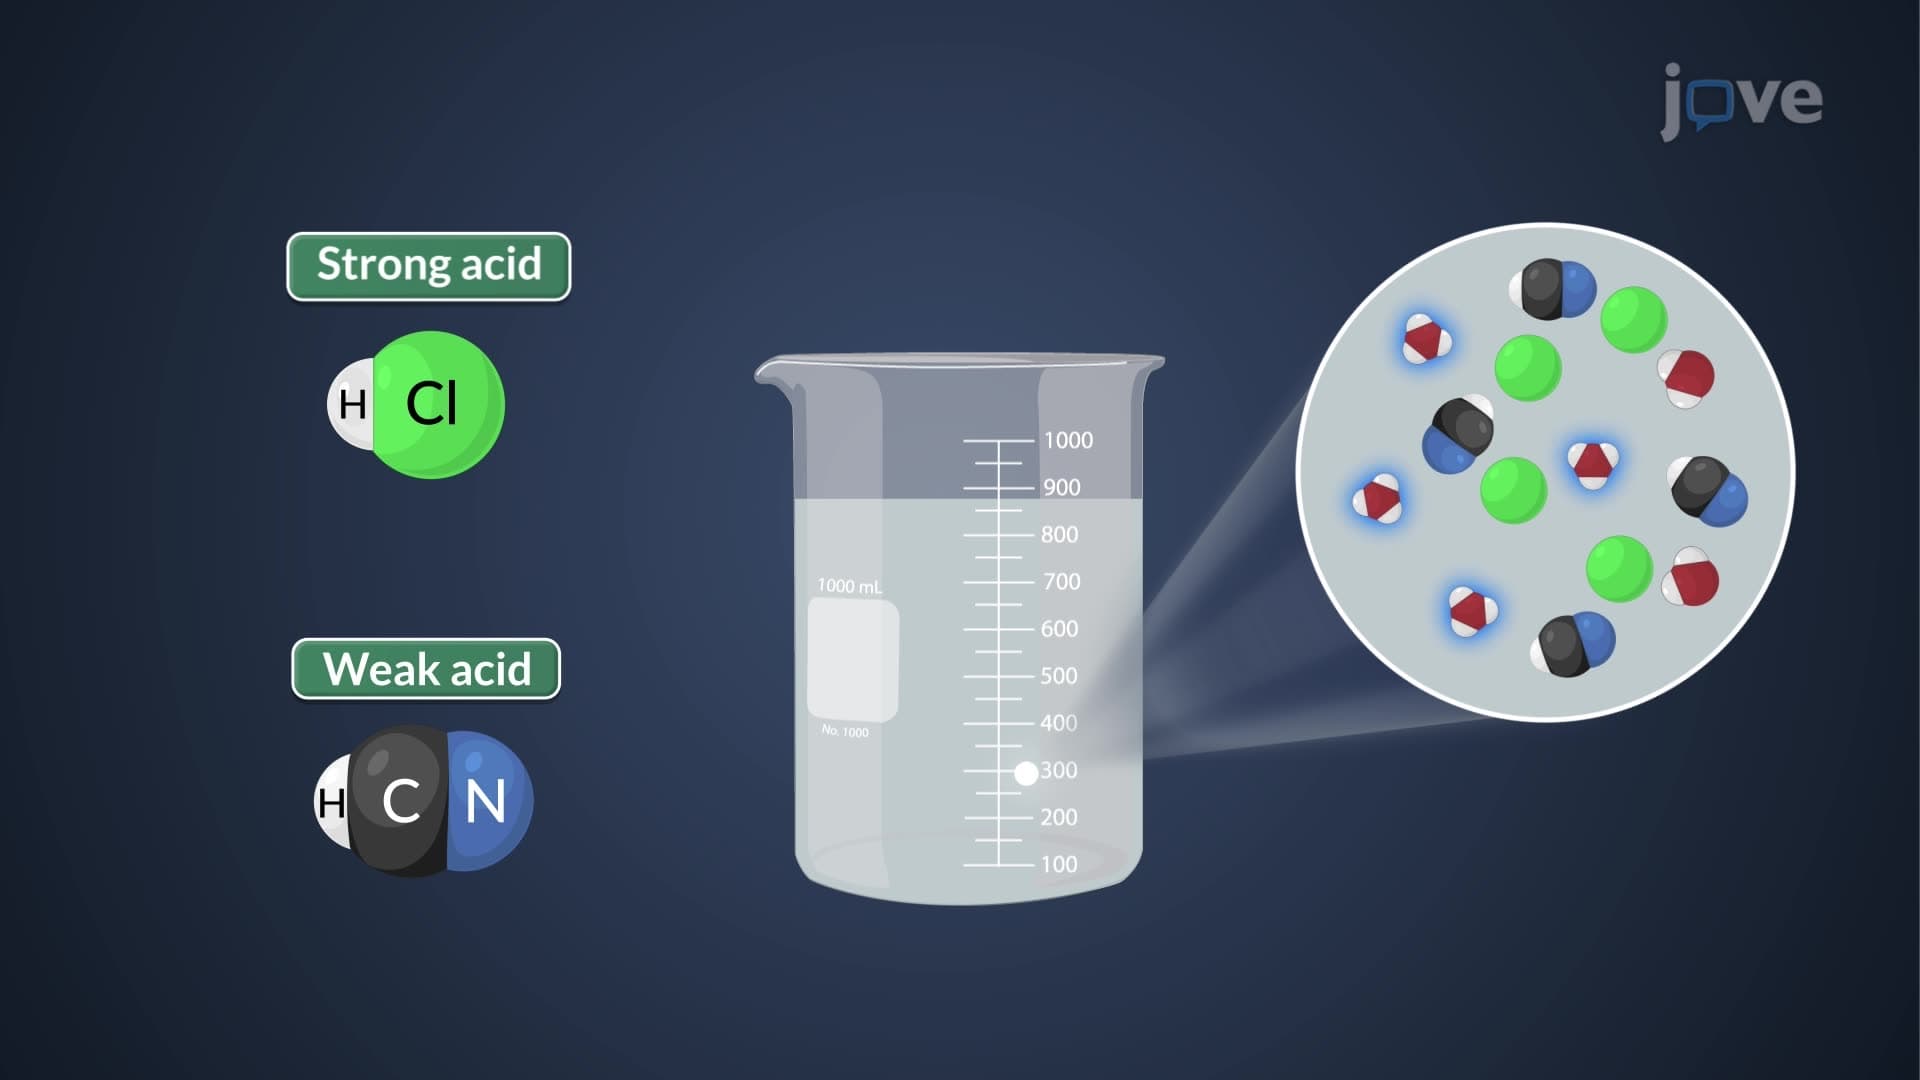
Mixtures of Acids
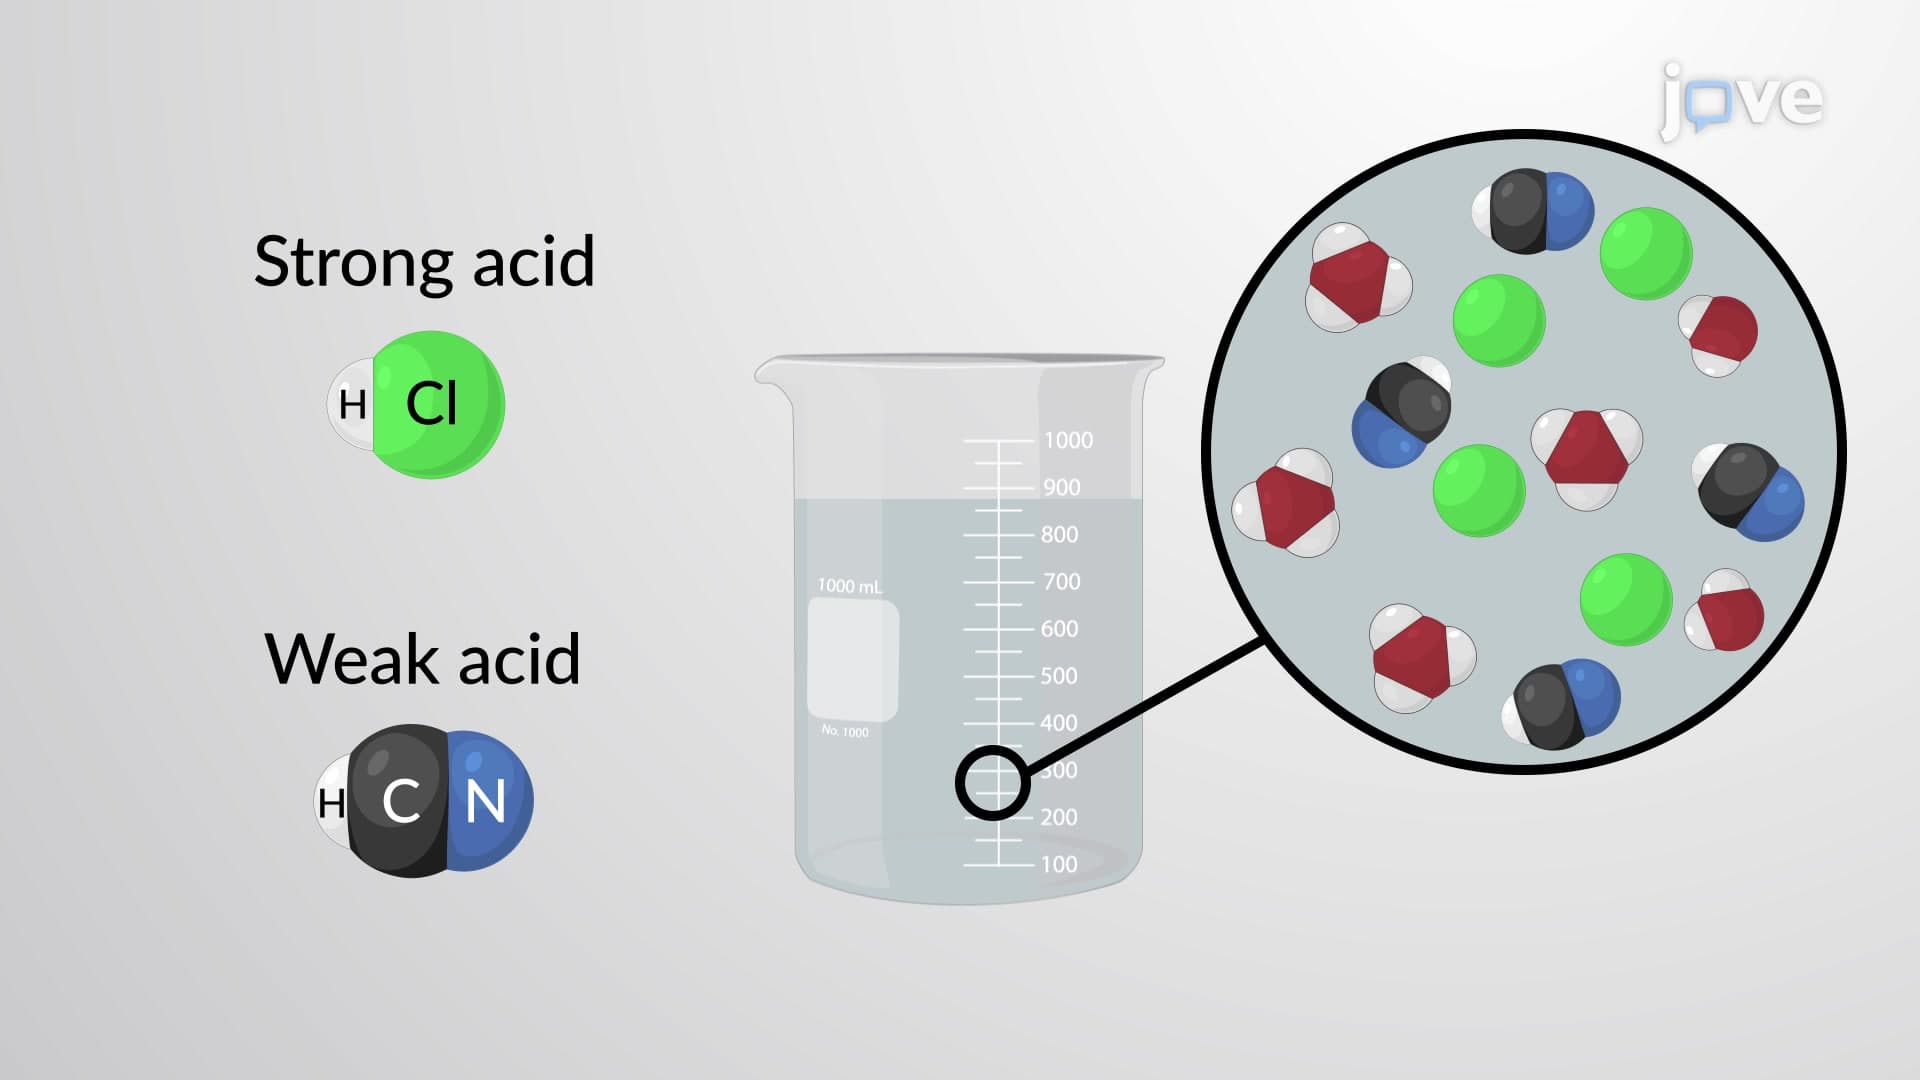
A Mixture of a Strong Acid and a Weak Acid
In a mixture of a strong acid and a weak acid, the strong acid dissociates completely and becomes a source of almost all the hydronium ions...
 01:19
Mixtures of Acids
In a strong and weak acid mixture, the strong acid dissociates completely and becomes a source of almost all the hydronium ions present in the solution. In contrast, the weak acid shows...
 02:27
Predicting Molecular Geometry
 02:43
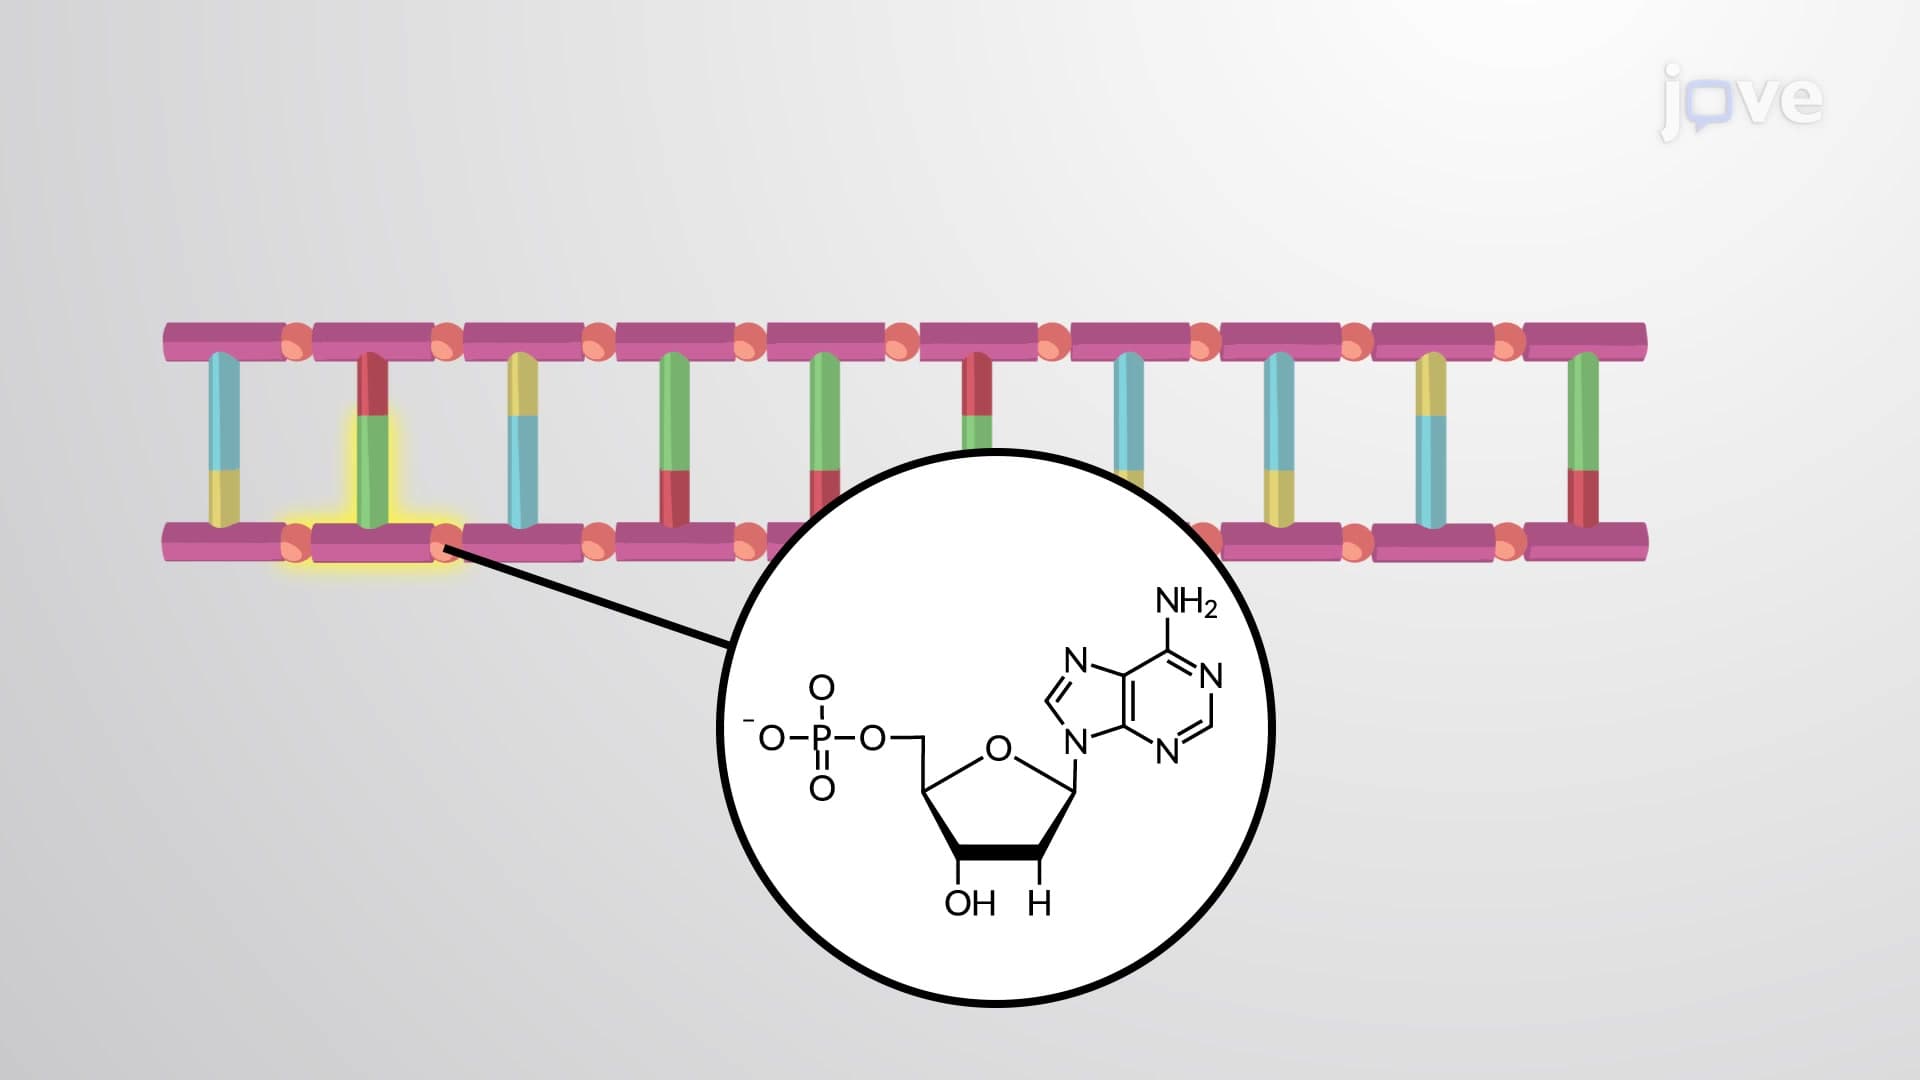
Nucleic acids
DNA and RNA
The two main types of nucleic acids are deoxyribonucleic acid (DNA) and ribonucleic acid (RNA). DNA is the genetic material in all living organisms, ranging from single-celled bacteria to multicellular mammals. It is in the nucleus of eukaryotes and in the organelles, chloroplasts, and mitochondria. In prokaryotes,...
 02:30
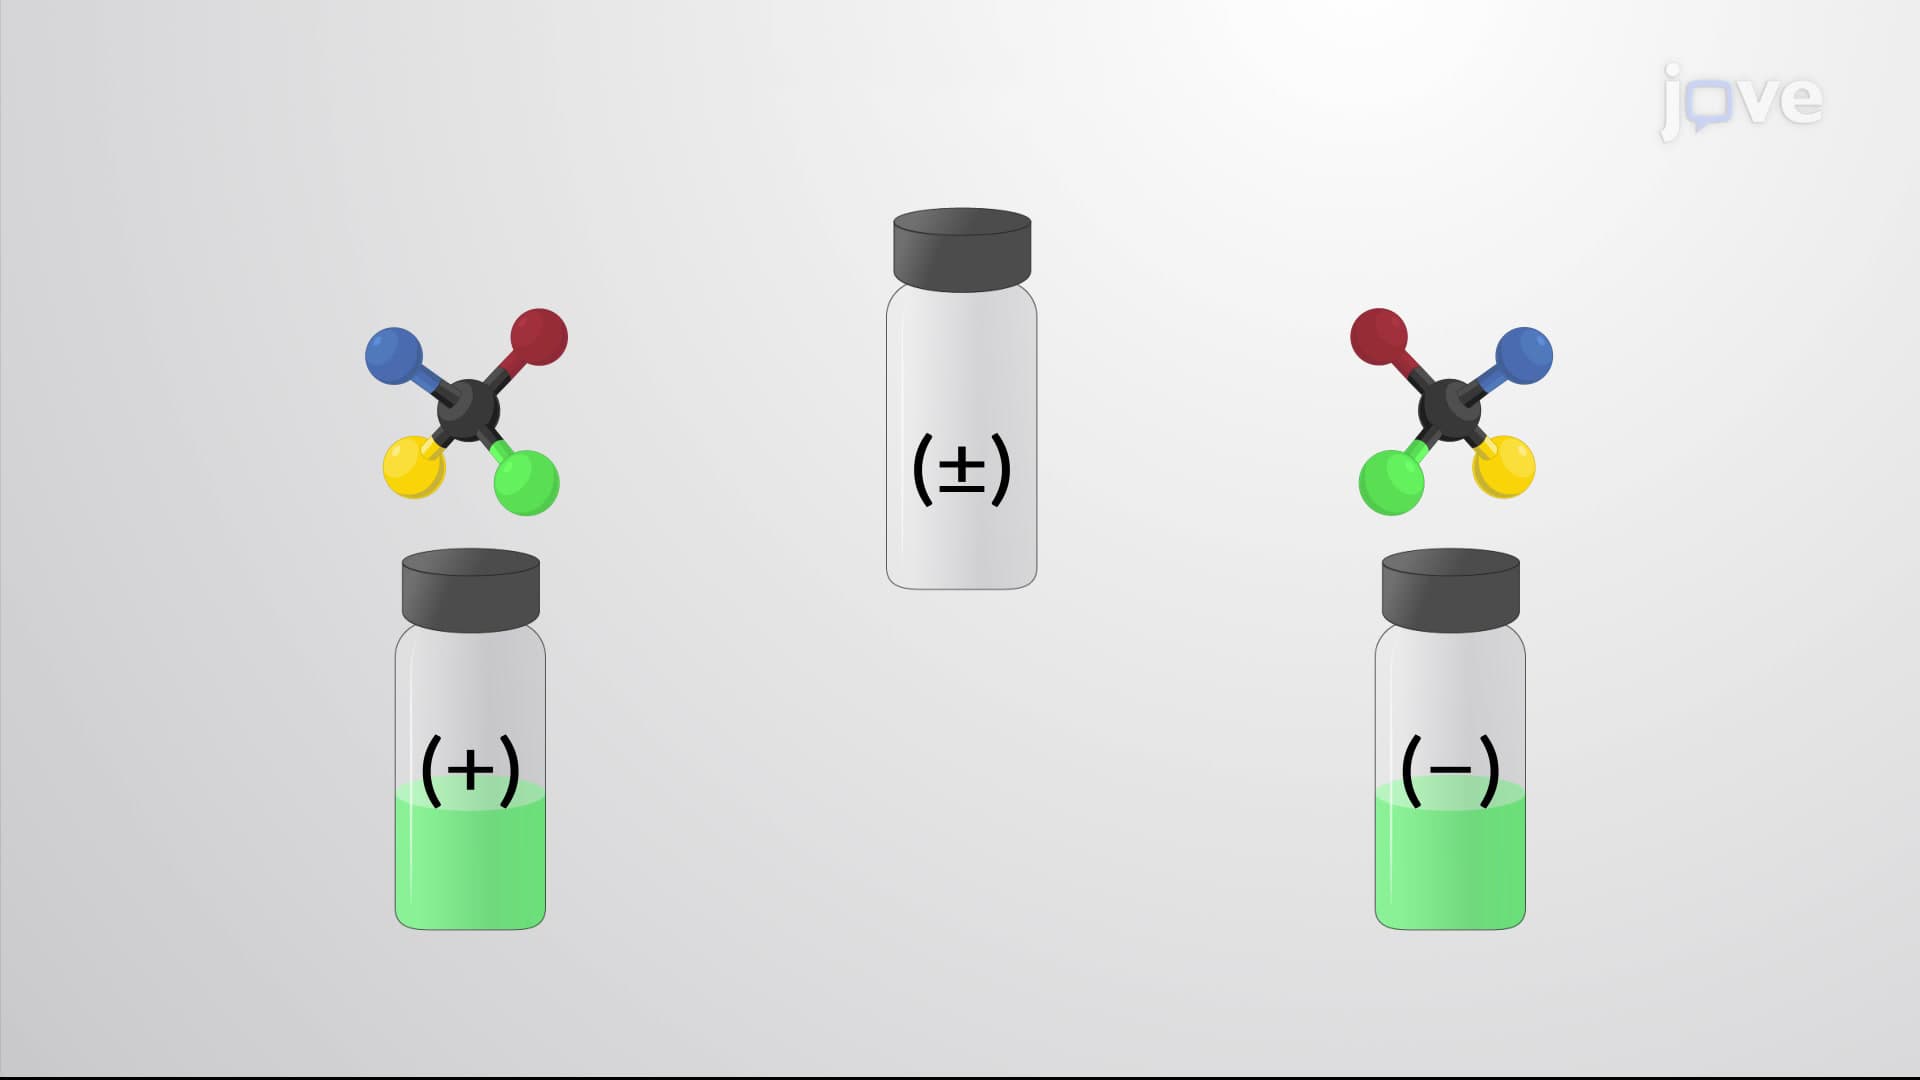
Racemic Mixtures and the Resolution of Enantiomers
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.