Related Experiment Video
Updated: Jan 26, 2026
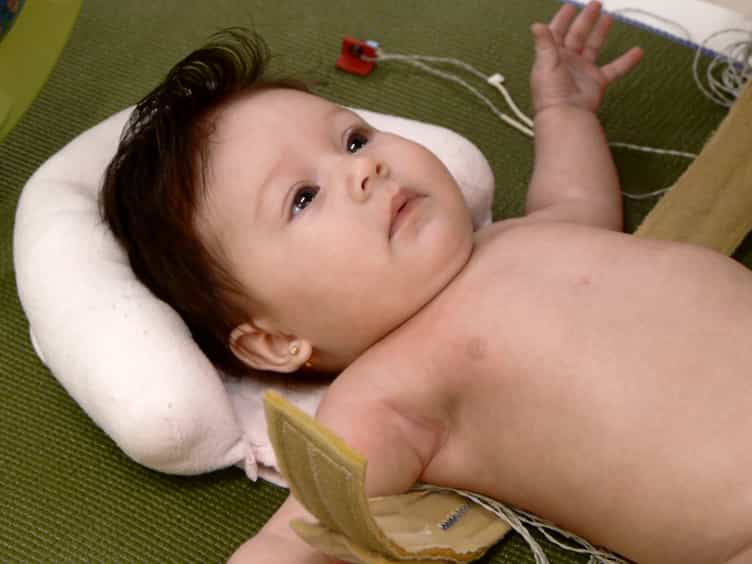

Quantifying Learning in Young Infants: Tracking Leg Actions During a Discovery-learning Task
Published on: June 1, 2015
The Hierarchical Continuous Pursuit Learning Automation: A Novel Scheme for Environments With Large Numbers of

Abstract:
Although the field of learning automata (LA) has made significant progress in the past four decades, the LA-based methods to tackle problems involving environments with a large number of actions is, in reality, relatively unresolved. The extension of the traditional LA to problems within this domain cannot be easily established when the number of actions is very large. This is because the dimensionality of the action probability vector is correspondingly large, and so, most components of the vector will soon have values that are smaller than the machine accuracy permits, implying that they will never be chosen. This paper presents a solution that extends the continuous pursuit paradigm to such large-actioned problem domains. The beauty of the solution is that it is hierarchical, where all the actions offered by the environment reside as leaves of the hierarchy. Furthermore, at every level, we merely require a two-action LA that automatically resolves the problem of dealing with arbitrarily small action probabilities. In addition, since all the LA invoke the pursuit paradigm, the best action at every level trickles up toward the root. Thus, by invoking the property of the "max" operator, in which the maximum of numerous maxima is the overall maximum, the hierarchy of LA converges to the optimal action. This paper describes the scheme and formally proves its ϵ -optimal convergence. The results presented here can, rather trivially, be extended for the families of discretized and Bayesian pursuit LA too. This paper also reports extensive experimental results (including for environments having 128 and 256 actions) that demonstrate the power of the scheme and its computational advantages. As far as we know, there are no comparable pursuit-based results in the field of LA. In some cases, the hierarchical continuous pursuit automaton requires less than 18% of the number of iterations than the benchmark LR-I scheme, which is, by all metrics, phenomenal.
Related Concept Videos
 01:34
The Z-Scheme of Electron Transport in Photosynthesis
 01:06
Fixed Action Patterns
 01:31
Action Potential
Membrane potential in neurons
Neurons typically have a resting membrane potential of about -70 millivolts (mV). When they receive...
01:14Action Potential
Membrane potential in neurons
Neurons typically have a resting membrane potential of about -70 millivolts (mV). When they receive...
 01:41
Action Potentials
 01:14
Avoidance Learning and Learned Helplessness
Avoidance learning occurs when an organism learns that a specific behavior can prevent an unpleasant outcome. For example, a student who receives a bad grade may start studying harder to avoid future poor grades. This behavior persists even when the negative outcome is no longer present. Avoidance learning is powerful because it maintains behavior in the absence of the...