Related Experiment Video
Updated: Jan 24, 2026
Methods to Test Visual Attention Online
Published on: February 19, 2015
Visual Attention Prediction for Stereoscopic Video by Multi-Module Fully Convolutional Network

Abstract:
Visual attention is an important mechanism in the human visual system (HVS) and there have been numerous saliency detection algorithms designed for 2D images/video recently. However, the research for fixation detection of stereoscopic video is still limited and challenging due to the complicated depth and motion information. In this paper, we design a novel multi-module fully convolutional network (MM-FCN) for fixation detection of stereoscopic video. Specifically, we design a fully convolutional network for spatial saliency prediction (S-FCN), where the initial spatial saliency map of stereoscopic video is learned by image database of object detection. Furthermore, the fully convolutional network for temporal saliency prediction (T-FCN) is constructed by combining saliency results from S-FCN and motion information from video frames. Finally, the fully convolutional network for depth fixation prediction (D-FCN) is designed to compute the final fixation map of stereoscopic video by learning depth features with spatiotemporal features from T-FCN. The experimental results show that the proposed MM-FCN can predict fixation results for stereoscopic video more effectively and efficiently than other related fixation prediction methods.
Related Concept Videos
 01:17
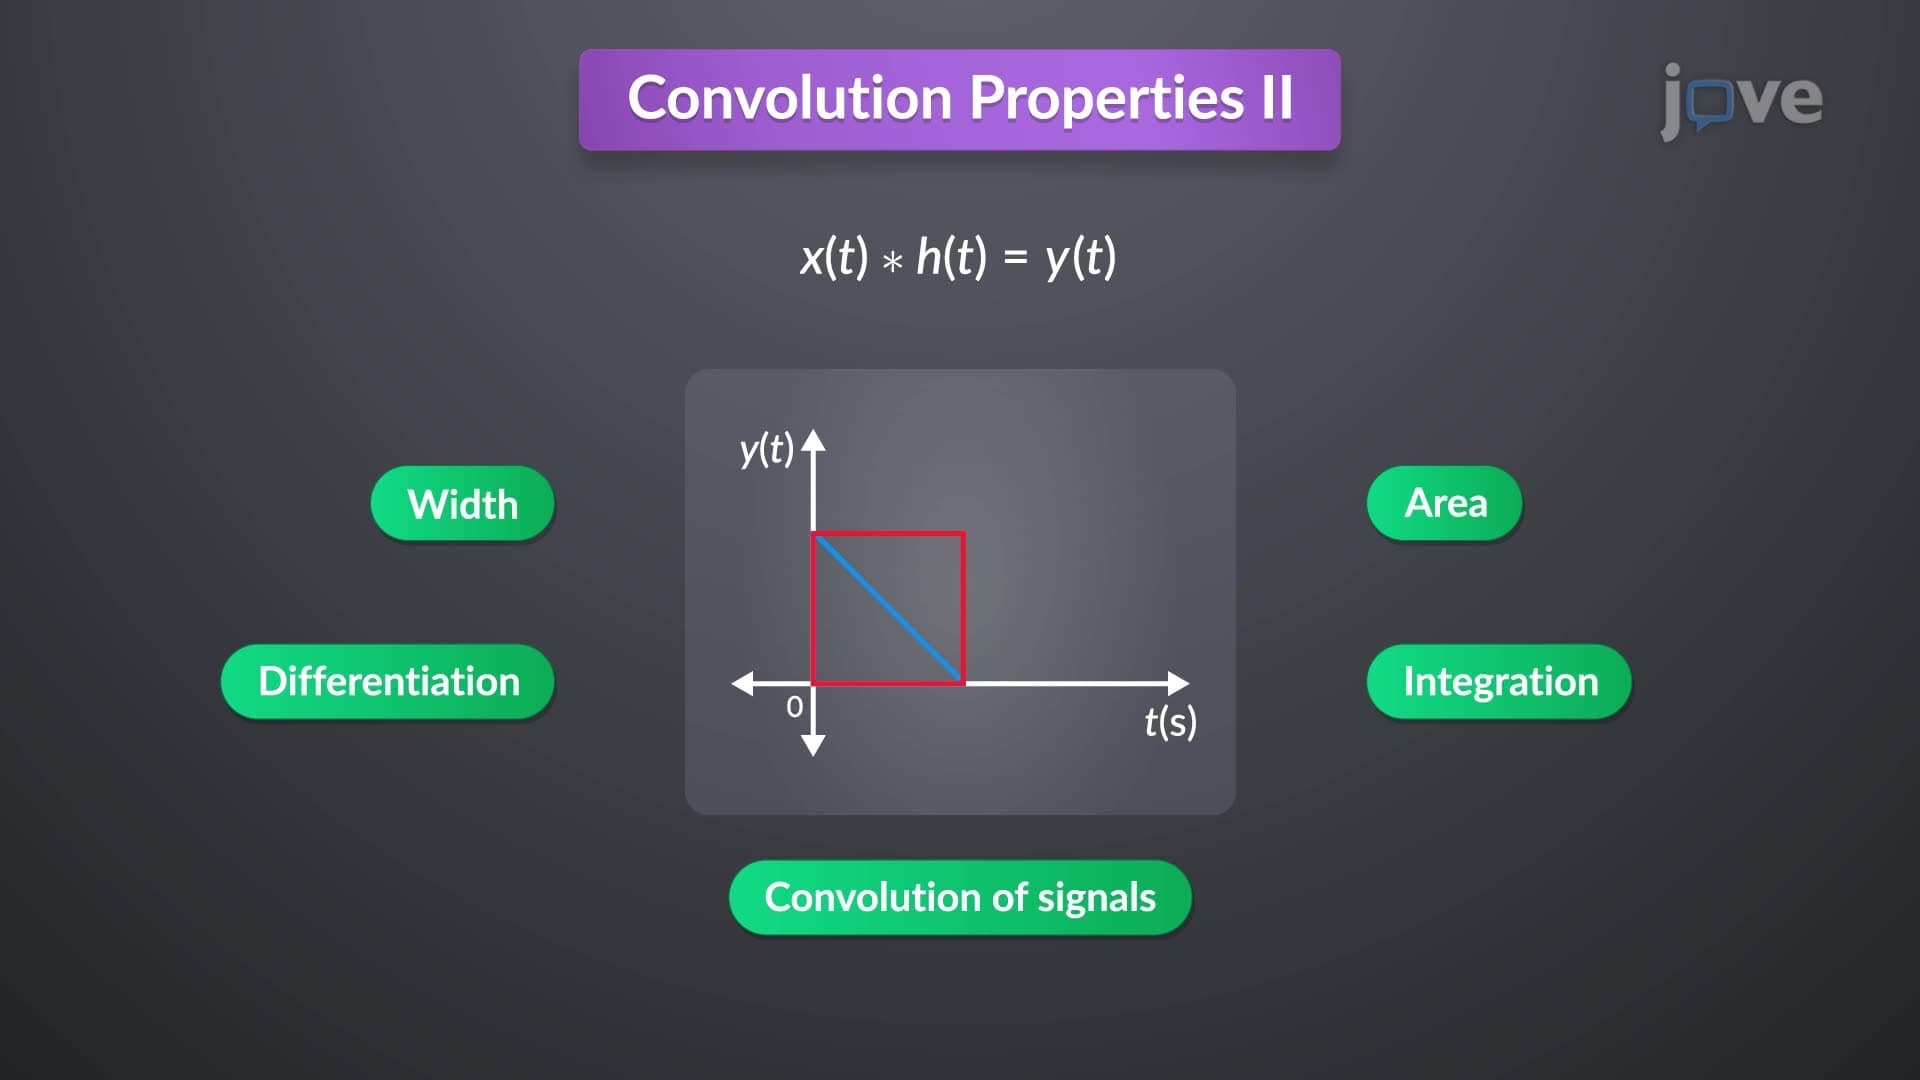
Convolution Properties II
The width property indicates that if the durations of input signals are T1 and T2, then the width of the output response equals the sum of both durations, irrespective of the shapes of the two functions. For instance, convolving two rectangular pulses with durations of 2 seconds and 1 second results in a function with a width of 3 seconds.
The area property asserts that the area under the...
 02:26
Protein Networks
These interactions can be represented through maps depicting protein-protein interaction networks, represented as nodes and edges. Nodes are circles that are representative of a protein,...
 01:20
Convolution Properties I
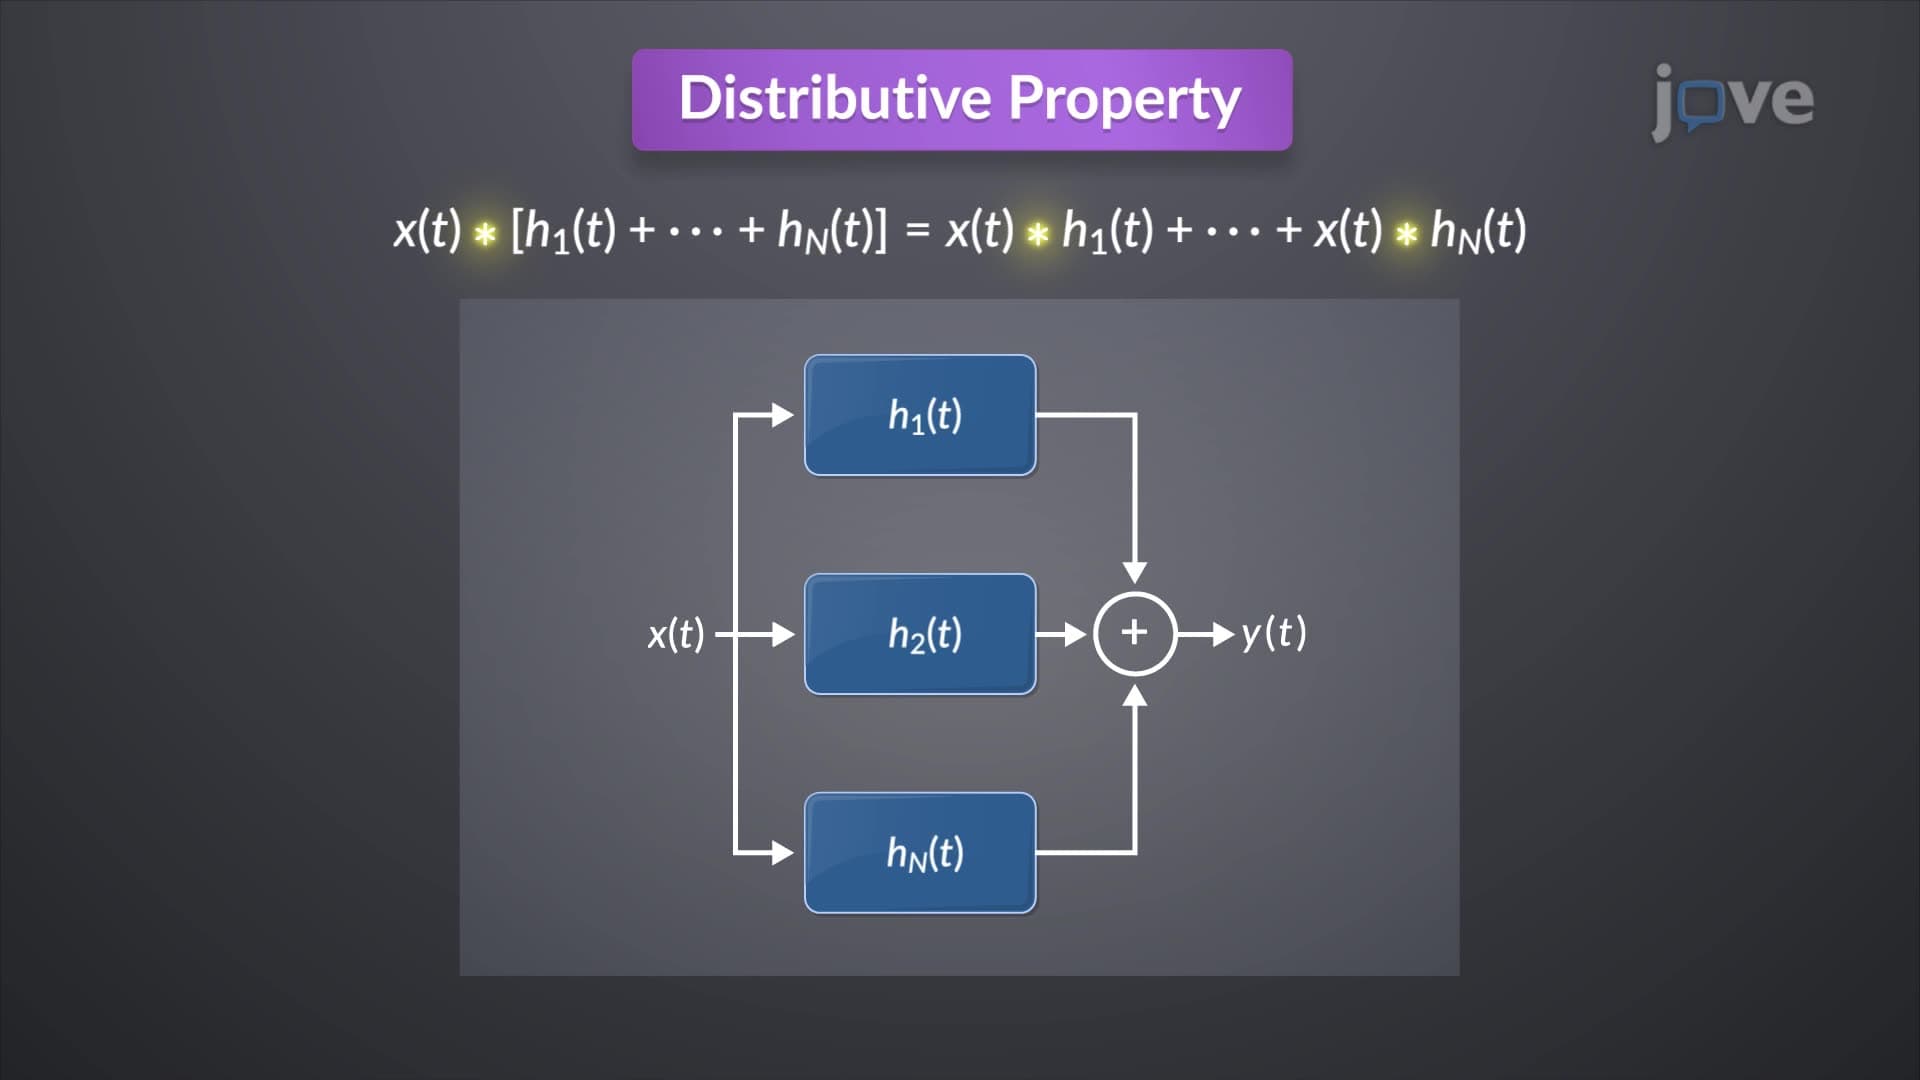
The commutative property reveals that the input and the impulse response of an LTI (Linear Time-Invariant) system can be interchanged without affecting the output:
 02:27
Predicting Molecular Geometry
 02:18
Network Covalent Solids
To break or to melt a covalent network solid, covalent bonds must be broken. Because covalent bonds are relatively strong, covalent network solids are typically...
 01:24
Convolution: Math, Graphics, and Discrete Signals
To simplify the convolution integral, it is assumed that both the input signal and impulse response are zero for negative time values. The graphical convolution process...