Related Experiment Video
Updated: Dec 30, 2025


Large-scale Reconstructions and Independent, Unbiased Clustering Based on Morphological Metrics to Classify Neurons in Selective Populations
Published on: February 15, 2017
Time-Series Clustering Based on the Characterization of Segment Typologies

Abstract:
Time-series clustering is the process of grouping time series with respect to their similarity or characteristics. Previous approaches usually combine a specific distance measure for time series and a standard clustering method. However, these approaches do not take the similarity of the different subsequences of each time series into account, which can be used to better compare the time-series objects of the dataset. In this article, we propose a novel technique of time-series clustering consisting of two clustering stages. In a first step, a least-squares polynomial segmentation procedure is applied to each time series, which is based on a growing window technique that returns different-length segments. Then, all of the segments are projected into the same dimensional space, based on the coefficients of the model that approximates the segment and a set of statistical features. After mapping, a first hierarchical clustering phase is applied to all mapped segments, returning groups of segments for each time series. These clusters are used to represent all time series in the same dimensional space, after defining another specific mapping process. In a second and final clustering stage, all the time-series objects are grouped. We consider internal clustering quality to automatically adjust the main parameter of the algorithm, which is an error threshold for the segmentation. The results obtained on 84 datasets from the UCR Time Series Classification Archive have been compared against three state-of-the-art methods, showing that the performance of this methodology is very promising, especially on larger datasets.

Related Concept Videos
 00:54
Time-Series Graph
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:29
Aggregates Classification
Petrographic classification groups aggregates based on common mineralogical characteristics. Some of the common mineral groups found in aggregates are...
 00:56
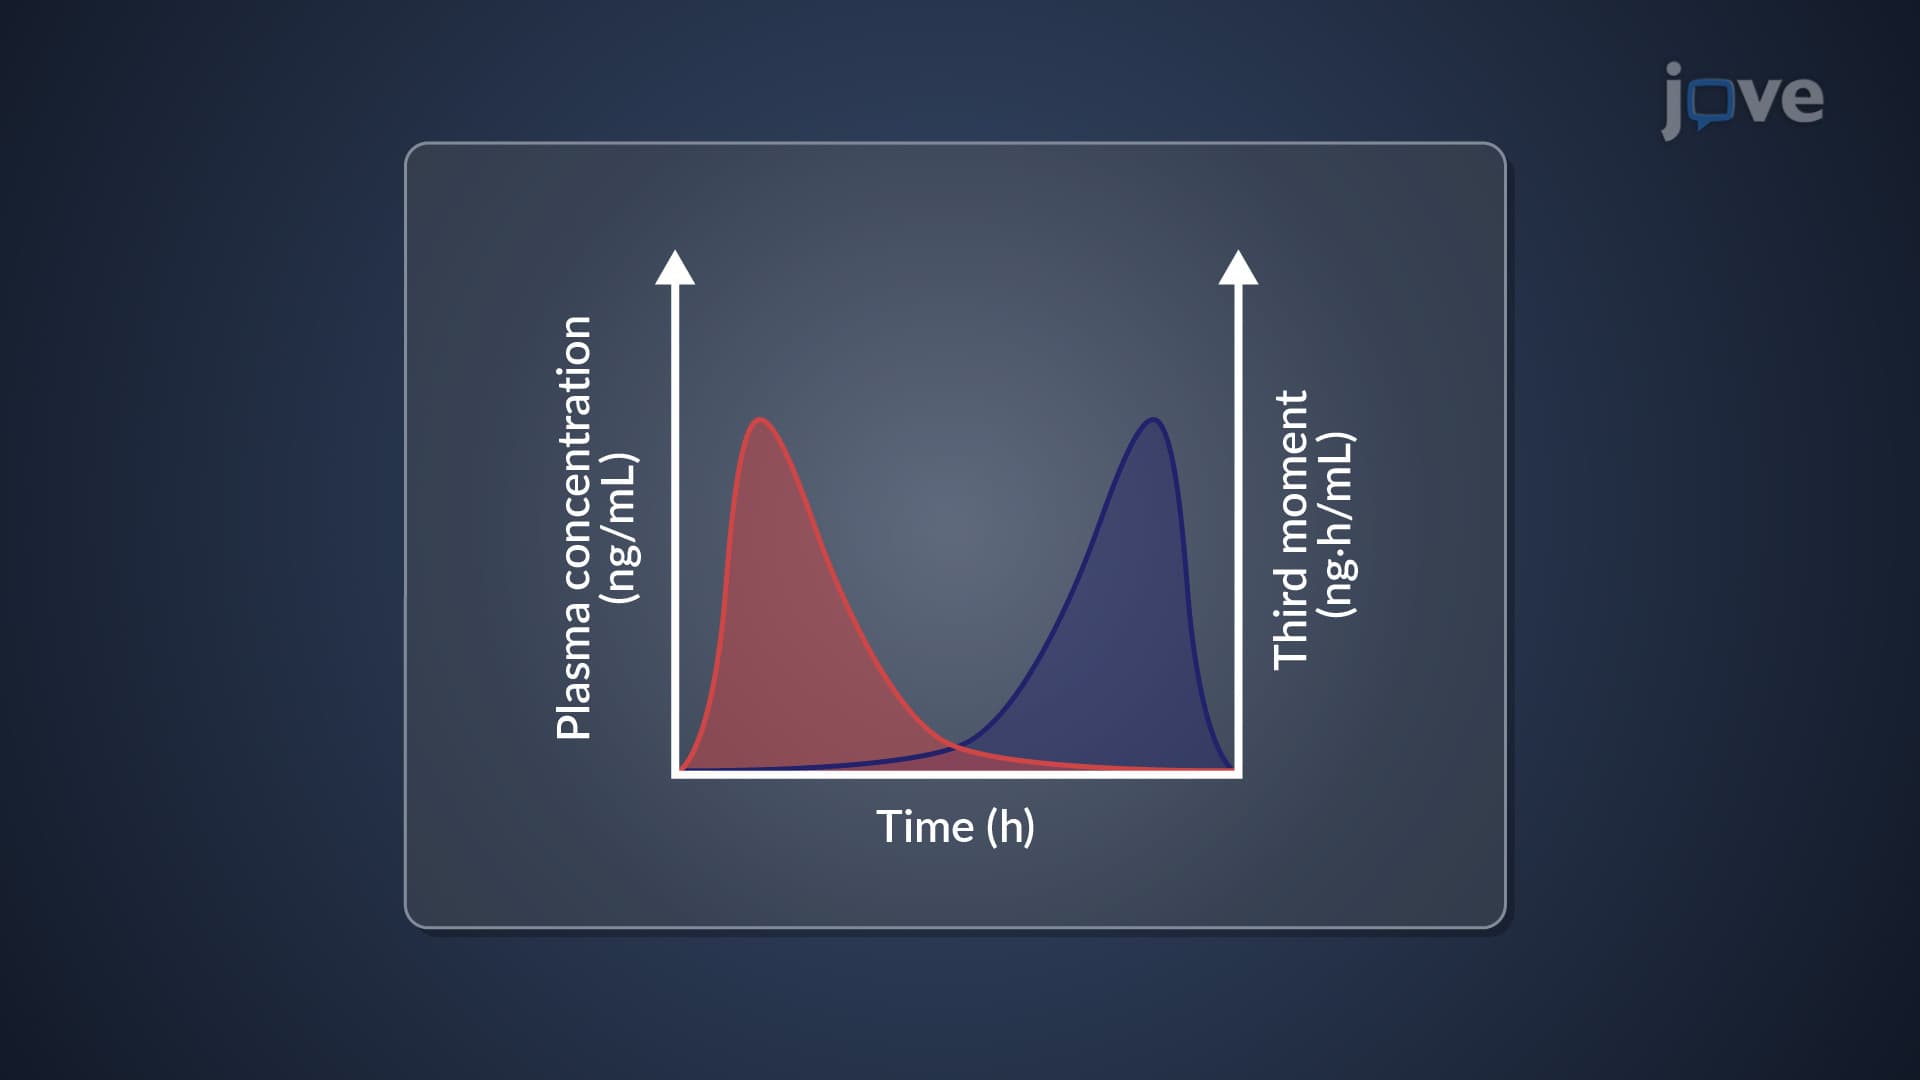
Noncompartmental Analysis: Statistical Moment Theory
 01:29
Modern Molecular Taxonomy
 01:11
How Data are Classified: Categorical Data
Data are classified based on whether they are measurable or not. Categorical data cannot be measured; instead, it can be divided into categories. For example, if Y denotes a person's party affiliation, some examples of Y include...