Related Experiment Video
Updated: Dec 21, 2025

Identification and Classification of Position-specific GABAA Receptor Subunit Missense Variants for Their Role In Hippocampal Pyramidal Neurons
Published on: June 6, 2025
Assessment of databases to determine the validity of β- and γ-carbonic anhydrase sequences from vertebrates
Reza Zolfaghari Emameh1, Marianne Kuuslahti2, Hassan Nosrati3
1Department of Energy and Environmental Biotechnology, National Institute of Genetic Engineering and Biotechnology (NIGEB), Tehran, 14965/161, Iran. zolfaghari@nigeb.ac.ir.

Background:
The inaccuracy of DNA sequence data is becoming a serious problem, as the amount of molecular data is multiplying rapidly and expectations are high for big data to revolutionize life sciences and health care. In this study, we investigated the accuracy of DNA sequence data from commonly used databases using carbonic anhydrase (CA) gene sequences as generic targets. CAs are ancient metalloenzymes that are present in all unicellular and multicellular living organisms. Among the eight distinct families of CAs, including α, β, γ, δ, ζ, η, θ, and ι, only α-CAs have been reported in vertebrates.
Results:
By an in silico analysis performed on the NCBI and Ensembl databases, we identified several β- and γ-CA sequences in vertebrates, including Homo sapiens, Mus musculus, Felis catus, Lipotes vexillifer, Pantholops hodgsonii, Hippocampus comes, Hucho hucho, Oncorhynchus tshawytscha, Xenopus tropicalis, and Rhinolophus sinicus. Polymerase chain reaction (PCR) analysis of genomic DNA persistently failed to amplify positive β- or γ-CA gene sequences when Mus musculus and Felis catus DNA samples were used as templates. Further BLAST homology searches of the database-derived "vertebrate" β- and γ-CA sequences revealed that the identified sequences were presumably derived from gut microbiota, environmental microbiomes, or grassland ecosystems.
Conclusions:
Our results highlight the need for more accurate and fast curation systems for DNA databases. The mined data must be carefully reconciled with our best knowledge of sequences to improve the accuracy of DNA data for publication.
More Related Videos
 07:49
Creating and Applying a Reference to Facilitate the Discussion and Classification of Proteins in a Diverse Group
Published on: August 16, 2017
 16:02
Demonstration of the Sequence Alignment to Predict Across Species Susceptibility Tool for Rapid Assessment of Protein Conservation
Published on: February 10, 2023
Related Concept Videos
 02:54
Evolutionary Relationships through Genome Comparisons
 01:57
Gene Families
Occasionally these regions can be adapted to take on new roles within the organism, becoming novel genes...
 02:47
Protein Families
 02:51
Multi-species Conserved Sequences
Although the genome of each species varies greatly from each other, a few sequences are highly conserved. Such conserved...
 02:21
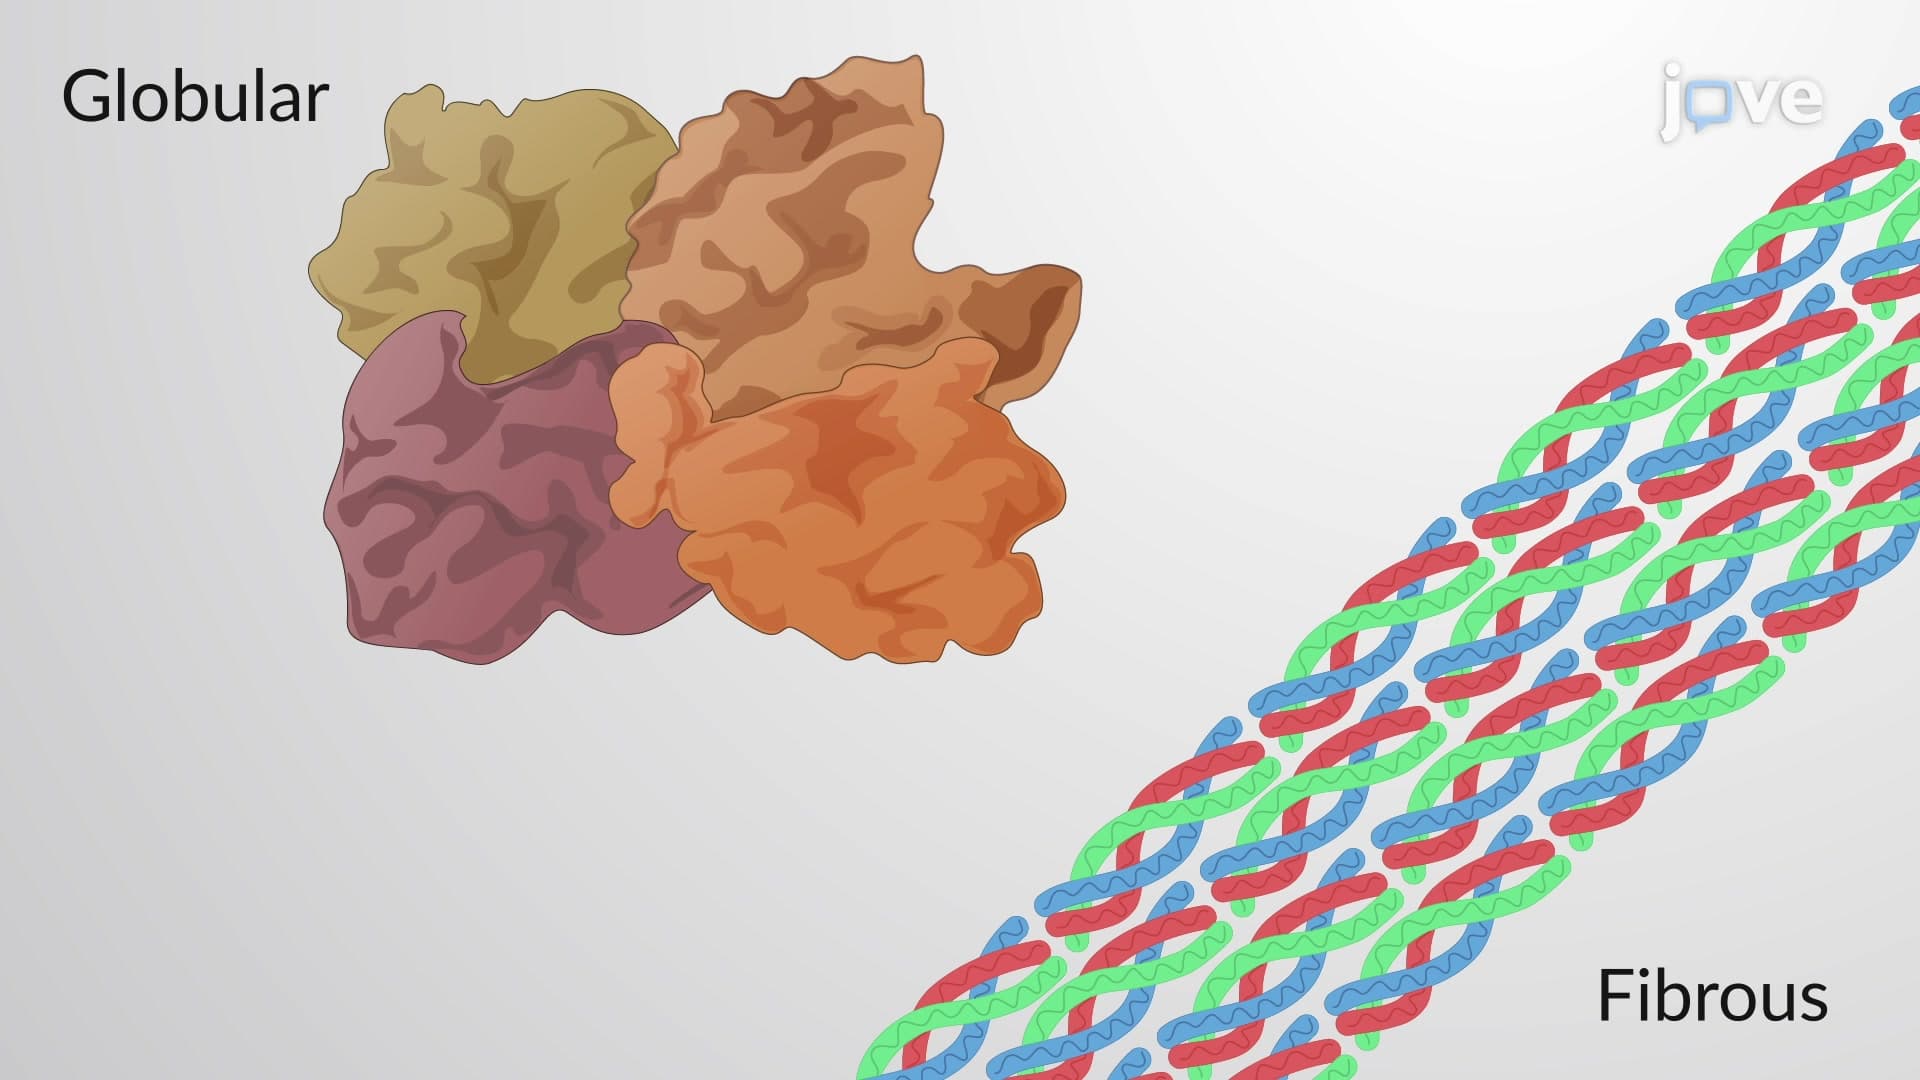
Globular and Fibrous Proteins
Globular proteins are also known as spheroproteins and typically are approximately round in shape. They contain a mix of amino acid types and contain differing sequences in their primary structures. Globular proteins have many different functions, such as enzymes, cellular messengers, and molecular transporters. These roles often require the proteins to be...