Related Experiment Video
Updated: Dec 9, 2025


Detection of Rare Genomic Variants from Pooled Sequencing Using SPLINTER
Published on: June 23, 2012
Understanding between-cluster variation in prevalence and limits for how much variation is plausible
Mark D Chatfield1, Daniel M Farewell2
1Faculty of Medicine, The University of Queensland, Brisbane, Australia.

Abstract:
In clinical trials and observational studies of clustered binary data, understanding between-cluster variation is essential: in sample size and power calculations of cluster randomised trials, for example, the intra-cluster correlation coefficient is often specified. However, quantifications of between-cluster variation can be unintuitive, and an intra-cluster correlation coefficient as low as 0.04 may correspond to surprisingly large between-cluster differences. We suggest that understanding is improved through visualising the implied distribution of true cluster prevalences - possibly by assuming they follow a beta distribution - or by calculating their standard deviation, which is more readily interpretable than the intra-cluster correlation coefficient. Even so, the bounded nature of binary data complicates the interpretation of variances as primary measures of uncertainty, and entropy offers an attractive alternative. Appealing to maximum entropy theory, we propose the following rule of thumb: that plausible intra-cluster correlation coefficients and standard deviations of true cluster prevalences are both bounded above by the overall prevalence, its complement, and one third. We also provide corresponding bounds for the coefficient of variation, and for a different standard deviation and intra-cluster correlation defined on the log odds scale. Using previously published data, we observe the quantities defined on the log odds scale to be more transportable between studies with different outcomes with different prevalences than the intra-cluster correlation and coefficient of variation. The latter increase and decrease, respectively, as prevalence increases from 0% to 50%, and the same is true for our bounds. Our work will help clinical trialists better understand between-cluster variation and avoid specifying implausibly high values for the intra-cluster correlation in sample size and power calculations.
Related Concept Videos
 01:11
Variability: Analysis
The range is a simple measure of variability, indicating the difference between the highest and...
 01:14
What is Variation?
The range, standard deviation, standard error, and variance are the different measures of variation.
Range: The range is the difference between its maximum and...
 00:54
Uncertainty: Confidence Intervals
 01:16
Unusual Results
According to the range rule of thumb, any value above or below two standard deviations, 2σ from the mean, μ is considered unusual.
Maximum unusual value =...
 01:21
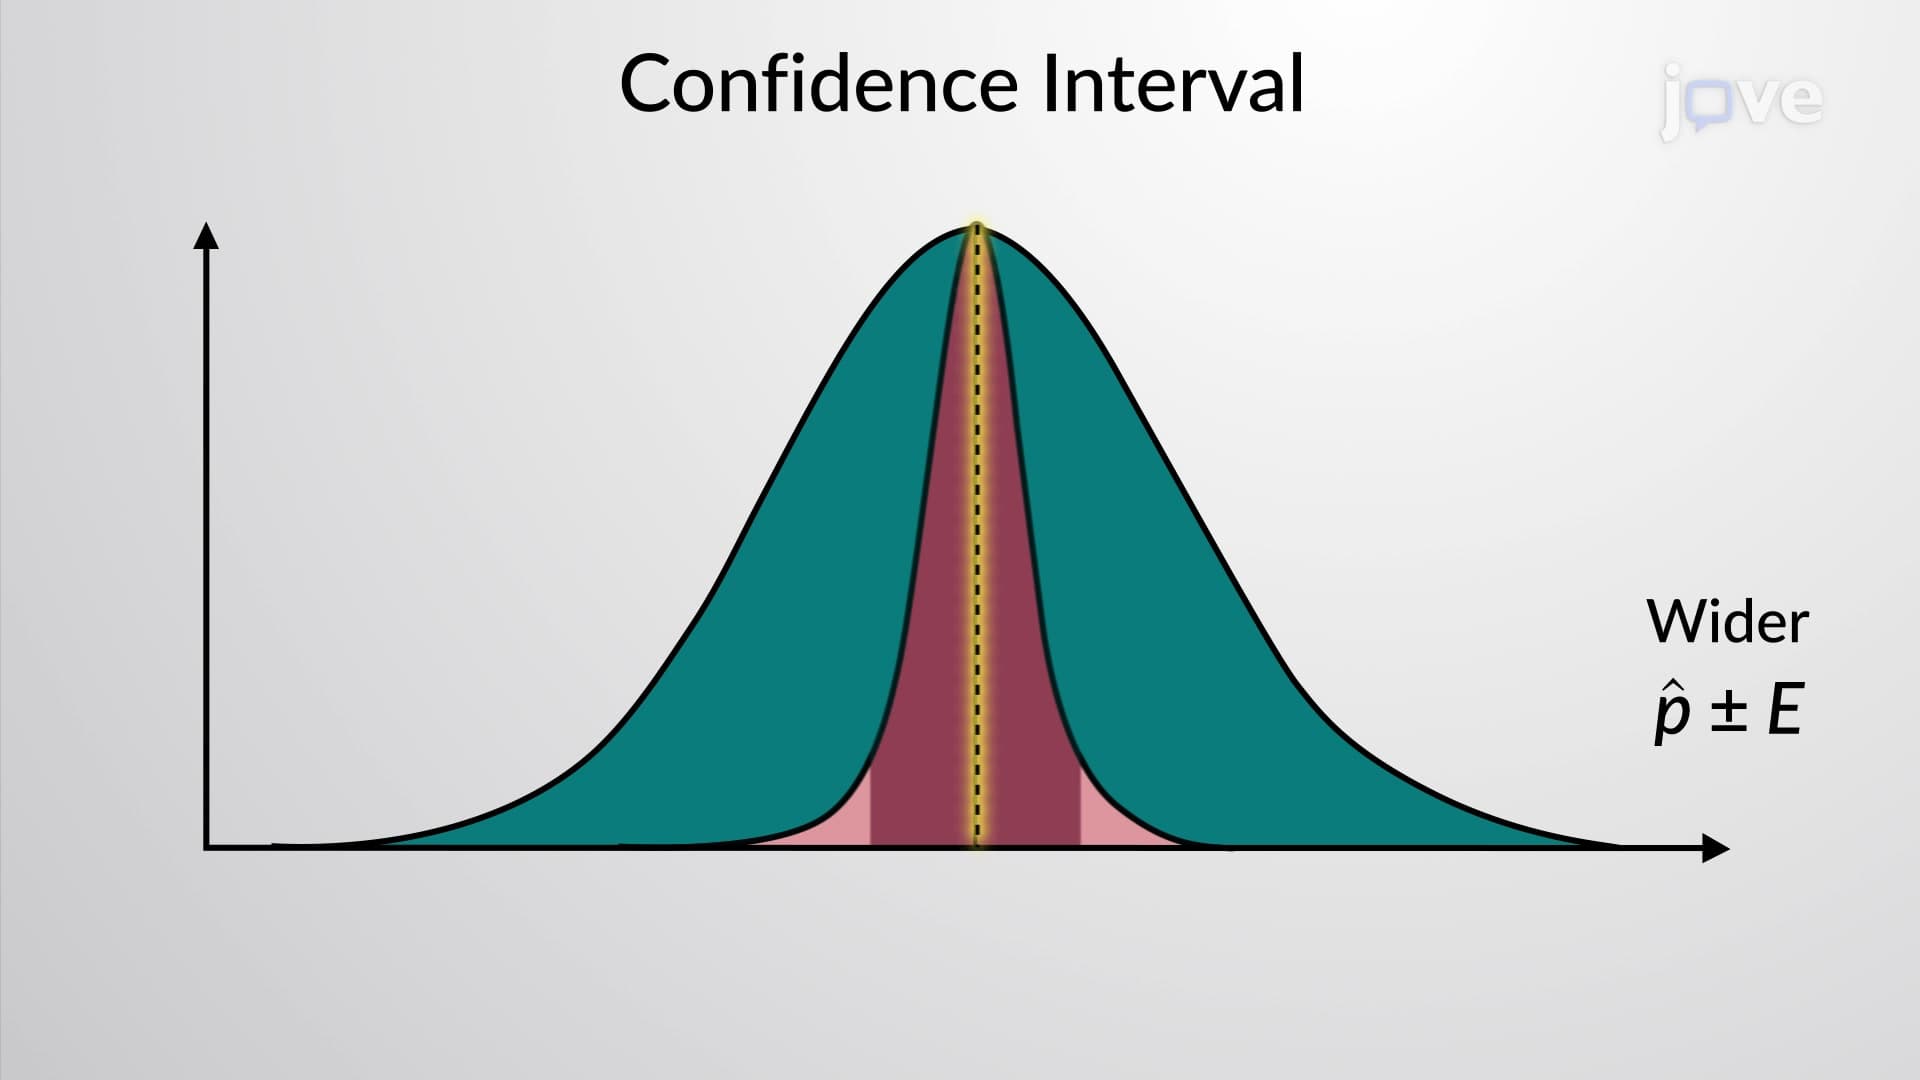
Confidence Intervals
A...
 01:19
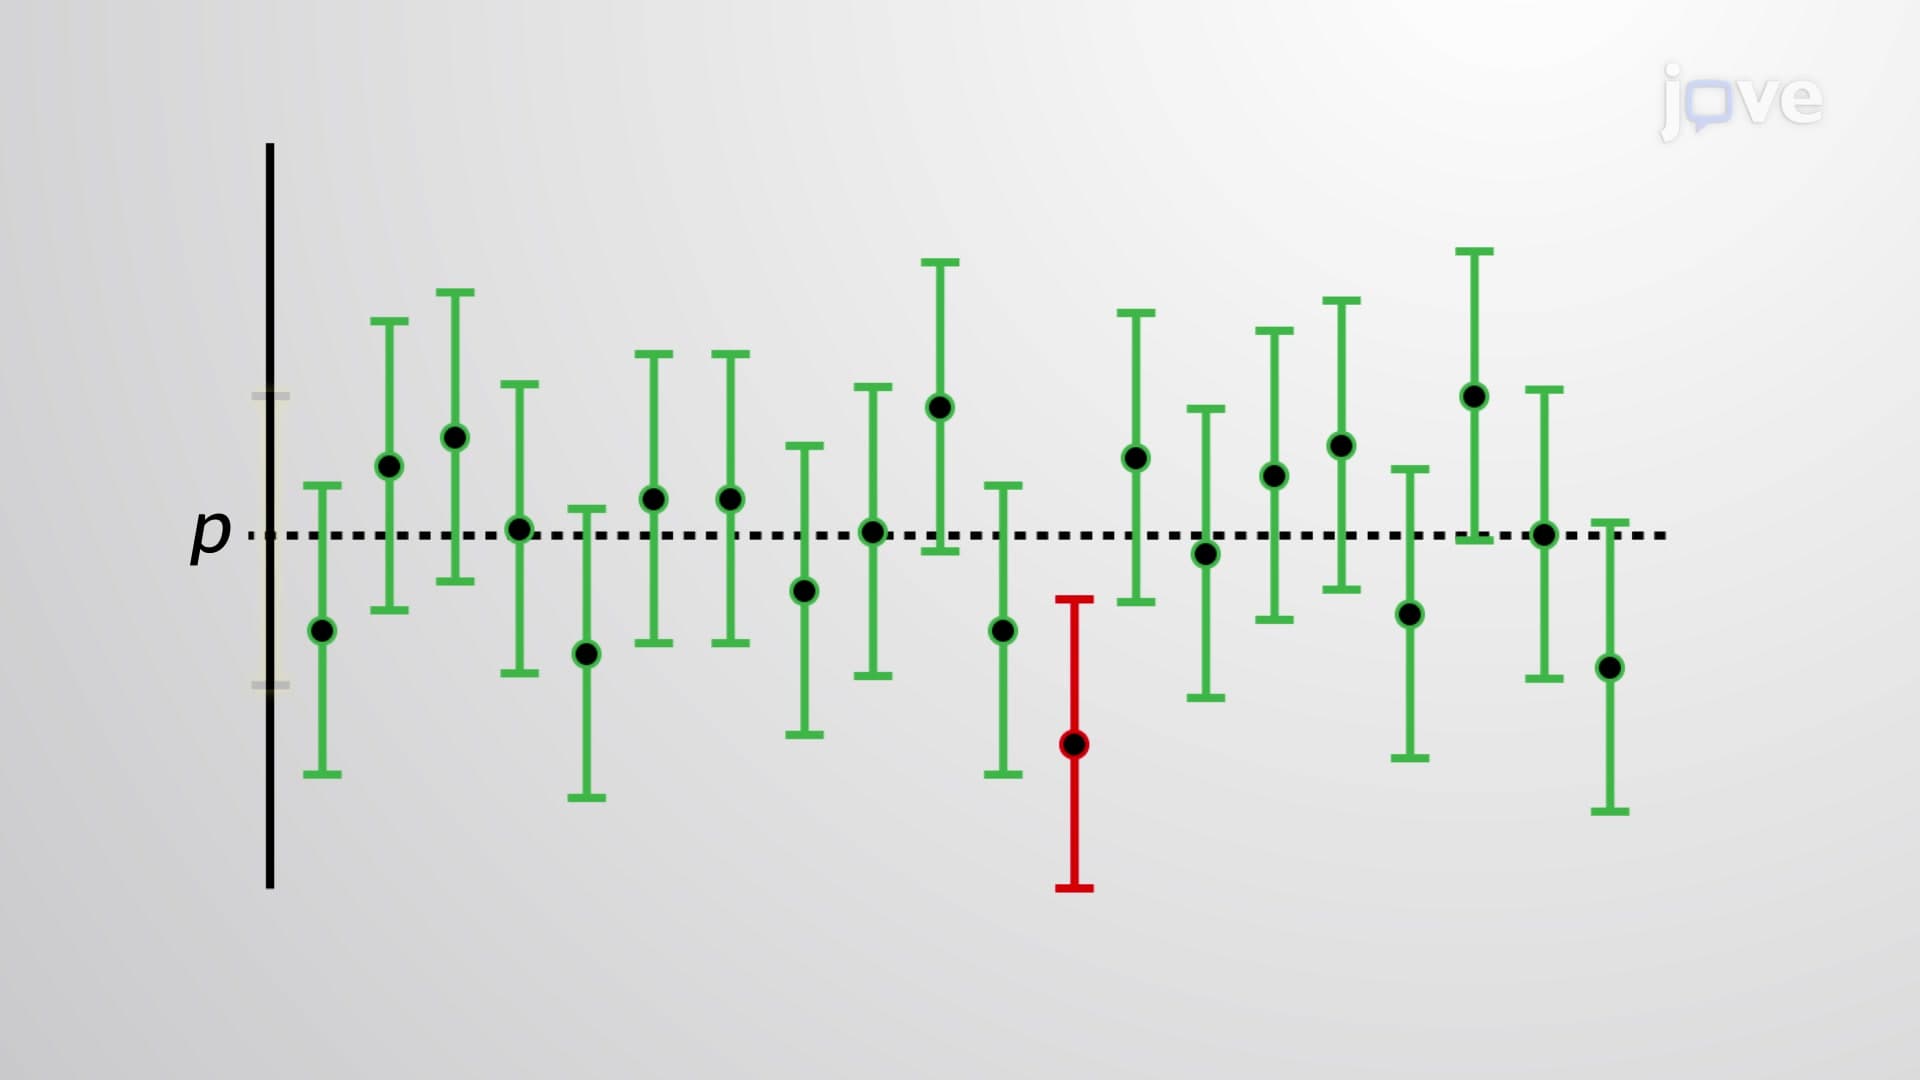
Interpretation of Confidence Intervals
Confidence intervals have confidence coefficients that are crucial for their interpretation. The most common confidence coefficients are 0.90, 0.95, and 0.99, which can be written as percentages–90%, 95%, and 99%, respectively.
Suppose a person calculates a confidence interval with a confidence coefficient of 0.95. In that case, they can...