Related Experiment Video
Updated: Dec 6, 2025
Basics of Multivariate Analysis in Neuroimaging Data
Published on: July 24, 2010
Visual Analysis of Large Multivariate Scattered Data using Clustering and Probabilistic Summaries

Abstract:
Rapidly growing data sizes of scientific simulations pose significant challenges for interactive visualization and analysis techniques. In this work, we propose a compact probabilistic representation to interactively visualize large scattered datasets. In contrast to previous approaches that represent blocks of volumetric data using probability distributions, we model clusters of arbitrarily structured multivariate data. In detail, we discuss how to efficiently represent and store a high-dimensional distribution for each cluster. We observe that it suffices to consider low-dimensional marginal distributions for two or three data dimensions at a time to employ common visual analysis techniques. Based on this observation, we represent high-dimensional distributions by combinations of low-dimensional Gaussian mixture models. We discuss the application of common interactive visual analysis techniques to this representation. In particular, we investigate several frequency-based views, such as density plots in 1D and 2D, density-based parallel coordinates, and a time histogram. We visualize the uncertainty introduced by the representation, discuss a level-of-detail mechanism, and explicitly visualize outliers. Furthermore, we propose a spatial visualization by splatting anisotropic 3D Gaussians for which we derive a closed-form solution. Lastly, we describe the application of brushing and linking to this clustered representation. Our evaluation on several large, real-world datasets demonstrates the scaling of our approach.
Related Concept Videos
 01:15
Scatter Plot
 01:11
Statistical Analysis: Overview
One of the most commonly used statistical quantifiers is the mean, which is the ratio between the sum of the numerical values of all results and the...
 01:17
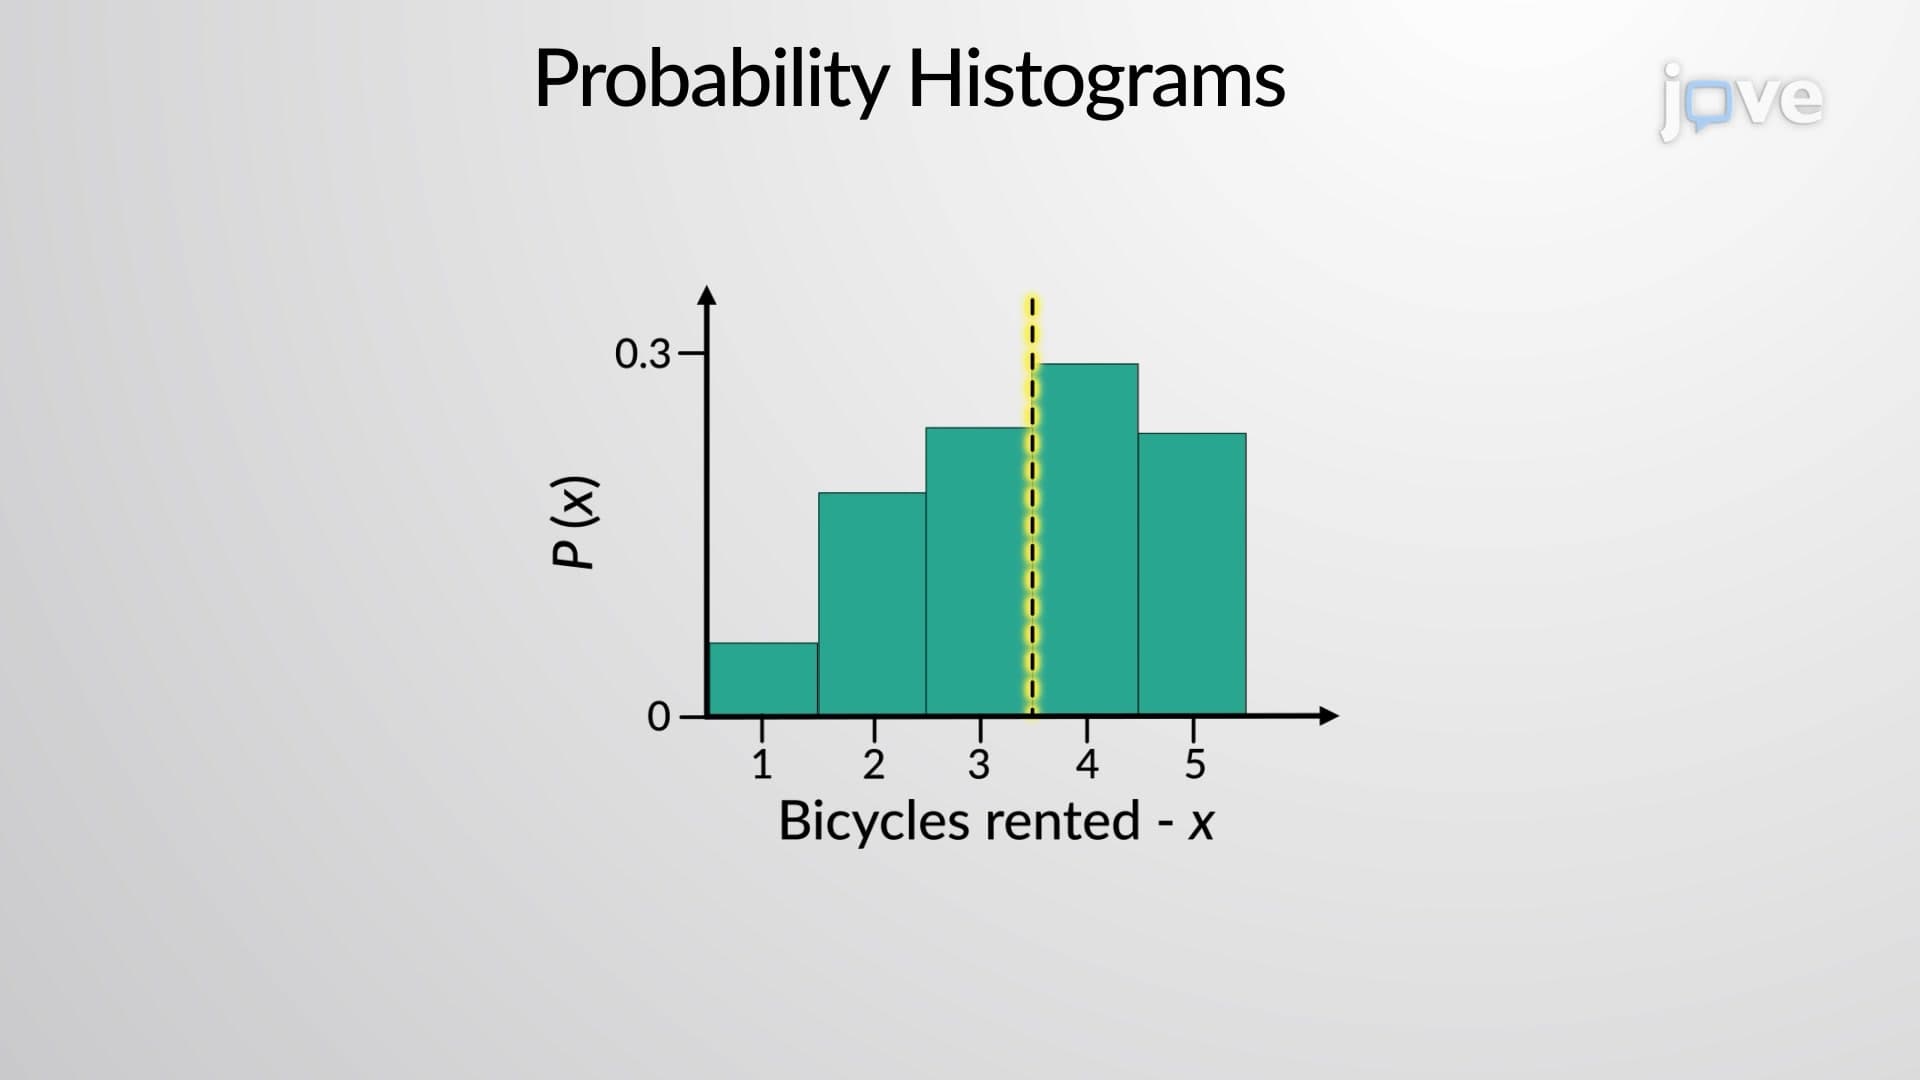
Probability Histograms
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:11
Variability: Analysis
The range is a simple measure of variability, indicating the difference between the highest and...
 01:13
Review and Preview