Related Experiment Video
Updated: Nov 28, 2025

Selecting Multiple Biomarker Subsets with Similarly Effective Binary Classification Performances
Published on: October 11, 2018
ROC and AUC with a Binary Predictor: a Potentially Misleading Metric
1Department of Biostatistics, Johns Hopkins Bloomberg School of Public Health, 615 N Wolfe St, Baltimore, MD 21205.

Abstract:
In analysis of binary outcomes, the receiver operator characteristic (ROC) curve is heavily used to show the performance of a model or algorithm. The ROC curve is informative about the performance over a series of thresholds and can be summarized by the area under the curve (AUC), a single number. When a predictor is categorical, the ROC curve has one less than number of categories as potential thresholds; when the predictor is binary there is only one threshold. As the AUC may be used in decision-making processes on determining the best model, it important to discuss how it agrees with the intuition from the ROC curve. We discuss how the interpolation of the curve between thresholds with binary predictors can largely change the AUC. Overall, we show using a linear interpolation from the ROC curve with binary predictors corresponds to the estimated AUC, which is most commonly done in software, which we believe can lead to misleading results. We compare R, Python, Stata, and SAS software implementations. We recommend using reporting the interpolation used and discuss the merit of using the step function interpolator, also referred to as the "pessimistic" approach by Fawcett (2006).
More Related Videos

Related Concept Videos
 01:15
Receiver Operating Characteristic Plot
 01:13
Sensitivity, Specificity, and Predicted Value
Sensitivity is the...
 01:52
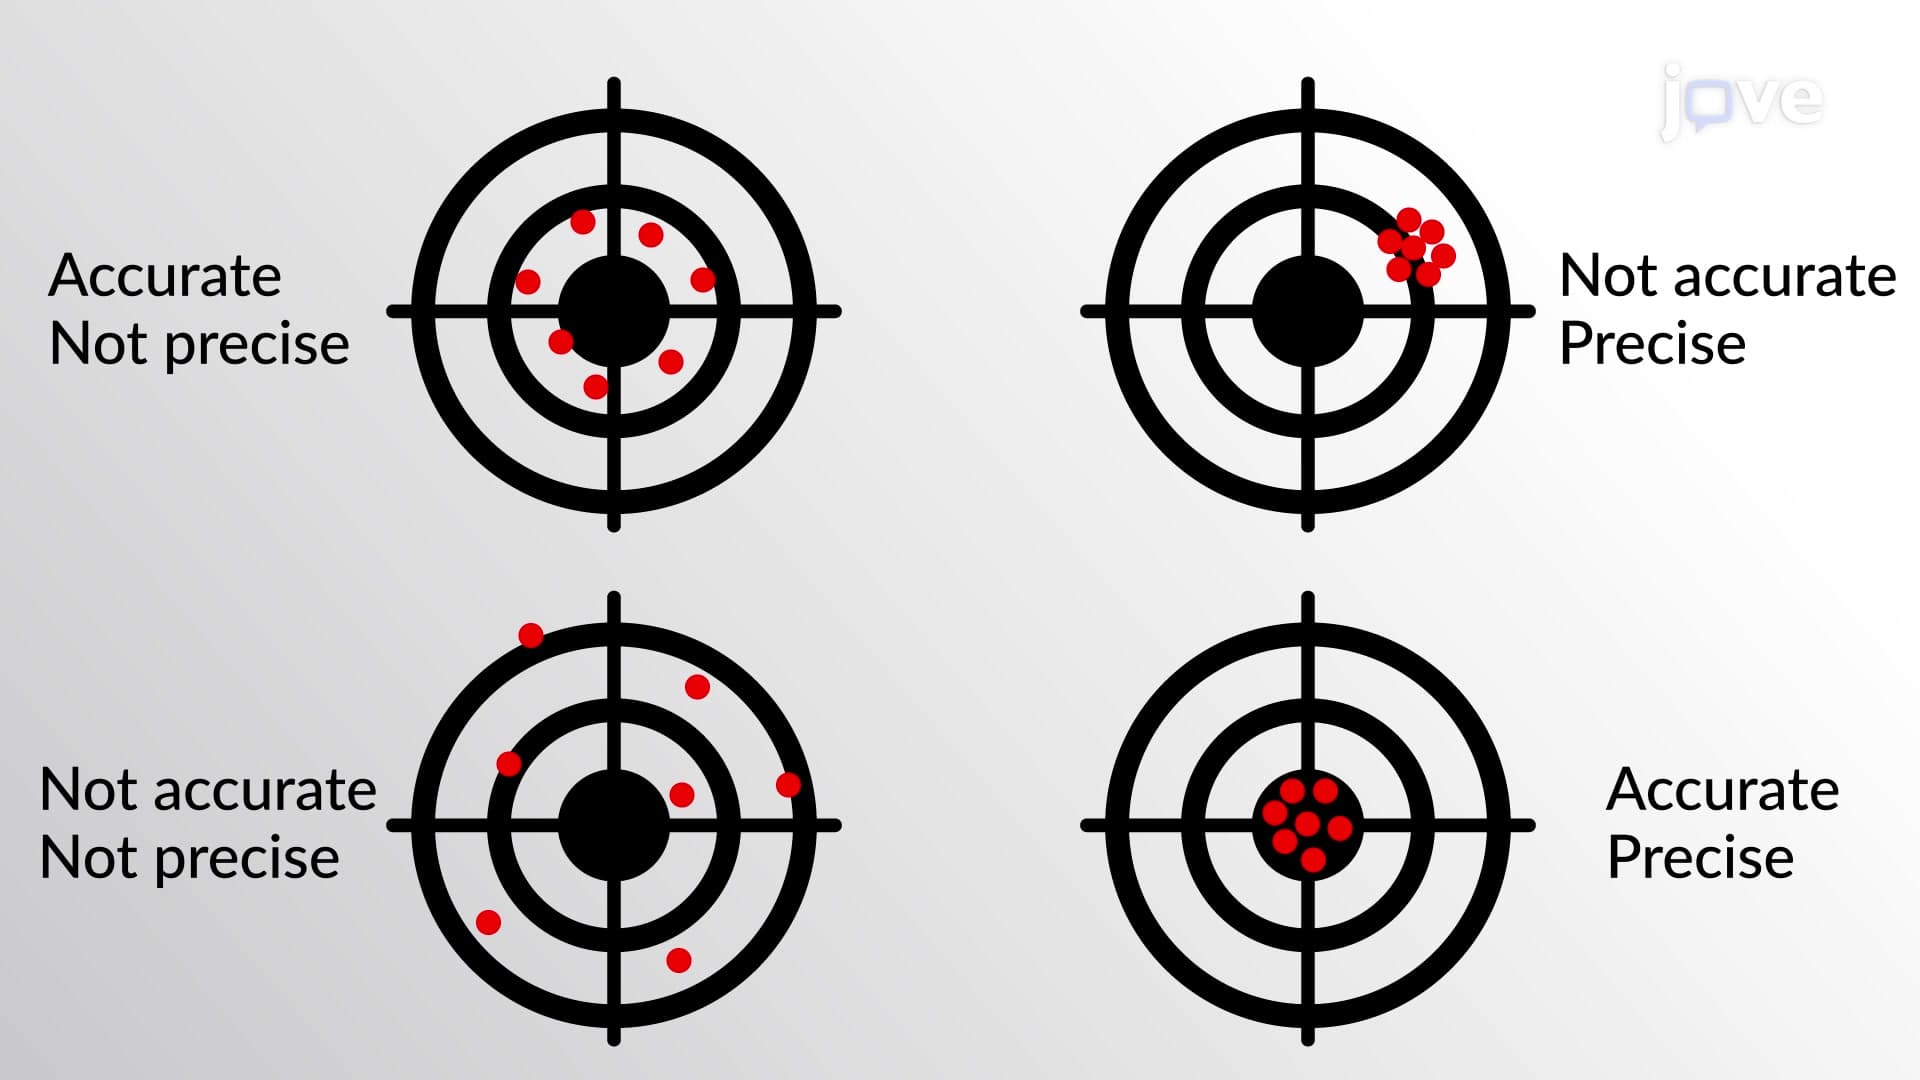
Accuracy and Precision
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
 01:19
Expected Frequencies in Goodness-of-Fit Tests