Related Experiment Video
Updated: Nov 26, 2025


Trajectory Data Analyses for Pedestrian Space-time Activity Study
Published on: February 25, 2013
Deconvoluting kernel density estimation and regression for locally differentially private data
1Department of Electrical and Electronic Engineering, The University of Melbourne, Parkville, VIC, 3010, Australia. farhad.farokhi@unimelb.edu.au.

Abstract:
Local differential privacy has become the gold-standard of privacy literature for gathering or releasing sensitive individual data points in a privacy-preserving manner. However, locally differential data can twist the probability density of the data because of the additive noise used to ensure privacy. In fact, the density of privacy-preserving data (no matter how many samples we gather) is always flatter in comparison with the density function of the original data points due to convolution with privacy-preserving noise density function. The effect is especially more pronounced when using slow-decaying privacy-preserving noises, such as the Laplace noise. This can result in under/over-estimation of the heavy-hitters. This is an important challenge facing social scientists due to the use of differential privacy in the 2020 Census in the United States. In this paper, we develop density estimation methods using smoothing kernels. We use the framework of deconvoluting kernel density estimators to remove the effect of privacy-preserving noise. This approach also allows us to adapt the results from non-parametric regression with errors-in-variables to develop regression models based on locally differentially private data. We demonstrate the performance of the developed methods on financial and demographic datasets.
More Related Videos
Related Concept Videos
 01:26
Distributions to Estimate Population Parameter
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
On...
 01:20
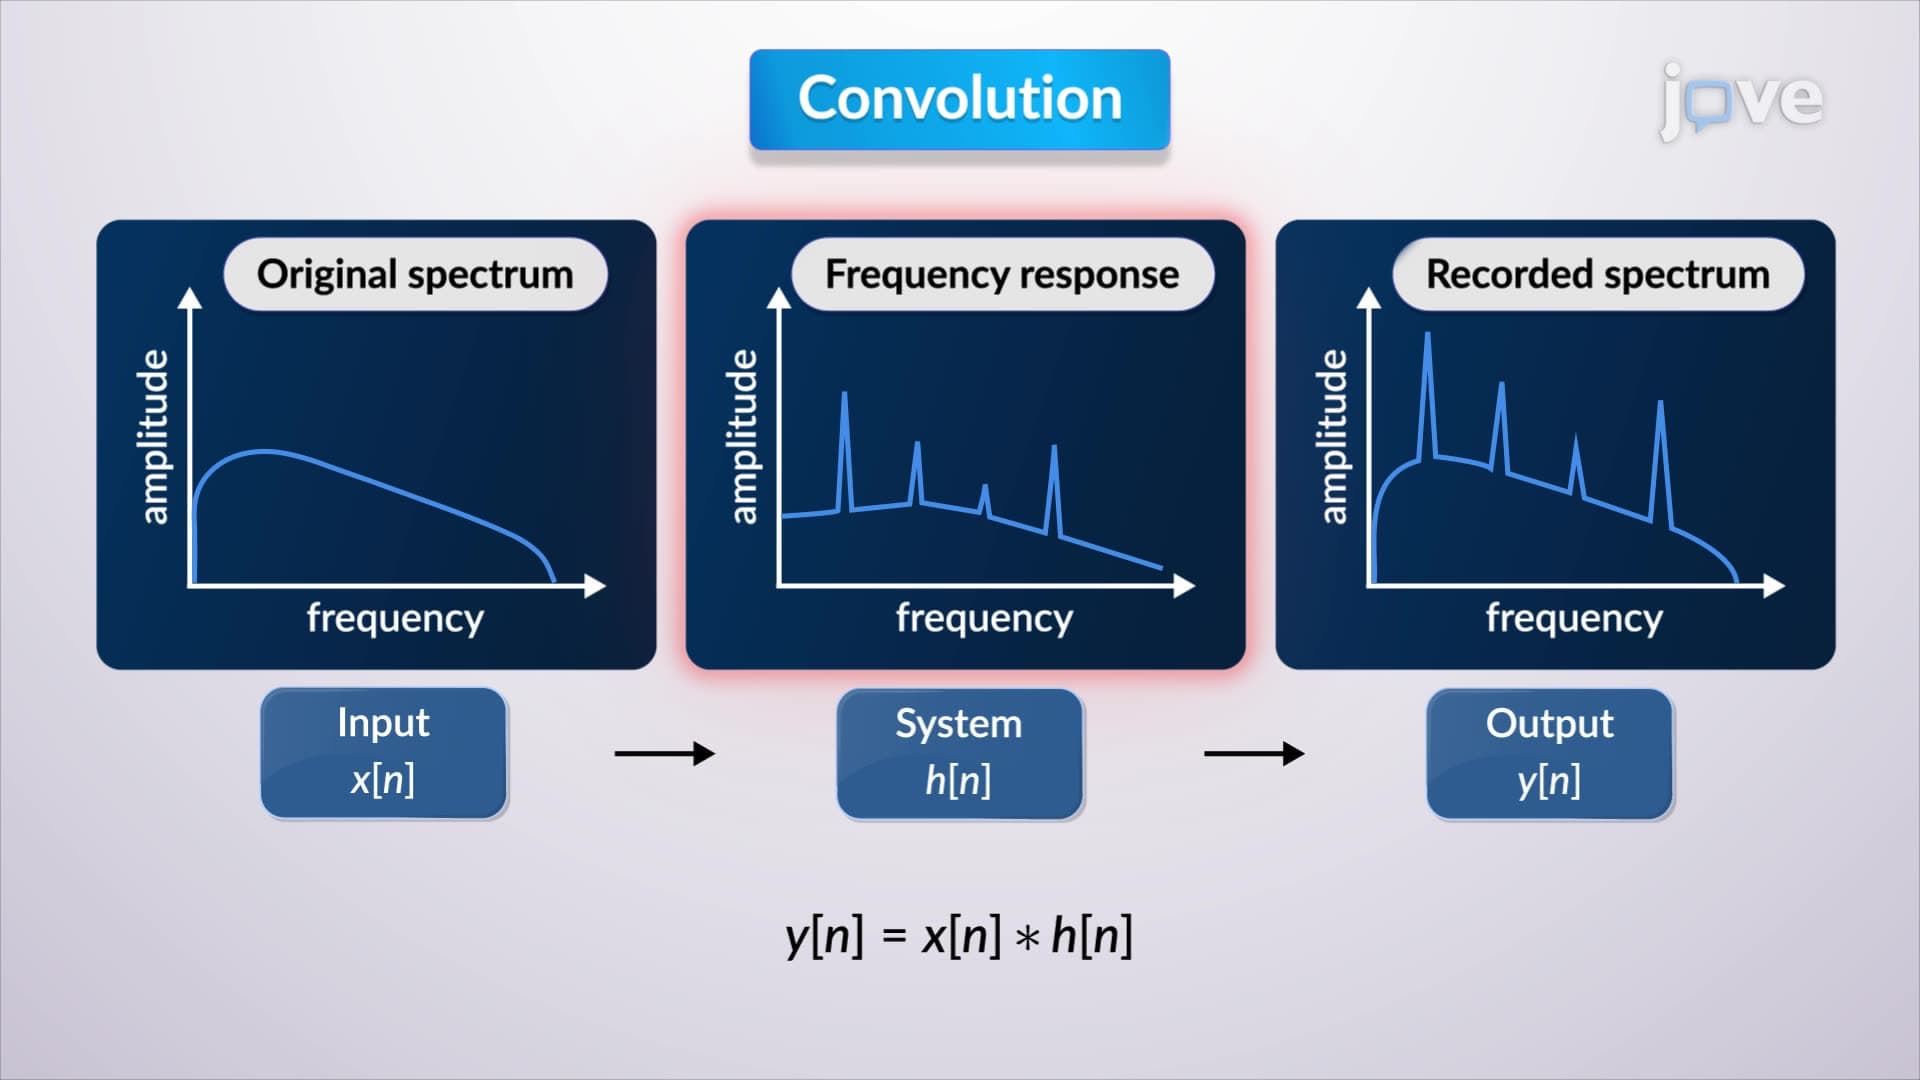
Deconvolution
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
 01:06
Model Approaches for Pharmacokinetic Data: Distributed Parameter Models
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...