Related Experiment Video
Updated: Nov 23, 2025

A Method of Trigonometric Modelling of Seasonal Variation Demonstrated with Multiple Sclerosis Relapse Data
Published on: December 9, 2015
A logistic model and predictions for the spread of the COVID-19 pandemic
1Los Alamos National Laboratory, Los Alamos, New Mexico 87545, USA.

Abstract:
The rapid spread of COVID-19 worldwide presents a great challenge to epidemic modelers. Model outcomes vary widely depending on the characteristics of a pathogen and the models. Here, we present a logistic model for the epidemic spread and divide the spread of the novel coronavirus into two phases: the first phase is a natural exponential growth phase that occurs in the absence of intervention and the second phase is a regulated growth phase that is affected by enforcing social distancing and isolation. We apply the model to a number of pandemic centers. Our results are in good agreement with the data to date and show that social distancing significantly reduces the epidemic spread and flattens the curve. Predictions on the spreading trajectory including the total infections and peak time of new infections for a community of any size are made weeks ahead, providing the vital information and lead time needed to prepare for and mitigate the epidemic. The methodology presented here has immediate and far-reaching applications for ongoing outbreaks or similar future outbreaks of other emergent infectious diseases.
Related Concept Videos
 01:18
Steps in Outbreak Investigation
 02:33
Exponential Equations for Modeling Growth
 00:57
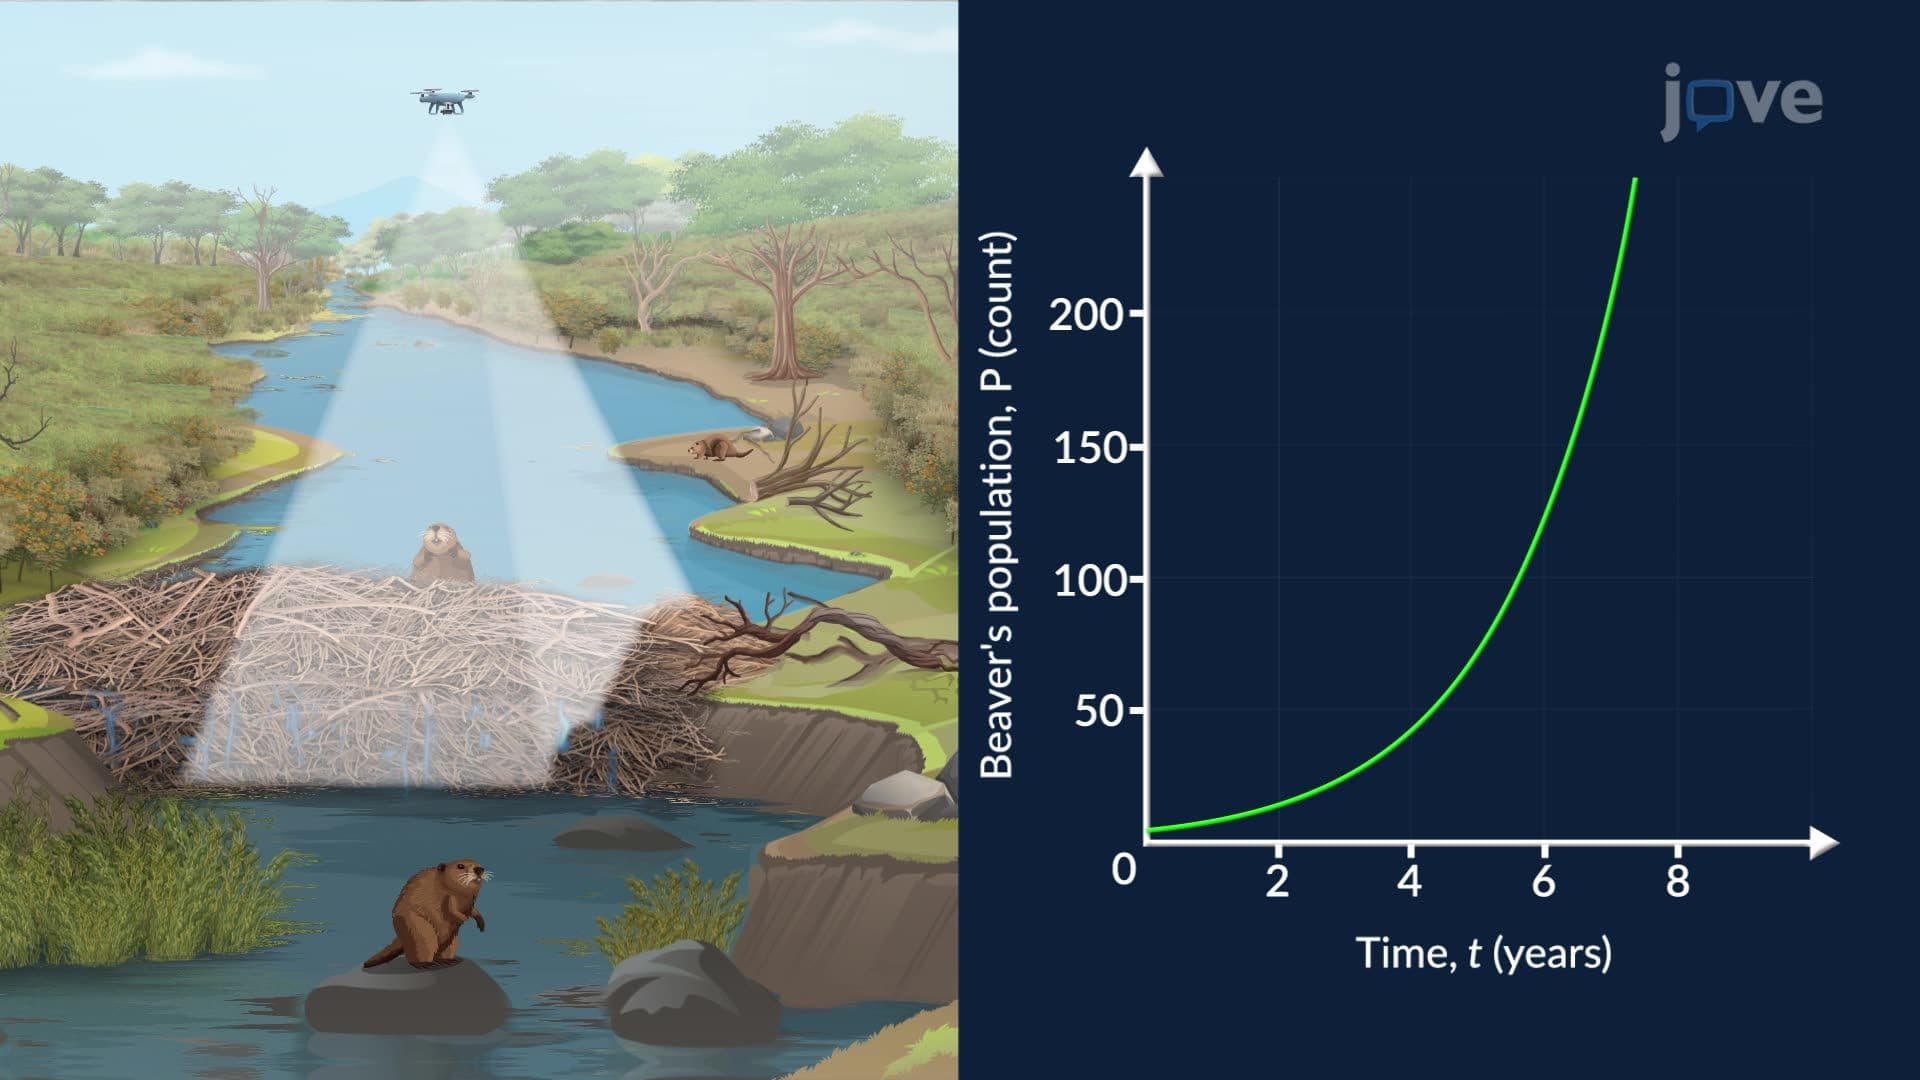
Population Growth
 01:29
Exponential Equations with Logarithms: Problem Solving
 01:14
Parametric Survival Analysis: Weibull and Exponential Methods
Weibull Distribution
The Weibull distribution is a flexible model used in parametric survival analysis. It can handle both increasing and decreasing hazard rates, depending on its shape parameter...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...