Related Experiment Video
Updated: Nov 4, 2025

Measuring the Subjective Value of Risky and Ambiguous Options using Experimental Economics and Functional MRI Methods
Published on: September 19, 2012
How vague is vague? How informative is informative? Reference analysis for Bayesian meta-analysis
Manuela Ott1, Martyn Plummer2, Małgorzata Roos1
1Department of Biostatistics at Epidemiology, Biostatistics and Prevention Institute, University of Zurich, Zurich, Switzerland.

Abstract:
Meta-analysis provides important insights for evidence-based medicine by synthesizing evidence from multiple studies which address the same research question. Within the Bayesian framework, meta-analysis is frequently expressed by a Bayesian normal-normal hierarchical model (NNHM). Recently, several publications have discussed the choice of the prior distribution for the between-study heterogeneity in the Bayesian NNHM and used several "vague" priors. However, no approach exists to quantify the informativeness of such priors, and thus, we develop a principled reference analysis framework for the Bayesian NNHM acting at the posterior level. The posterior reference analysis (post-RA) is based on two posterior benchmarks: one induced by the improper reference prior, which is minimally informative for the data, and the other induced by a highly anticonservative proper prior. This approach applies the Hellinger distance to quantify the informativeness of a heterogeneity prior of interest by comparing the corresponding marginal posteriors with both posterior benchmarks. The post-RA is implemented in the freely accessible R package ra4bayesmeta and is applied to two medical case studies. Our findings show that anticonservative heterogeneity priors produce platykurtic posteriors compared with the reference posterior, and they produce shorter 95% credible intervals (CrI) and optimistic inference compared with the reference prior. Conservative heterogeneity priors produce leptokurtic posteriors, longer 95% CrI and cautious inference. The novel post-RA framework could support numerous Bayesian meta-analyses in many research fields, as it determines how informative a heterogeneity prior is for the actual data as compared with the minimally informative reference prior.

Related Concept Videos
 01:11
Statistical Analysis: Overview
One of the most commonly used statistical quantifiers is the mean, which is the ratio between the sum of the numerical values of all results and the...
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...
 01:16
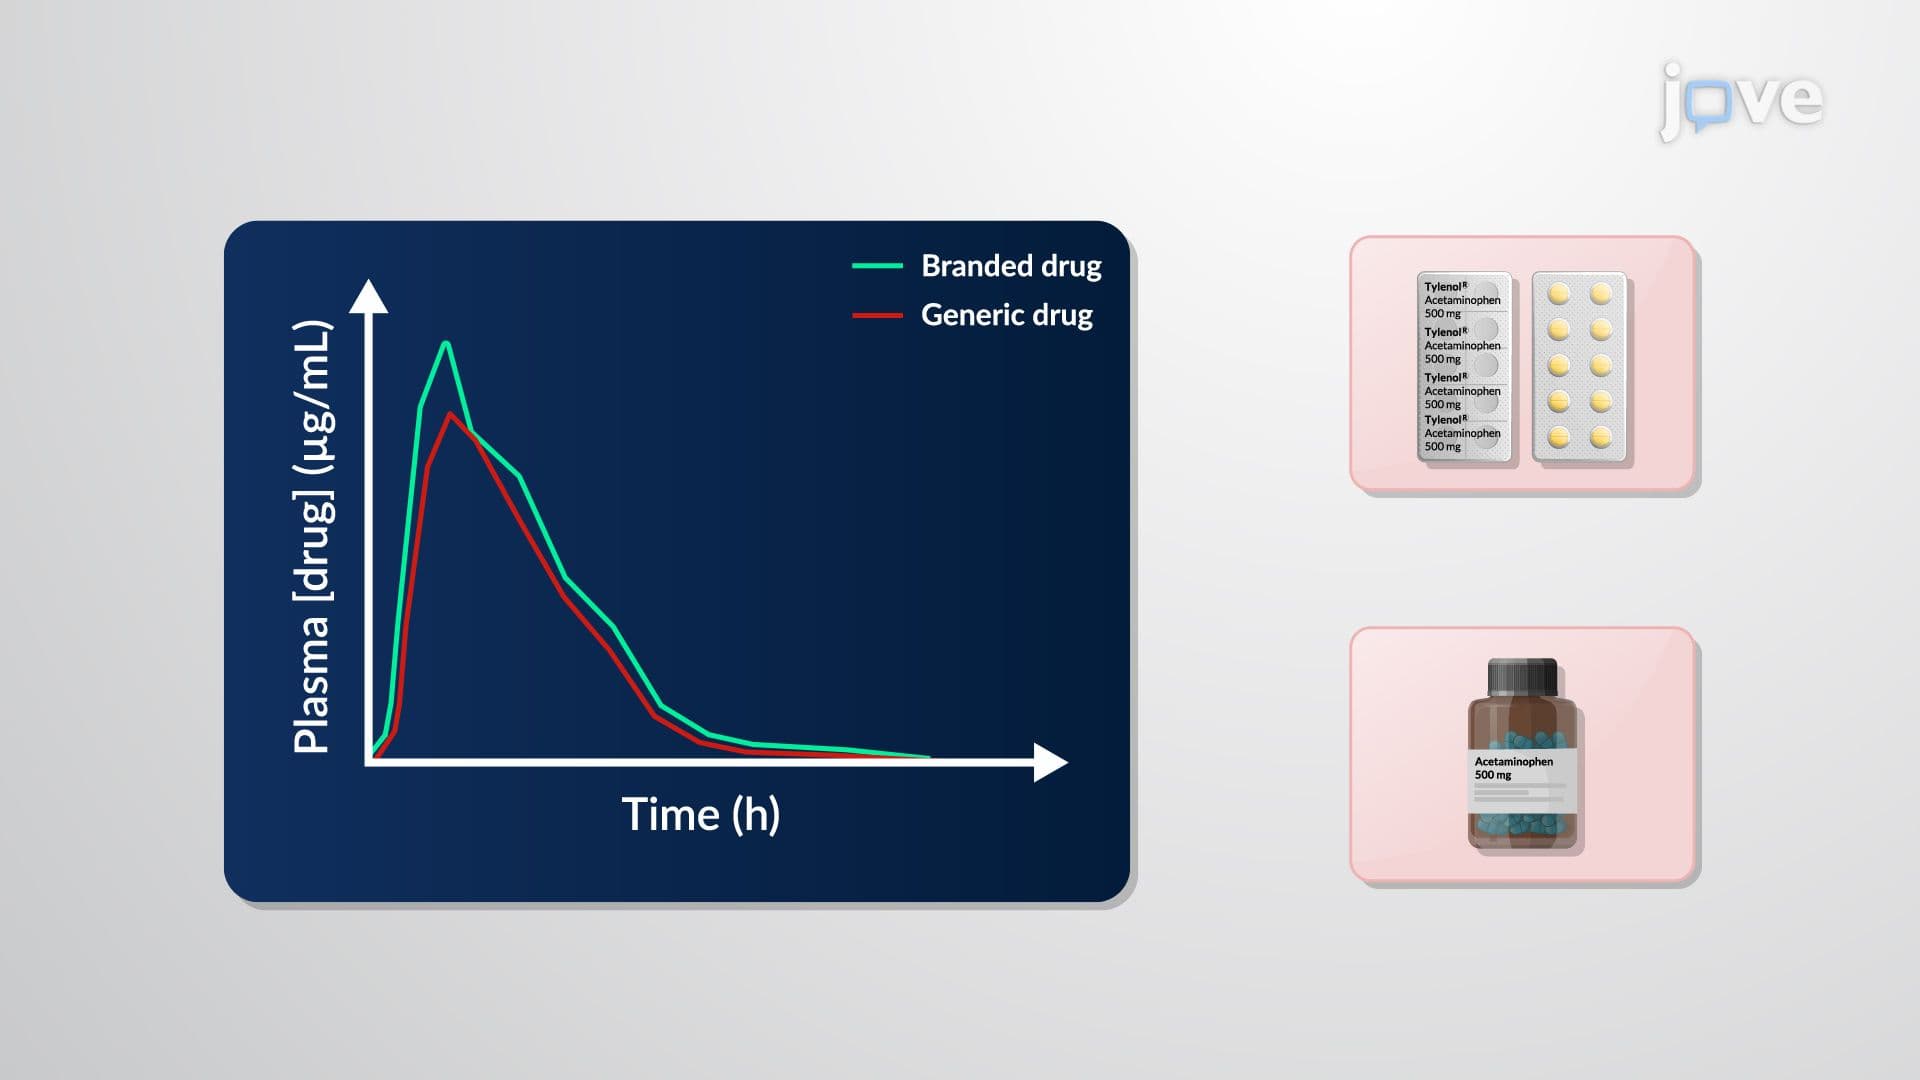
Bioequivalence Data: Statistical Interpretation
 00:59
Uncertainty: Overview
 01:19
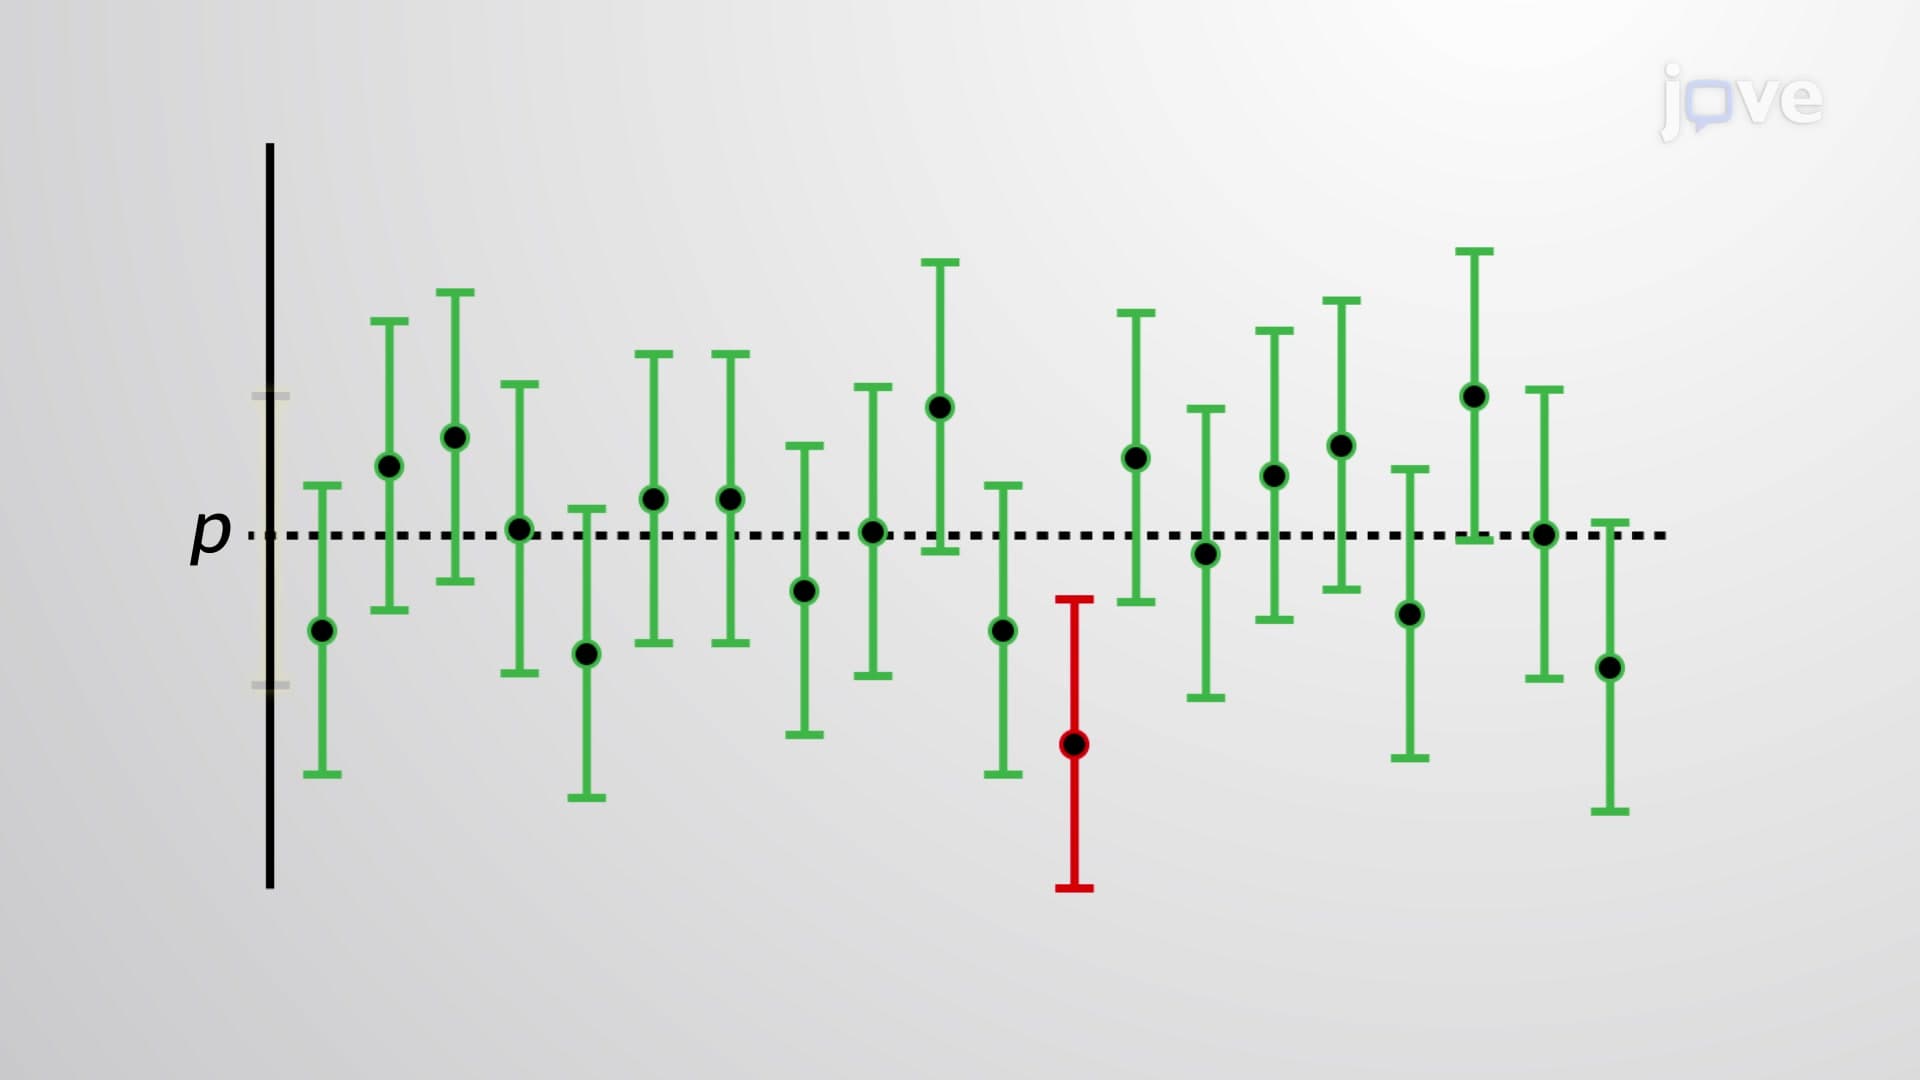
Interpretation of Confidence Intervals
Confidence intervals have confidence coefficients that are crucial for their interpretation. The most common confidence coefficients are 0.90, 0.95, and 0.99, which can be written as percentages–90%, 95%, and 99%, respectively.
Suppose a person calculates a confidence interval with a confidence coefficient of 0.95. In that case, they can...
 01:28
Accuracy, limits, and approximation
Accuracy is defined as the closeness of the measured value to the true or actual value. In engineering mechanics, repeated measurements are taken during theoretical or experimental analyses to ensure that the result is precise and accurate.
The accuracy of any solution is based on the...