Efficient Low-Rank Semidefinite Programming With Robust Loss Functions

Abstract:
In real-world applications, it is important for machine learning algorithms to be robust against data outliers or corruptions. In this paper, we focus on improving the robustness of a large class of learning algorithms that are formulated as low-rank semi-definite programming (SDP) problems. Traditional formulations use the square loss, which is notorious for being sensitive to outliers. We propose to replace this with more robust noise models, including the l1-loss and other nonconvex losses. However, the resultant optimization problem becomes difficult as the objective is no longer convex or smooth. To alleviate this problem, we design an efficient algorithm based on majorization-minimization. The crux is on constructing a good optimization surrogate, and we show that this surrogate can be efficiently obtained by the alternating direction method of multipliers (ADMM). By properly monitoring ADMM's convergence, the proposed algorithm is empirically efficient and also theoretically guaranteed to converge to a critical point. Extensive experiments are performed on four machine learning applications using both synthetic and real-world data sets. Results show that the proposed algorithm is not only fast but also has better performance than the state-of-the-arts.

Related Concept Videos
 01:19
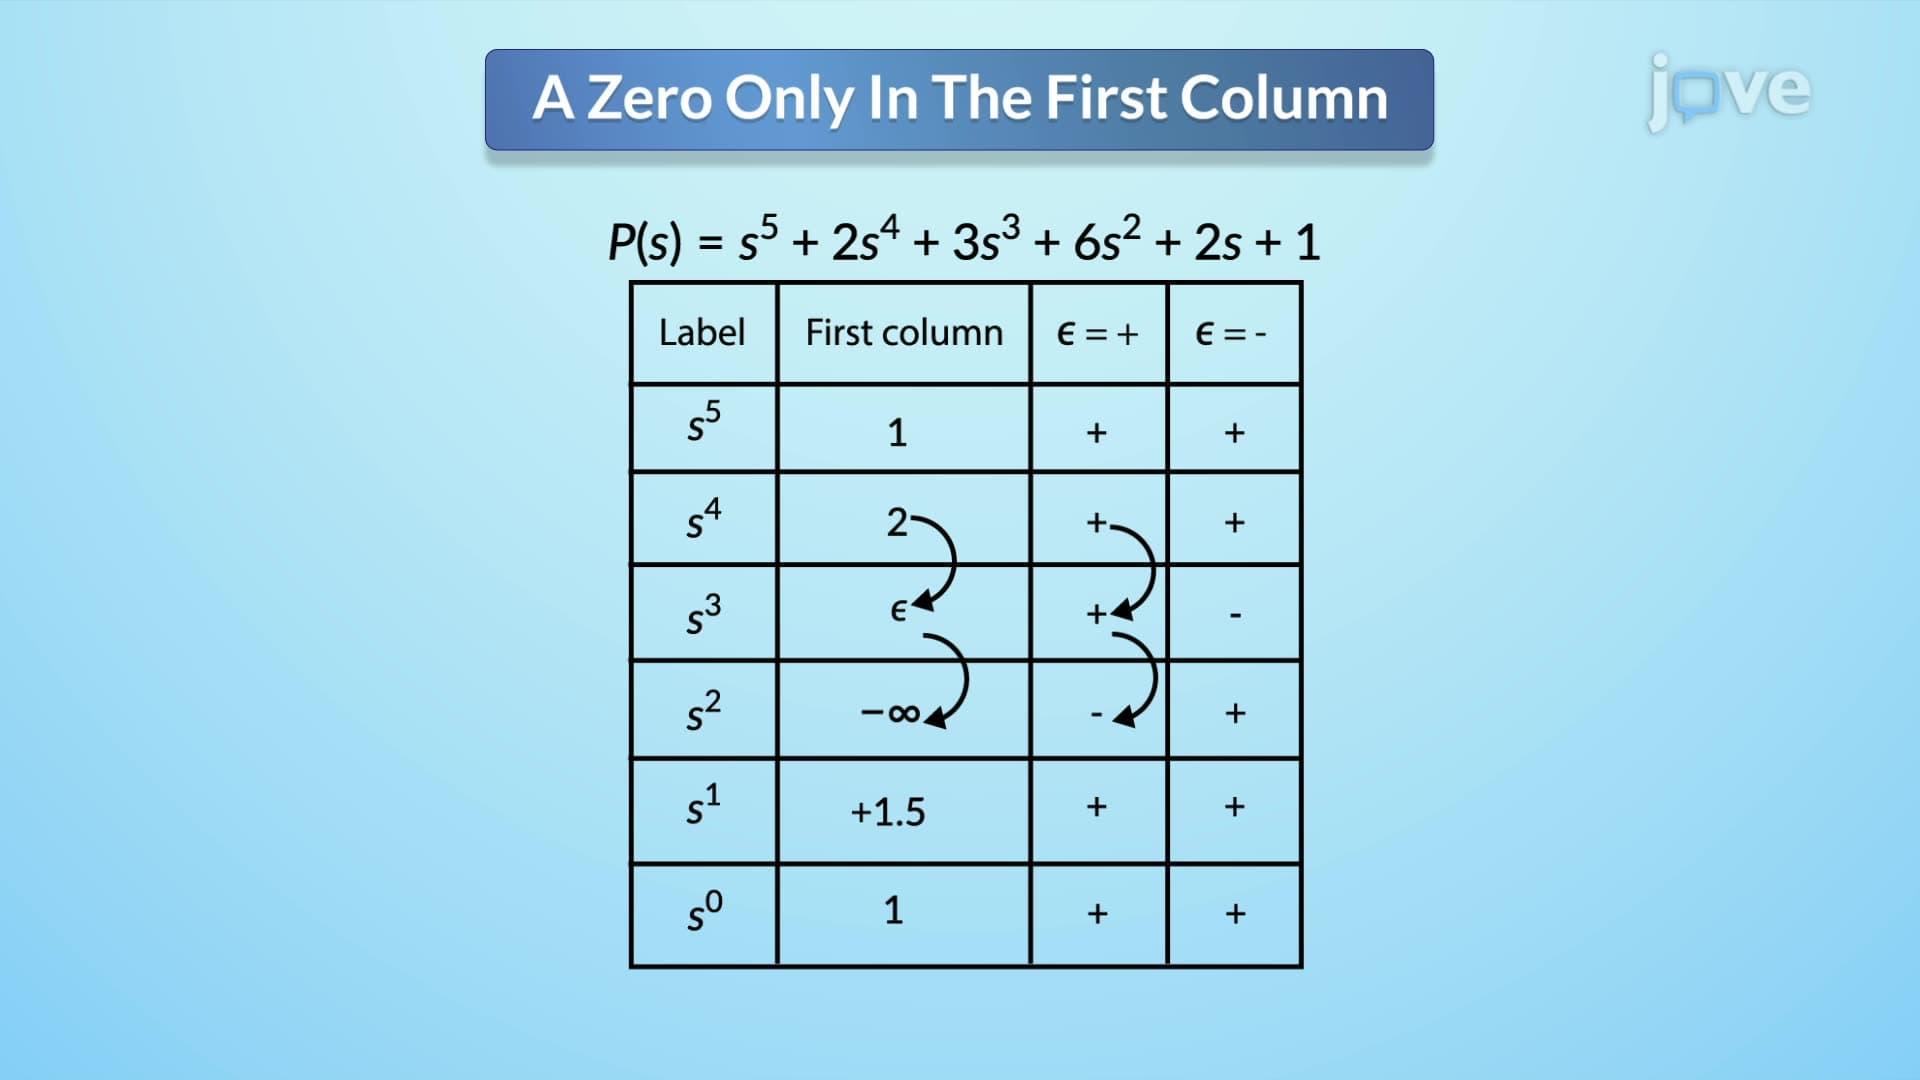
Routh-Hurwitz Criterion II
The first scenario occurs when a singular zero appears in the first column of the Routh table. This situation creates a division by zero issues. To resolve this, a small positive or negative number, denoted as epsilon (∈), is substituted for the zero. The stability analysis proceeds by assuming a sign for ∈. If ∈ is positive, any sign change in the first...
 01:15
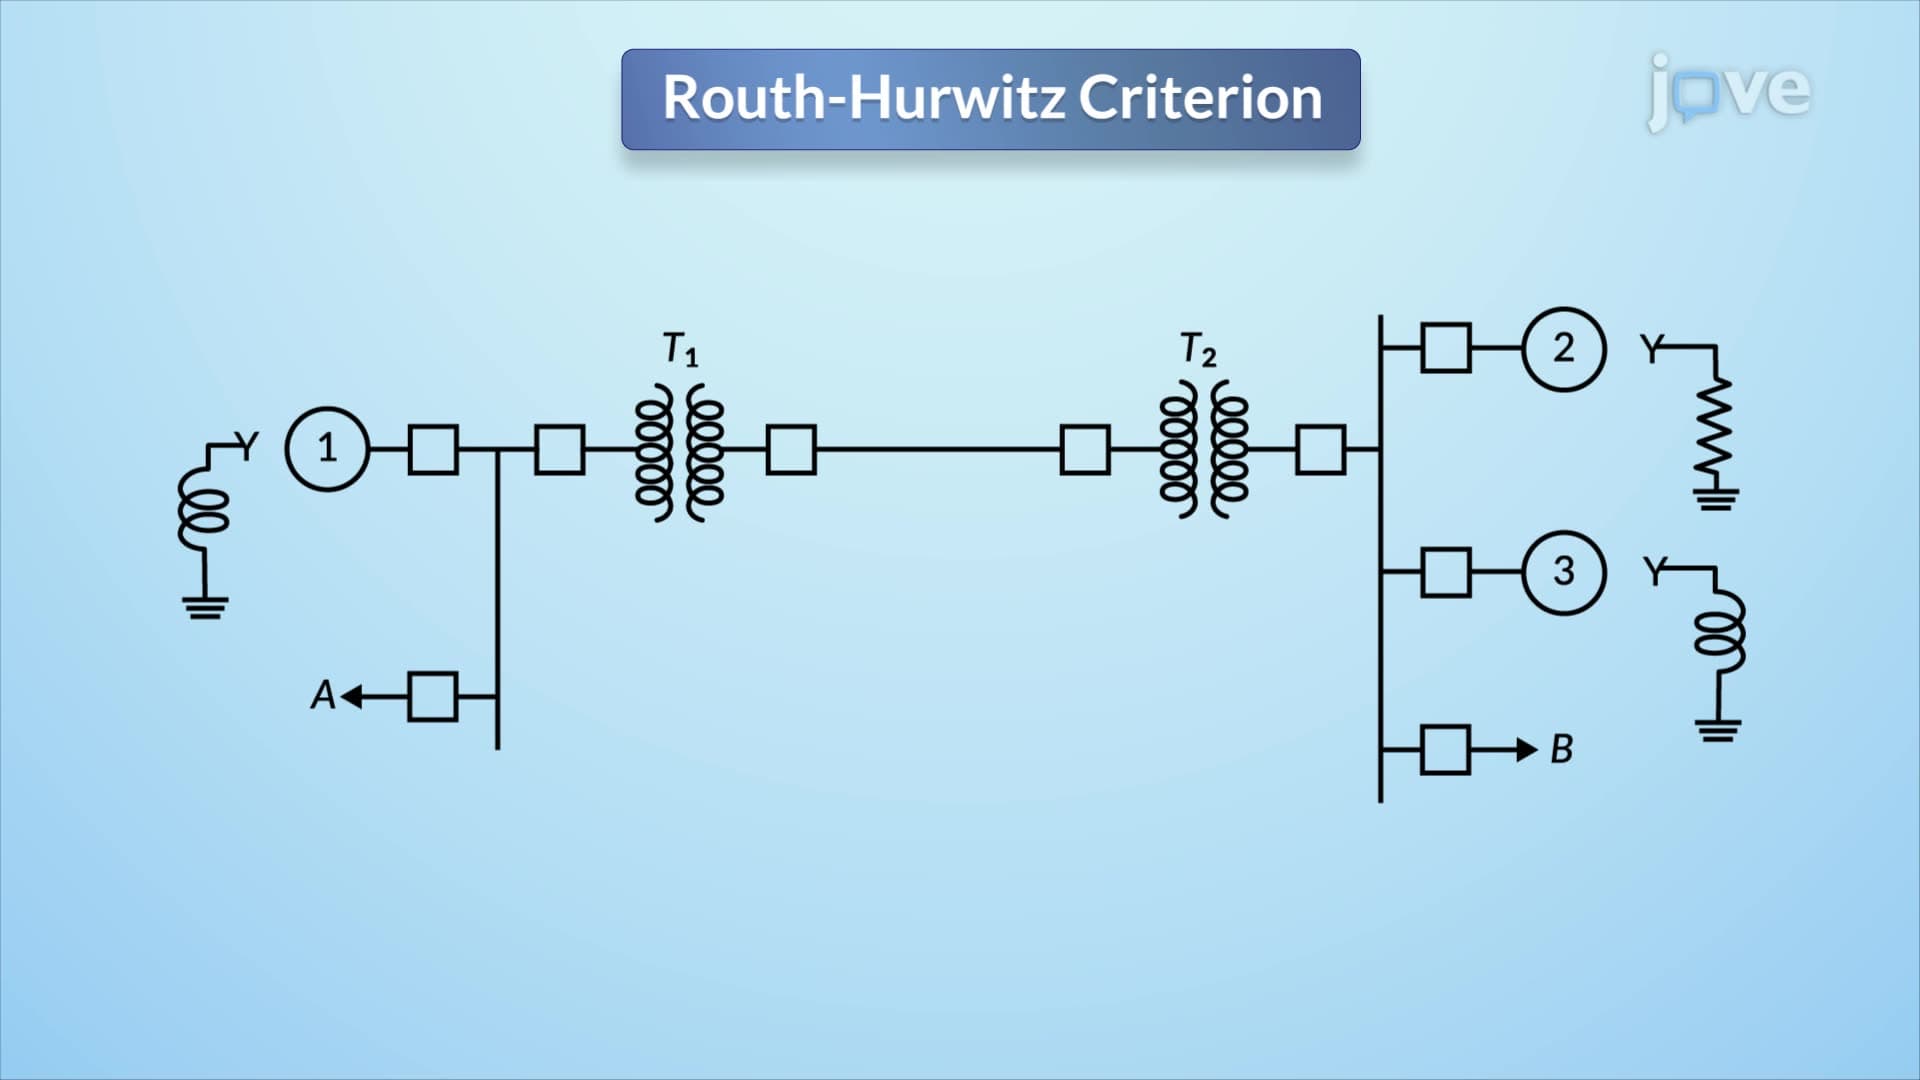
Routh-Hurwitz Criterion I
To apply the Routh-Hurwitz criterion, a Routh table is constructed. The table's rows are labeled with powers of the complex frequency variable s, starting from the...
 01:18
Reducing Line Loss
With a step-up transformer at the source, the voltage is increased, thereby reducing the current in the transmission lines since power loss in...
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:29
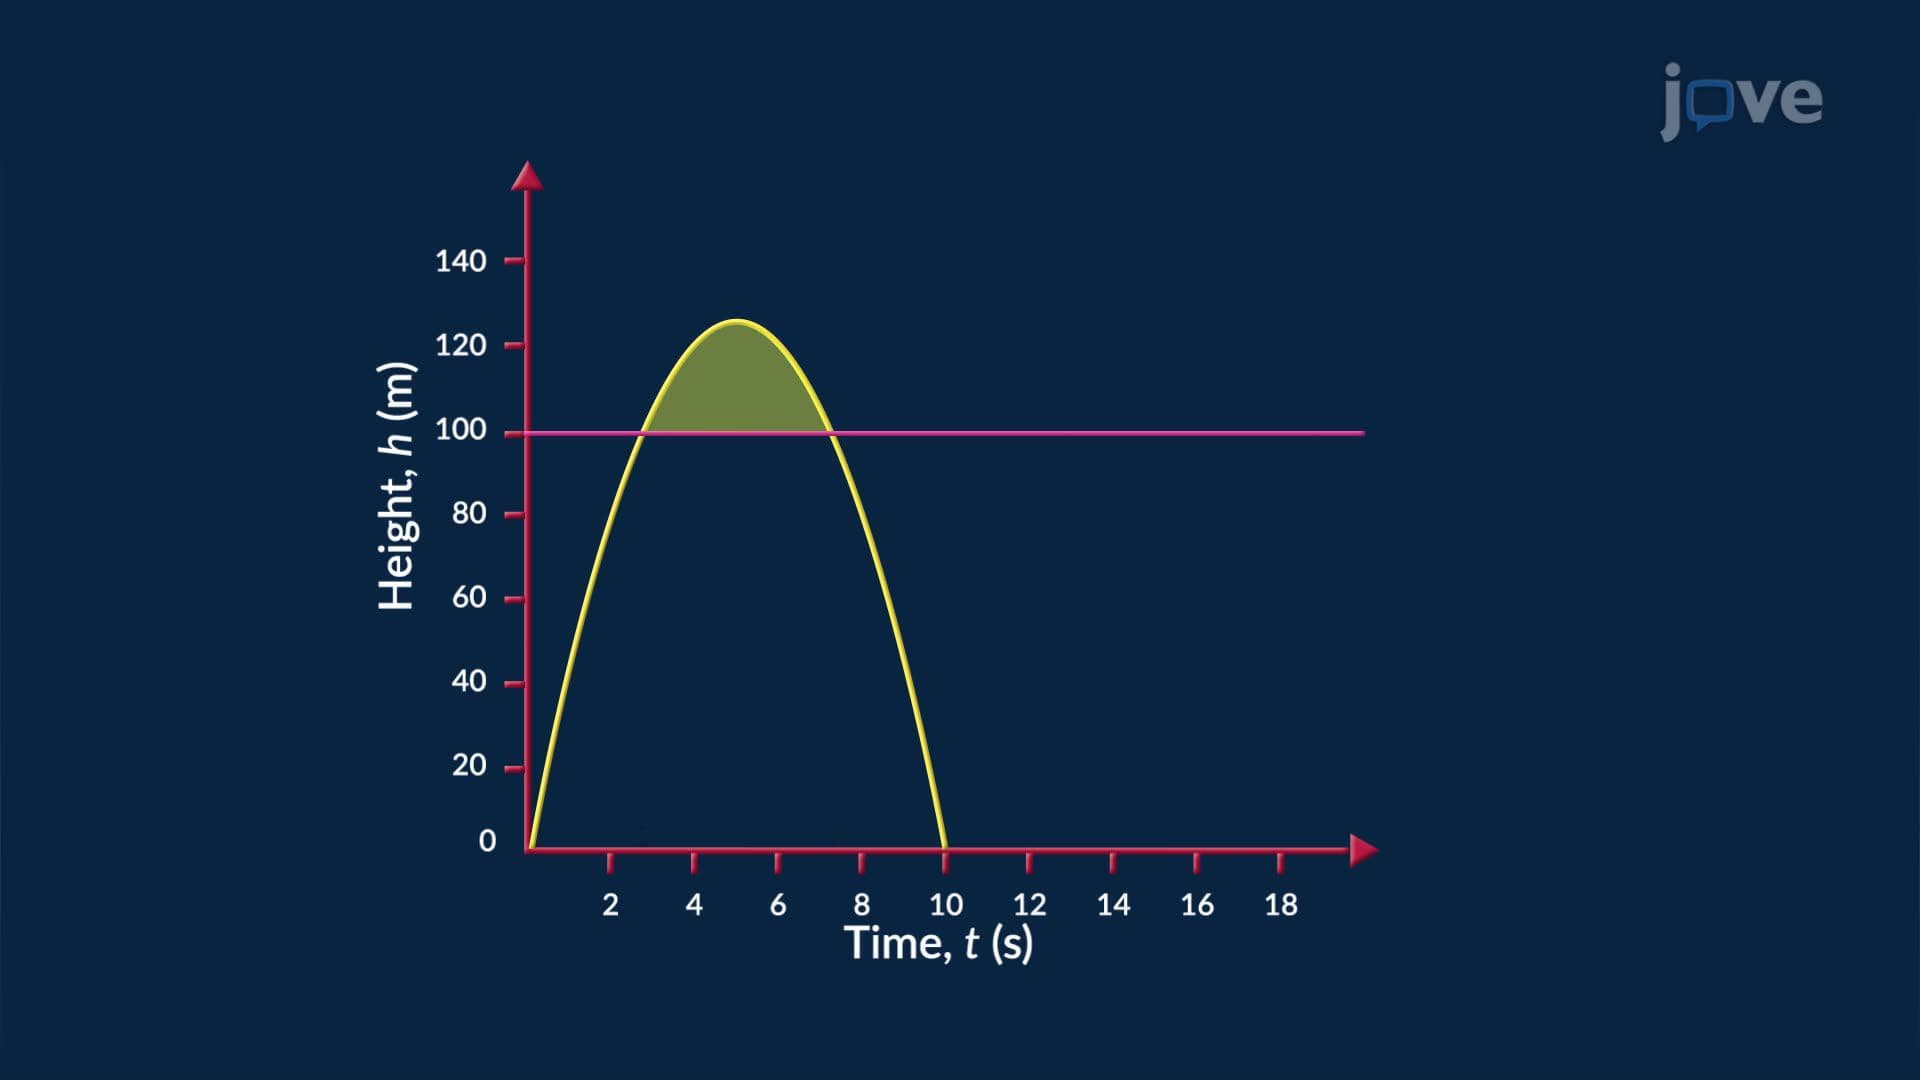
Application of Nonlinear Inequalities
 01:30
Gaussian Elimination: Problem Solving