Related Experiment Video
Updated: Nov 1, 2025
Profiling Maternal Behavior Responses During Whole-Brain Imaging
Published on: January 24, 2025
Graph Convolutional Module for Temporal Action Localization in Videos

Abstract:
Temporal action localization, which requires a machine to recognize the location as well as the category of action instances in videos, has long been researched in computer vision. The main challenge of temporal action localization lies in that videos are usually long and untrimmed with diverse action contents involved. Existing state-of-the-art action localization methods divide each video into multiple action units (i.e., proposals in two-stage methods and segments in one-stage methods) and then perform action recognition/regression on each of them individually, without explicitly exploiting their relations during learning. In this paper, we claim that the relations between action units play an important role in action localization, and a more powerful action detector should not only capture the local content of each action unit but also allow a wider field of view on the context related to it. To this end, we propose a general graph convolutional module (GCM) that can be easily plugged into existing action localization methods, including two-stage and one-stage paradigms. To be specific, we first construct a graph, where each action unit is represented as a node and their relations between two action units as an edge. Here, we use two types of relations, one for capturing the temporal connections between different action units, and the other one for characterizing their semantic relationship. Particularly for the temporal connections in two-stage methods, we further explore two different kinds of edges, one connecting the overlapping action units and the other one connecting surrounding but disjointed units. Upon the graph we built, we then apply graph convolutional networks (GCNs) to model the relations among different action units, which is able to learn more informative representations to enhance action localization. Experimental results show that our GCM consistently improves the performance of existing action localization methods, including two-stage methods (e.g., CBR [15] and R-C3D [47]) and one-stage methods (e.g., D-SSAD [22]), verifying the generality and effectiveness of our GCM. Moreover, with the aid of GCM, our approach significantly outperforms the state-of-the-art on THUMOS14 (50.9 percent versus 42.8 percent). Augmentation experiments on ActivityNet also verify the efficacy of modeling the relationships between action units. The source code and the pre-trained models are available at https://github.com/Alvin-Zeng/GCM.
Related Concept Videos
 01:23
Propagation of Action Potentials
Neurons (nerve cells) have a resting membrane potential, with a slightly negative charge inside compared to outside. This is maintained by ion channels, such as sodium (Na+) and potassium (K+) channels, which control the flow of ions. When a stimulus, like a touch or a signal from another neuron, triggers the neuron, sodium channels open, allowing sodium ions to...
 01:25
Relative Motion Analysis using Rotating Axes
However, to express the relative position of point B relative to point A, an additional frame of reference, denoted as x'y', is necessary. This additional frame not only translates but also rotates relative to the fixed frame, making it...
 01:24
Convolution: Math, Graphics, and Discrete Signals
To simplify the convolution integral, it is assumed that both the input signal and impulse response are zero for negative time values. The graphical convolution process...
 01:24
Absolute Motion Analysis- General Plane Motion
As the drone's propellers rotate, an upward force is generated that counteracts the force of gravity, enabling the drone to lift off from the ground. This initial movement of the drone is along a straight path, representing a form of translational motion. In this phase, every point on the...
 01:20
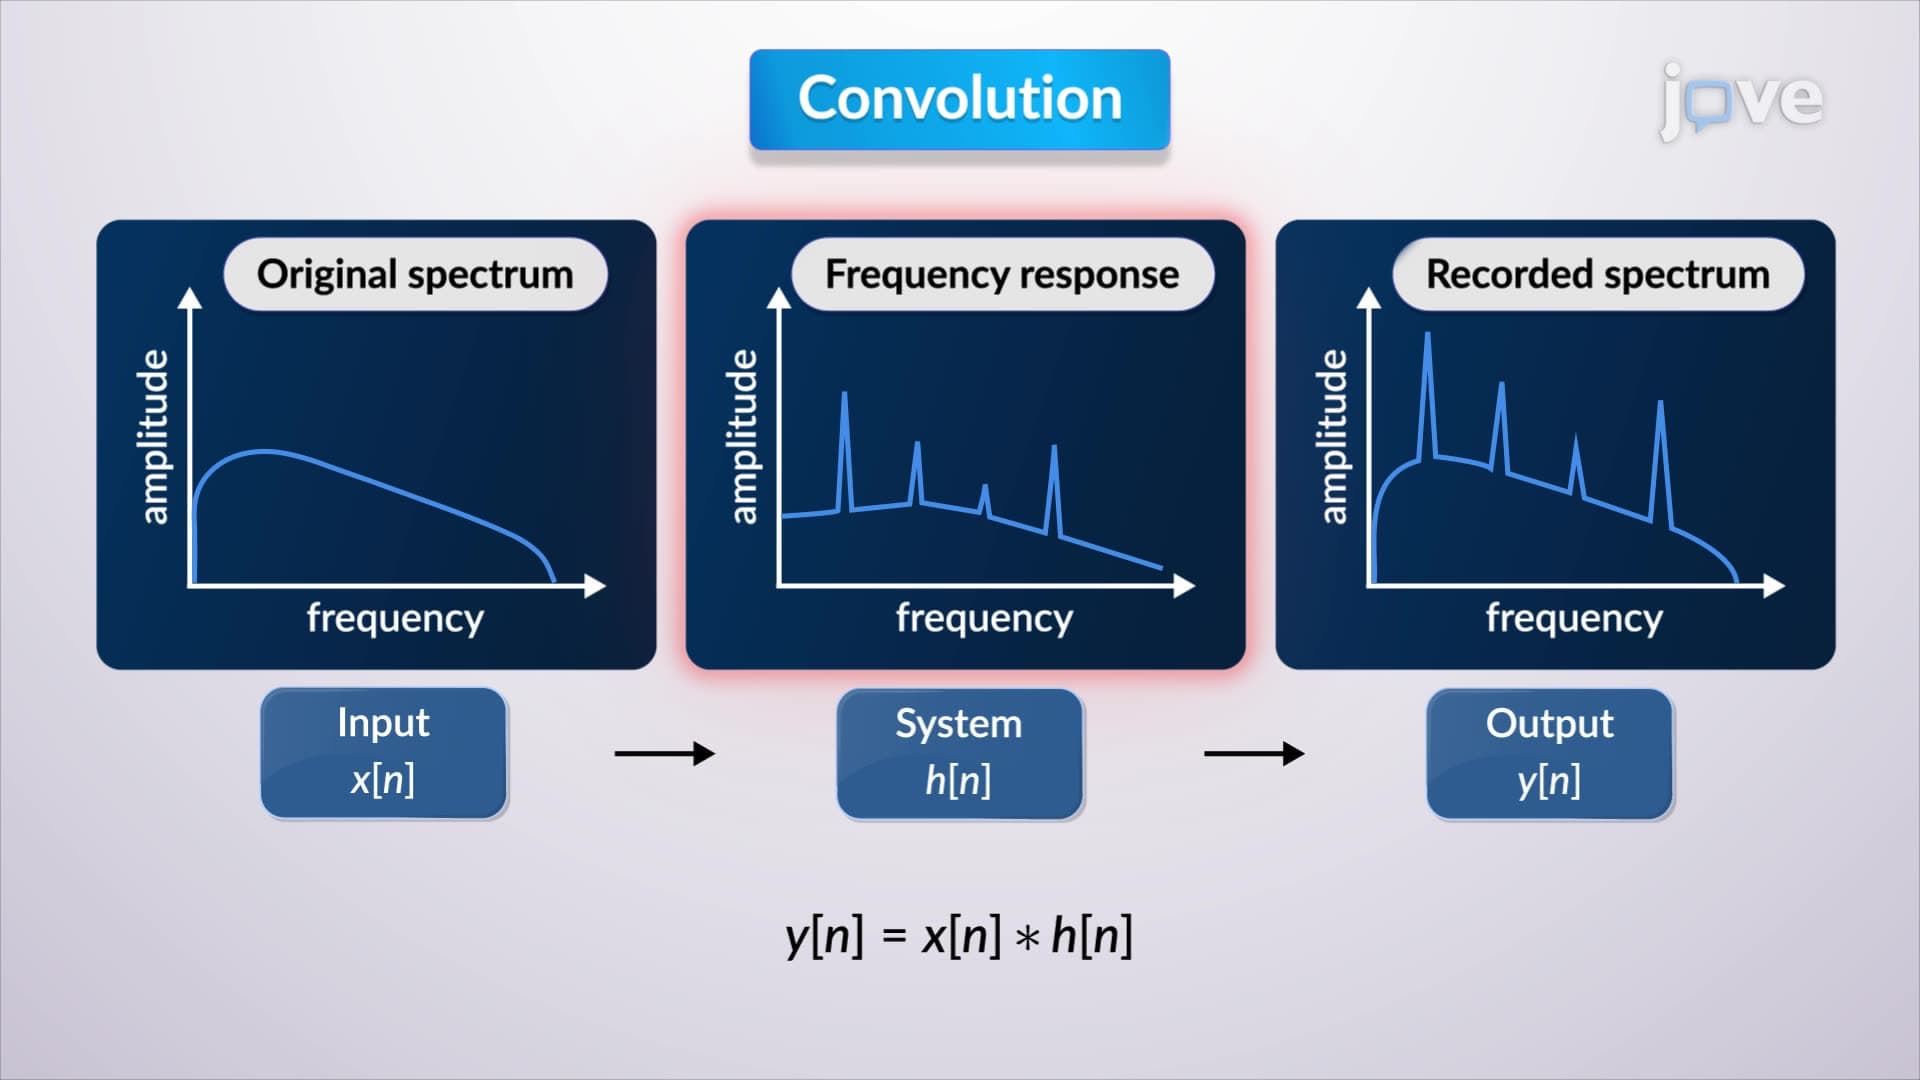
Deconvolution
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
 01:17
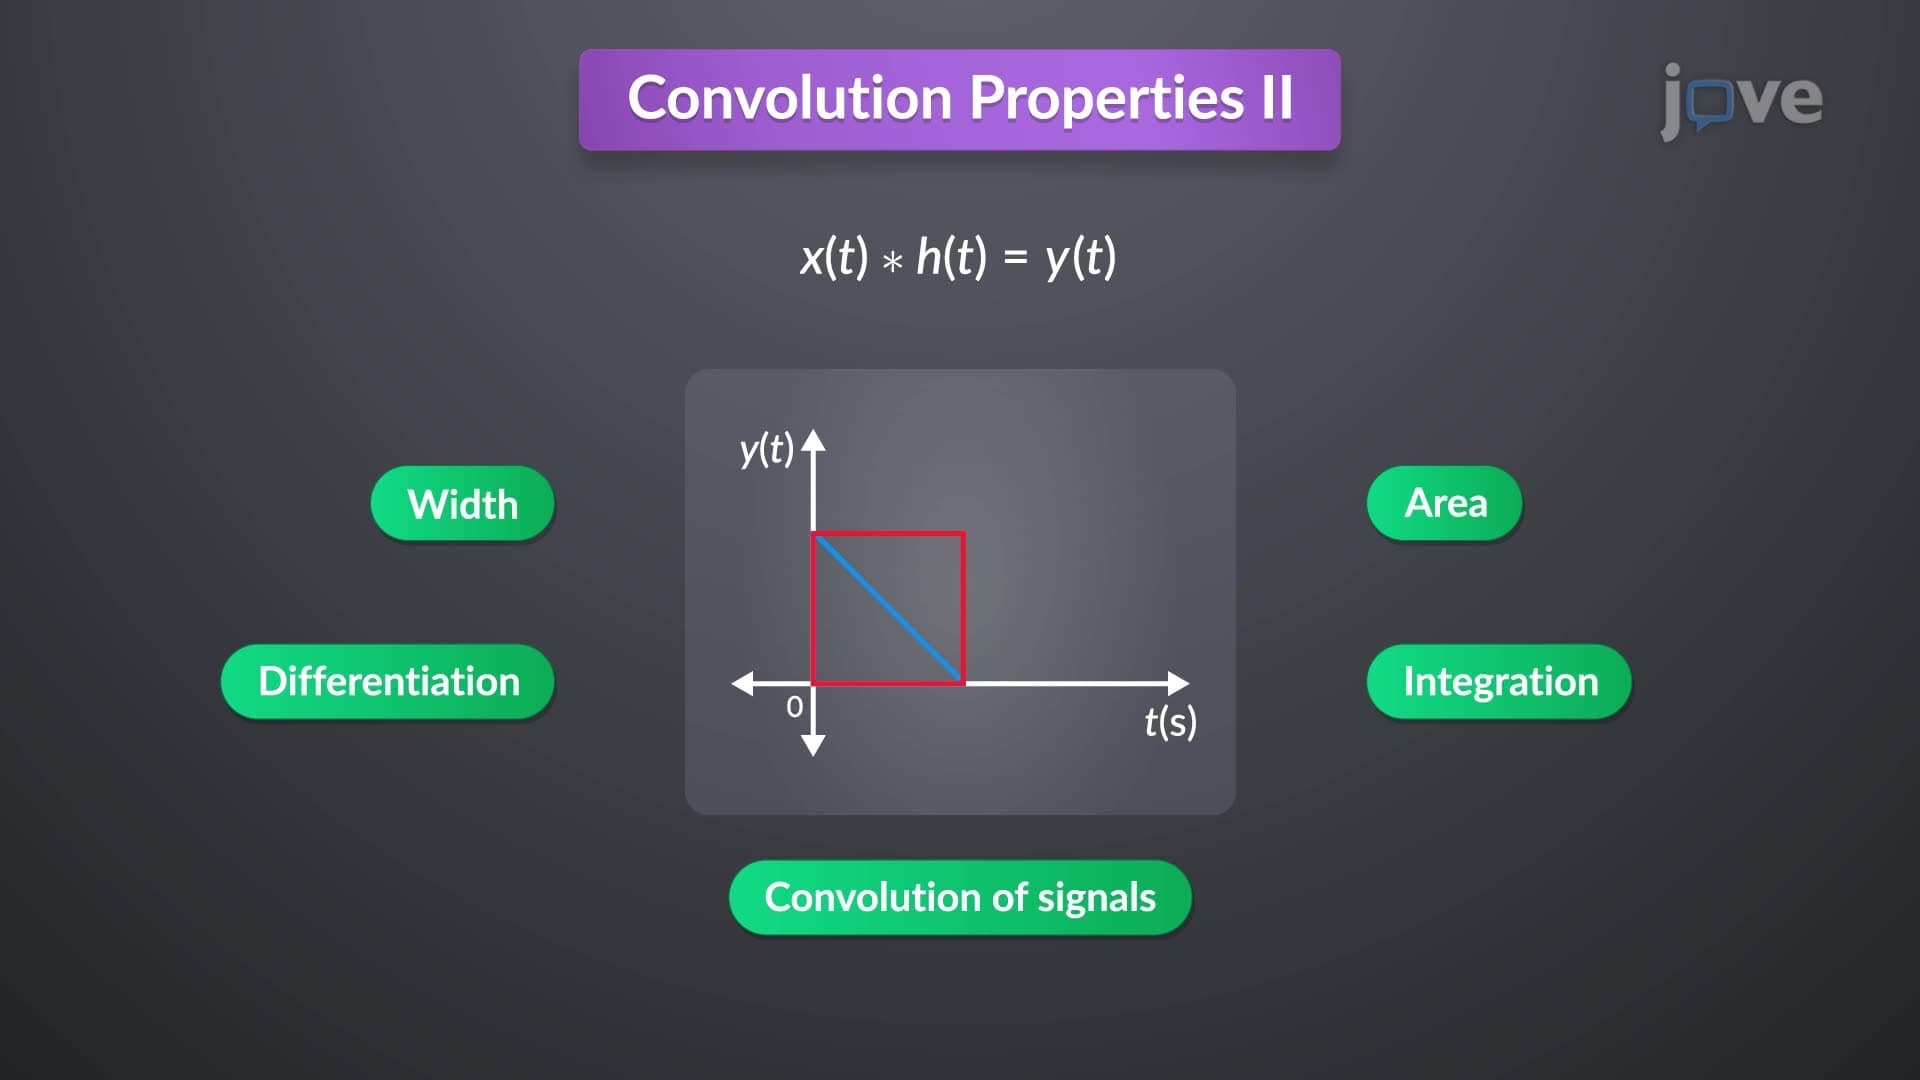
Convolution Properties II
The width property indicates that if the durations of input signals are T1 and T2, then the width of the output response equals the sum of both durations, irrespective of the shapes of the two functions. For instance, convolving two rectangular pulses with durations of 2 seconds and 1 second results in a function with a width of 3 seconds.
The area property asserts that the area under the...