Simple Convolutional-Based Models: Are They Learning the Task or the Data?
Related Experiment Video
Updated: Oct 15, 2025

Author Spotlight: Enhancement of Salient Object Detection for Smart Grid Applications
Published on: December 15, 2023
Luis Sa-Couto1, Andreas Wichert2
1Department of Computer Science and Engineering, INESC-ID and Instituto Superior, Técnico University of Lisbon, 2744-016 Porto Salvo, Portugal luis.sa.couto@tecnico.ulisboa.pt.

Abstract:
Convolutional neural networks (CNNs) evolved from Fukushima's neocognitron model, which is based on the ideas of Hubel and Wiesel about the early stages of the visual cortex. Unlike other branches of neocognitron-based models, the typical CNN is based on end-to-end supervised learning by backpropagation and removes the focus from built-in invariance mechanisms, using pooling not as a way to tolerate small shifts but as a regularization tool that decreases model complexity. These properties of end-to-end supervision and flexibility of structure allow the typical CNN to become highly tuned to the training data, leading to extremely high accuracies on typical visual pattern recognition data sets. However, in this work, we hypothesize that there is a flip side to this capability, a hidden overfitting. More concretely, a supervised, backpropagation based CNN will outperform a neocognitron/map transformation cascade (MTC) when trained and tested inside the same data set. Yet if we take both models trained and test them on the same task but on another data set (without retraining), the overfitting appears. Other neocognitron descendants like the What-Where model go in a different direction. In these models, learning remains unsupervised, but more structure is added to capture invariance to typical changes. Knowing that, we further hypothesize that if we repeat the same experiments with this model, the lack of supervision may make it worse than the typical CNN inside the same data set, but the added structure will make it generalize even better to another one. To put our hypothesis to the test, we choose the simple task of handwritten digit classification and take two well-known data sets of it: MNIST and ETL-1. To try to make the two data sets as similar as possible, we experiment with several types of preprocessing. However, regardless of the type in question, the results align exactly with expectation.
Related Concept Videos
 01:24
Convolution: Math, Graphics, and Discrete Signals
To simplify the convolution integral, it is assumed that both the input signal and impulse response are zero for negative time values. The graphical convolution process...
 01:18
Introduction to Learning
In contrast to learned behaviors, unlearned behaviors such as crying, sexual...
 01:17
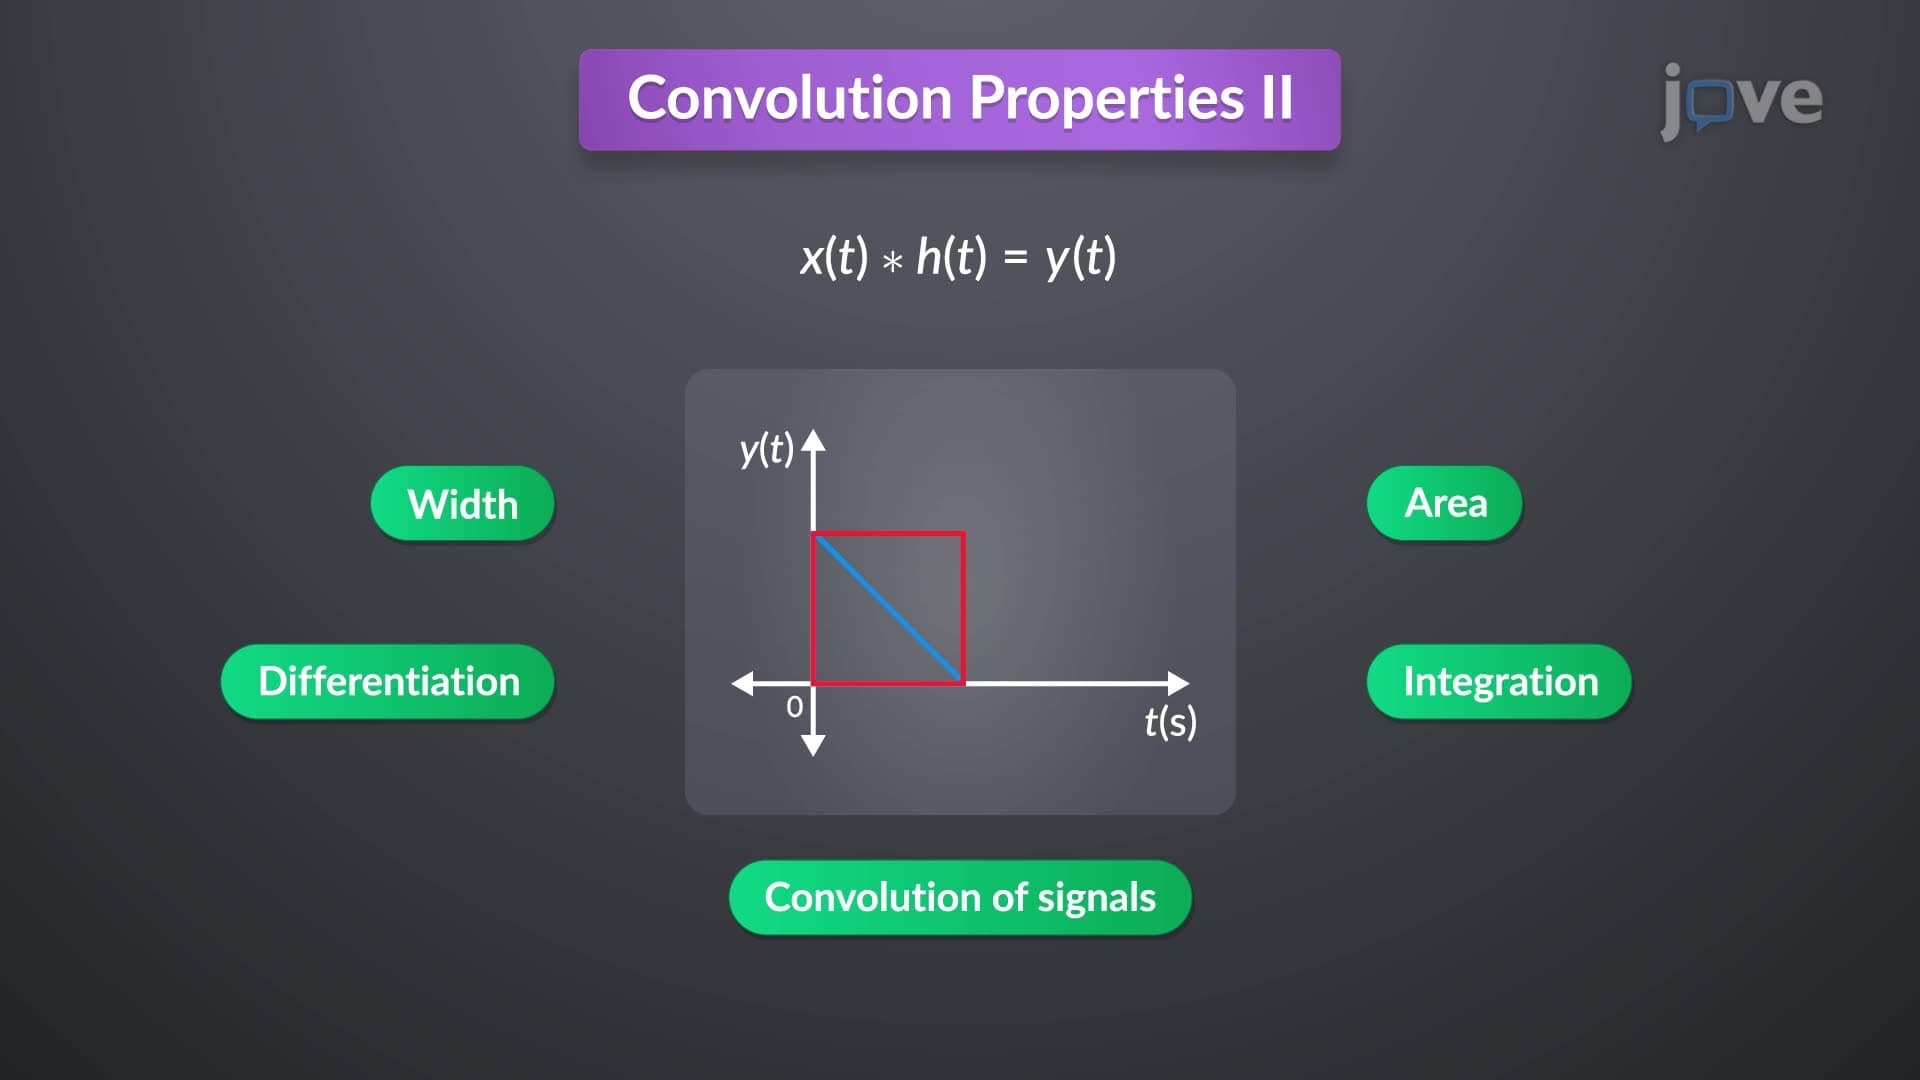
Convolution Properties II
The width property indicates that if the durations of input signals are T1 and T2, then the width of the output response equals the sum of both durations, irrespective of the shapes of the two functions. For instance, convolving two rectangular pulses with durations of 2 seconds and 1 second results in a function with a width of 3 seconds.
The area property asserts that the area under the...
 01:20
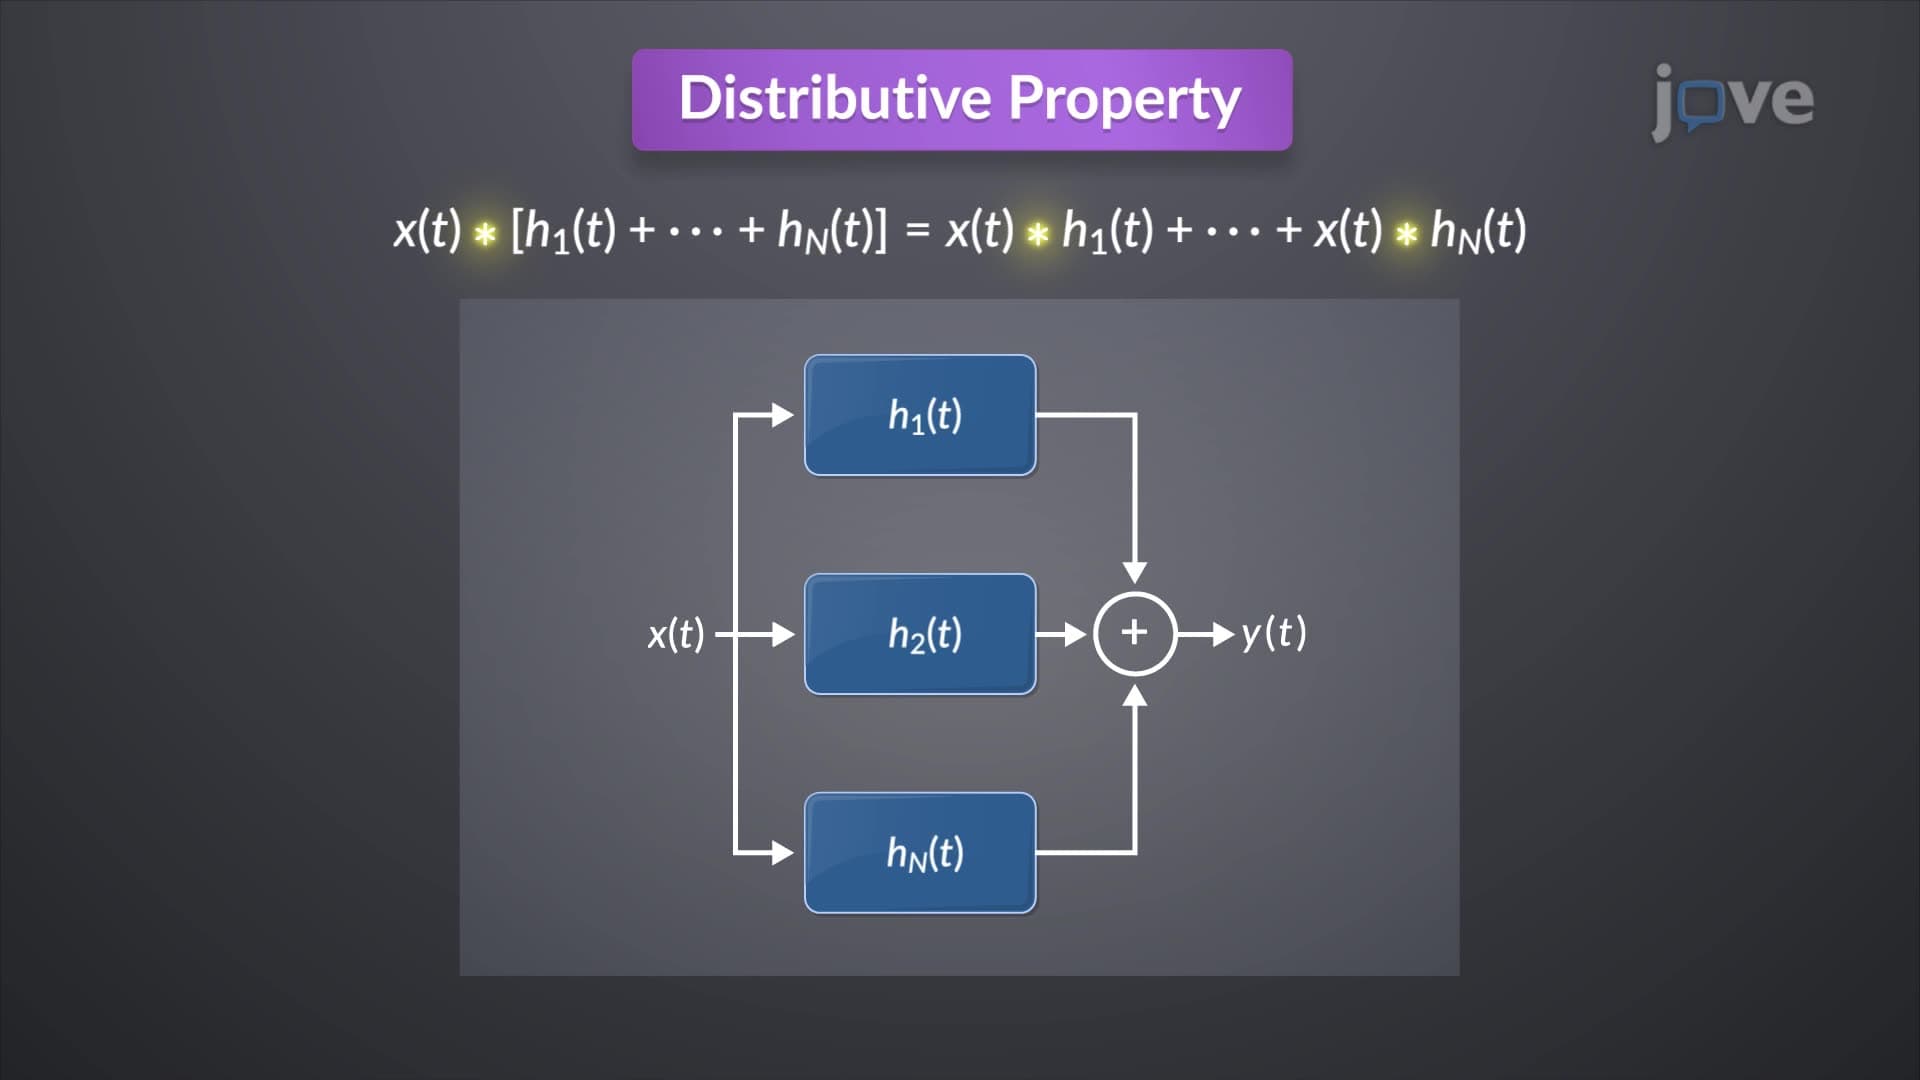
Convolution Properties I
The commutative property reveals that the input and the impulse response of an LTI (Linear Time-Invariant) system can be interchanged without affecting the output:
 01:12
Observational Learning
 01:22
Multi-input and Multi-variable systems
In the absence...