Related Experiment Video
Updated: Oct 14, 2025

Development of an Individual-Tree Basal Area Increment Model using a Linear Mixed-Effects Approach
Published on: July 3, 2020
A Systematic Study into the Factors that Affect the Predictive Accuracy of Multilevel VAR(1) Models
Ginette Lafit1, Kristof Meers2, Eva Ceulemans2
1Research Group of Quantitative Psychology and Individual Differences, KU Leuven - University of Leuven, Leuven, Belgium. ginette.lafit@kuleuven.be.

Abstract:
The use of multilevel VAR(1) models to unravel within-individual process dynamics is gaining momentum in psychological research. These models accommodate the structure of intensive longitudinal datasets in which repeated measurements are nested within individuals. They estimate within-individual auto- and cross-regressive relationships while incorporating and using information about the distributions of these effects across individuals. An important quality feature of the obtained estimates pertains to how well they generalize to unseen data. Bulteel and colleagues (Psychol Methods 23(4):740-756, 2018a) showed that this feature can be assessed through a cross-validation approach, yielding a predictive accuracy measure. In this article, we follow up on their results, by performing three simulation studies that allow to systematically study five factors that likely affect the predictive accuracy of multilevel VAR(1) models: (i) the number of measurement occasions per person, (ii) the number of persons, (iii) the number of variables, (iv) the contemporaneous collinearity between the variables, and (v) the distributional shape of the individual differences in the VAR(1) parameters (i.e., normal versus multimodal distributions). Simulation results show that pooling information across individuals and using multilevel techniques prevent overfitting. Also, we show that when variables are expected to show strong contemporaneous correlations, performing multilevel VAR(1) in a reduced variable space can be useful. Furthermore, results reveal that multilevel VAR(1) models with random effects have a better predictive performance than person-specific VAR(1) models when the sample includes groups of individuals that share similar dynamics.
More Related Videos
 06:48
Lexical Decision Task for Studying Written Word Recognition in Adults with and without Dementia or Mild Cognitive Impairment
Published on: June 25, 2019
 06:52
Using Cholesky Decomposition to Explore Individual Differences in Longitudinal Relations between Reading Skills
Published on: September 17, 2019
Related Concept Videos
 01:25
Multiple Regression
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
 01:19
Variation
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
 01:11
Regression Analysis
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
 01:14
Multicompartment Models: Overview
These models offer a more comprehensive representation of drug behavior in the body than one-compartment models. They accommodate the complexity of drug distribution,...
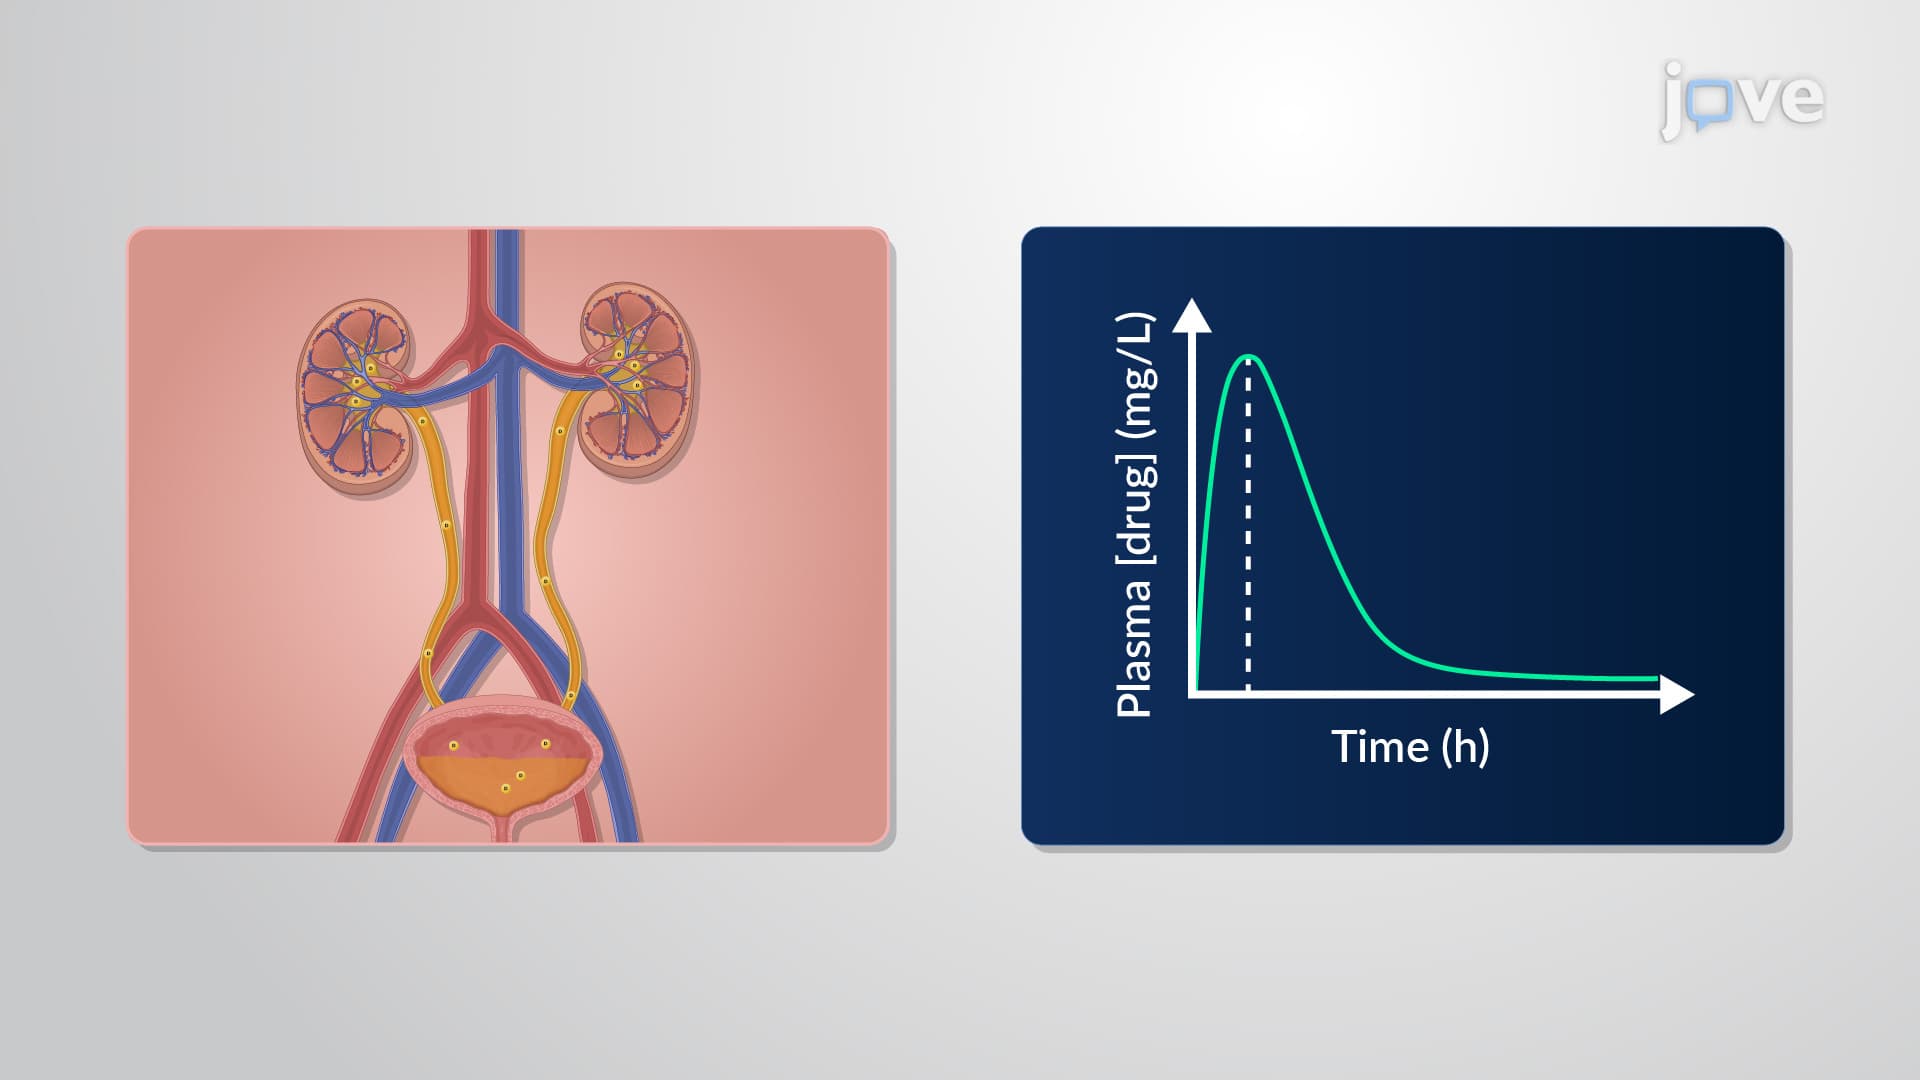 01:13
Parameters Affecting Nonlinear Elimination: Zero-Order Input, First-Order Absorption and Two-Compartment Model
When a drug is administered through a constant intravenous infusion and eliminated via nonlinear pharmacokinetics, it follows zero-order input. For example, oral drugs undergo first-order absorption upon administration and are eliminated through nonlinear pharmacokinetics.
In the case of subcutaneously administered drugs,...
 01:03
Prediction Intervals
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.