Related Experiment Video
Updated: Oct 7, 2025
09:26

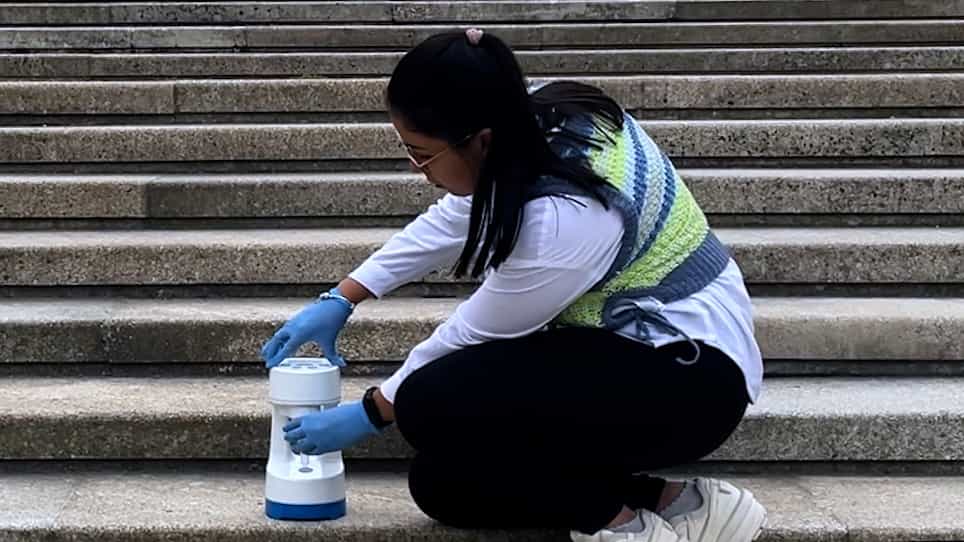
Quantification and Whole Genome Characterization of SARS-CoV-2 RNA in Wastewater and Air Samples
Published on: June 30, 2023
1.3K
A model study on predicting new COVID-19 cases in China based on social and news media
Mengxuan Lin1, Hui Chen2, Yuqi Wang3
1Academy of Military Medical Sciences, Academy of Military Science of Chinese PLA, Beijing, China.
The Journal of Infection
|January 12, 2022

Abstract
No abstract available in PubMed .
Related Concept Videos
 01:18
Steps in Outbreak Investigation
246
In the ever-evolving field of public health, statistical analysis serves as a cornerstone for understanding and managing disease outbreaks. By leveraging various statistical tools, health professionals can predict potential outbreaks, analyze ongoing situations, and devise effective responses to mitigate impact. For that to happen, there are a few possible stages of the analysis:
246
 01:05
Single Nucleotide Polymorphisms-SNPs
16.6K
A single nucleotide polymorphism or SNP is a single nucleotide variation at a specific genomic position in a large population. It is the most prevalent type of sequence variation found in the human genome. Point mutations that occur in more than 1% of the population qualify as SNPs. These are present once every 1000 nucleotides on an average in the human genome. Replacement of a purine with another purine (A/G) or a pyrimidine with another pyrimidine (C/T) is known as a transition. In contrast,...
16.6K
 01:25
Statistical Methods for Analyzing Epidemiological Data
592
Epidemiological data primarily involves information on specific populations' occurrence, distribution, and determinants of health and diseases. This data is crucial for understanding disease patterns and impacts, aiding public health decision-making and disease prevention strategies. The analysis of epidemiological data employs various statistical methods to interpret health-related data effectively. Here are some commonly used methods:
592
 01:21
Causality in Epidemiology
1.0K
Causality or causation is a fundamental concept in epidemiology, vital for understanding the relationships between various factors and health outcomes. Despite its importance, there's no single, universally accepted definition of causality within the discipline. Drawing from a systematic review, causality in epidemiology encompasses several definitions, including production, necessary and sufficient, sufficient-component, counterfactual, and probabilistic models. Each has its strengths and...
1.0K
 01:29
Bias in Epidemiological Studies
765
Biases can arise at various stages of research, from study design and data collection to analysis and interpretation. Recognizing and addressing these biases is essential to ensure the validity and reliability of epidemiological findings.Broadly speaking, biases in epidemiology fall into three main categories: selection bias, information bias, and confounding. A more detailed description of possible biases is:
765
 01:11
Residuals and Least-Squares Property
8.0K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
8.0K