Related Experiment Video
Updated: Oct 4, 2025
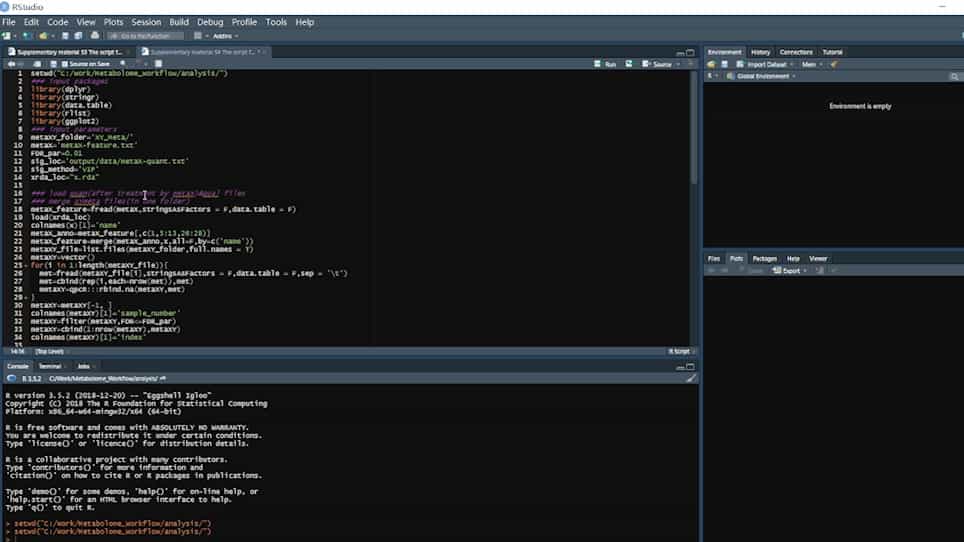
An Integrated Workflow of Identification and Quantification on FDR Control-Based Untargeted Metabolome
Published on: September 20, 2022
Estimation of the proportion of true null hypotheses under sparse dependence: Adaptive FDR controlling in microarray
Aniket Biswas1, Subrata Chakraborty1, Vishwa Jyoti Baruah2
1Department of Statistics, 28675Dibrugarh University, Dibrugarh, Assam, India.

Abstract:
The proportion of non-differentially expressed genes is an important quantity in microarray data analysis and an appropriate estimate of the same is used to construct adaptive multiple testing procedures. Most of the estimators for the proportion of true null hypotheses based on the thresholding, maximum likelihood and density estimation approaches assume independence among the gene expressions. Usually, sparse dependence structure is natural in modelling associations in microarray gene expression data and hence it is necessary to develop methods for accommodating the sparse dependence well within the framework of existing estimators. We propose a clustering based method to put genes in the same group that are not coexpressed using the estimated high dimensional correlation structure under sparse assumption as dissimilarity matrix. This novel method is applied to three existing estimators for the proportion of true null hypotheses. Extensive simulation study shows that the proposed method improves an existing estimator by making it less conservative and the corresponding adaptive Benjamini-Hochberg algorithm more powerful. The proposed method is applied to a microarray gene expression dataset of colorectal cancer patients and the results show gain in terms of number of differentially expressed genes. The R code is available at https://github.com/aniketstat/Proportiontion-of-true-null-under-sparse-dependence-2021.
More Related Videos
Related Concept Videos
 01:14
Identifying Statistically Significant Differences: The F-Test
 01:13
Accuracy and Errors in Hypothesis Testing
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5%...
 01:19
Expected Frequencies in Goodness-of-Fit Tests
 01:16
Statistical Hypothesis Testing
Statistical significance measures the probability that an observed result occurred by chance. If this probability, known as...
 02:46
Chi-square Analysis
The chi-square test was developed by Pearson in 1990.
The first step of performing a Chi-square analysis is to establish a null hypothesis, which assumes that there is no real...
 01:08
Fisher's Exact Test