Related Experiment Video
Updated: Sep 29, 2025


Combining Eye-tracking Data with an Analysis of Video Content from Free-viewing a Video of a Walk in an Urban Park Environment
Published on: May 7, 2019
Photo2Video: Semantic-Aware Deep Learning-Based Video Generation from Still Content
Paula Viana1,2, Maria Teresa Andrade1,3, Pedro Carvalho1,2
1INESC TEC, 4200-465 Porto, Portugal.

Abstract:
Applying machine learning (ML), and especially deep learning, to understand visual content is becoming common practice in many application areas. However, little attention has been given to its use within the multimedia creative domain. It is true that ML is already popular for content creation, but the progress achieved so far addresses essentially textual content or the identification and selection of specific types of content. A wealth of possibilities are yet to be explored by bringing the use of ML into the multimedia creative process, allowing the knowledge inferred by the former to influence automatically how new multimedia content is created. The work presented in this article provides contributions in three distinct ways towards this goal: firstly, it proposes a methodology to re-train popular neural network models in identifying new thematic concepts in static visual content and attaching meaningful annotations to the detected regions of interest; secondly, it presents varied visual digital effects and corresponding tools that can be automatically called upon to apply such effects in a previously analyzed photo; thirdly, it defines a complete automated creative workflow, from the acquisition of a photograph and corresponding contextual data, through the ML region-based annotation, to the automatic application of digital effects and generation of a semantically aware multimedia story driven by the previously derived situational and visual contextual data. Additionally, it presents a variant of this automated workflow by offering to the user the possibility of manipulating the automatic annotations in an assisted manner. The final aim is to transform a static digital photo into a short video clip, taking into account the information acquired. The final result strongly contrasts with current standard approaches of creating random movements, by implementing an intelligent content- and context-aware video.
Related Concept Videos
 01:27
State Space Representation
Consider an RLC circuit, a...
 01:16
Non-equilibrium in the Cell
 01:20
Deconvolution
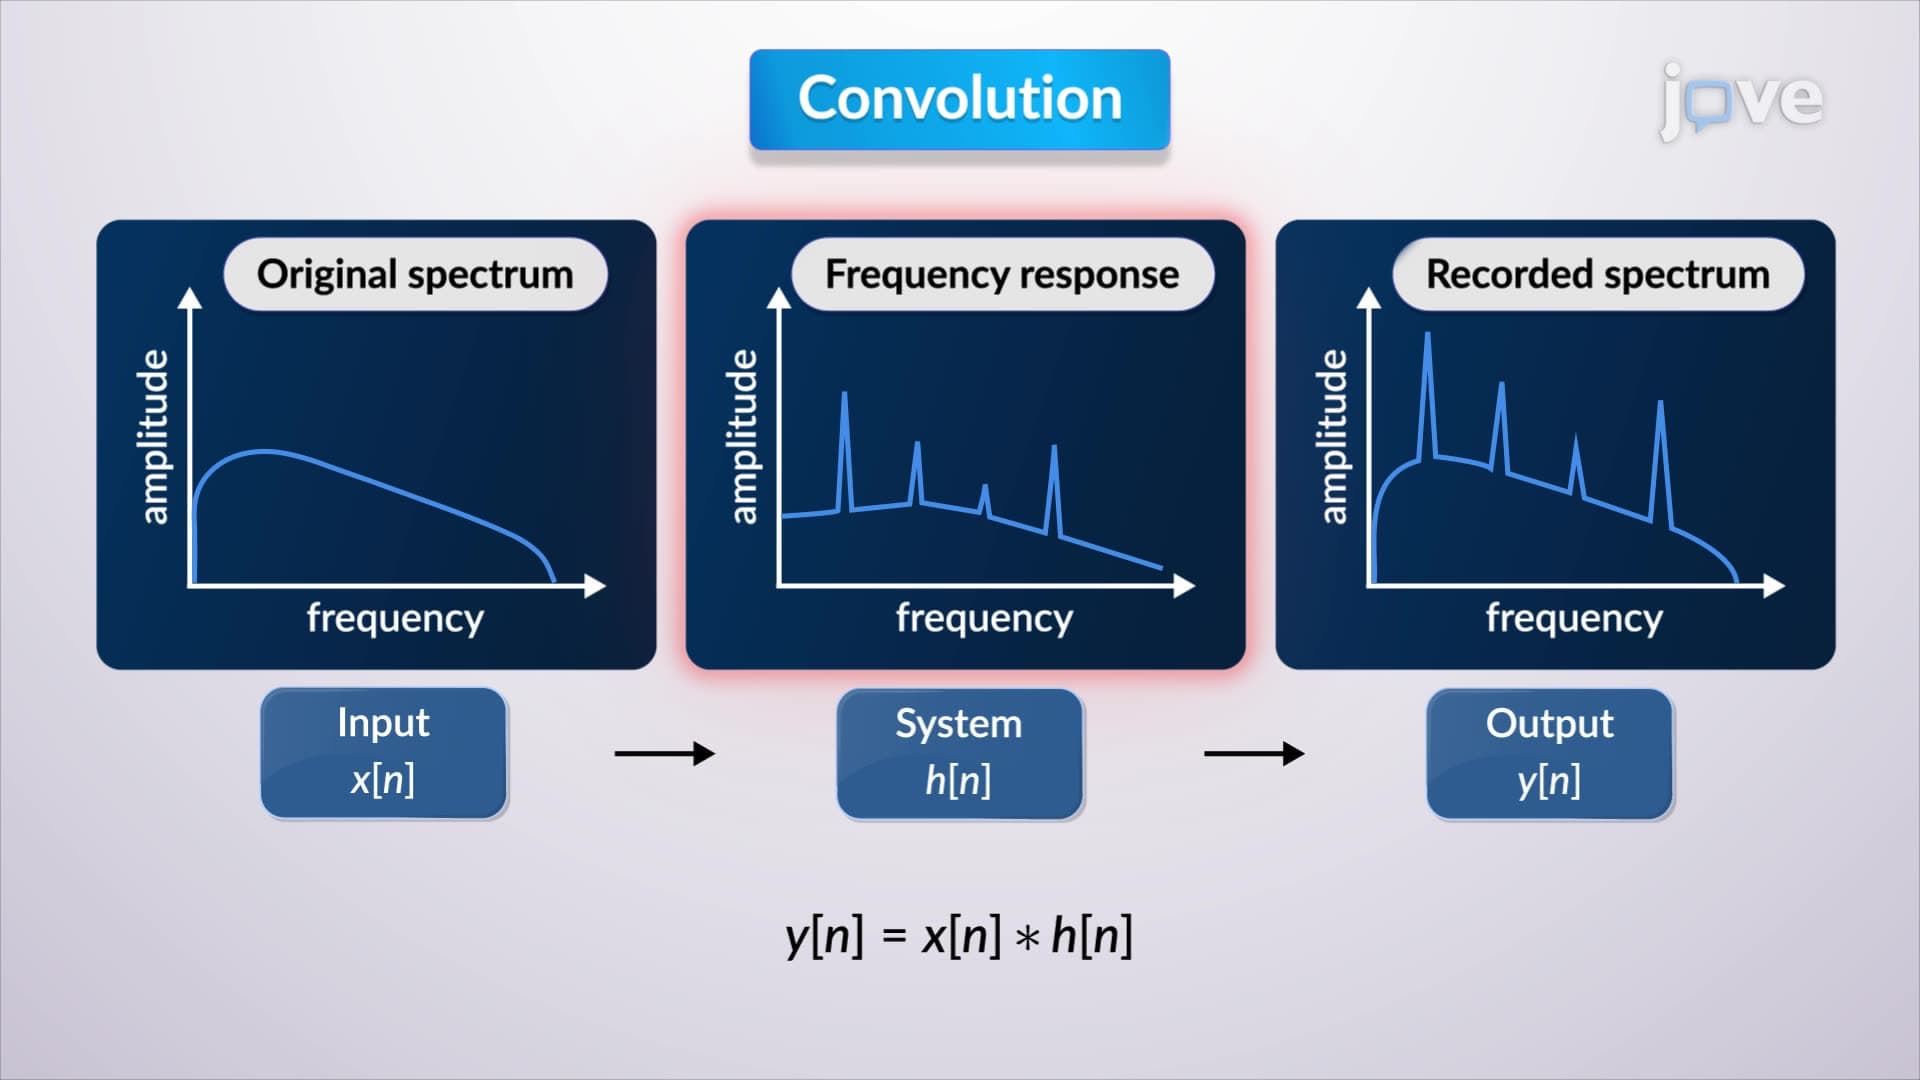
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
 01:20
Downsampling
The Fourier transform of the decimated sequence reveals a combination of scaled and shifted versions of the original spectrum. This...
 02:16
Stereotype Content Model
 01:22
Upsampling