Related Experiment Video
Updated: Sep 27, 2025
Author Spotlight: Advancing Large-Scale Neural Dynamics Through HD-MEA Technology
Published on: March 8, 2024
Multimodal Sparse Transformer Network for Audio-Visual Speech Recognition

Abstract:
Automatic speech recognition (ASR) is the major human-machine interface in many intelligent systems, such as intelligent homes, autonomous driving, and servant robots. However, its performance usually significantly deteriorates in the presence of external noise, leading to limitations of its application scenes. The audio-visual speech recognition (AVSR) takes visual information as a complementary modality to enhance the performance of audio speech recognition effectively, particularly in noisy conditions. Recently, the transformer-based architectures have been used to model the audio and video sequences for the AVSR, which achieves a superior performance. However, its performance may be degraded in these architectures due to extracting irrelevant information while modeling long-term dependences. In addition, the motion feature is essential for capturing the spatio-temporal information within the lip region to best utilize visual sequences but has not been considered in the AVSR tasks. Therefore, we propose a multimodal sparse transformer network (MMST) in this article. The sparse self-attention mechanism can improve the concentration of attention on global information by selecting the most relevant parts wisely. Moreover, the motion features are seamlessly introduced into the MMST model. We subtly allow motion-modality information to flow into visual modality through the cross-modal attention module to enhance visual features, thereby further improving recognition performance. Extensive experiments conducted on different datasets validate that our proposed method outperforms several state-of-the-art methods in terms of the word error rate (WER).
Related Concept Videos
 01:16
Types Of Transformers
If the ratio of the number of turns in the secondary winding to that of the primary winding is greater than one, then the transformer is said to be a step-up transformer. In a step-up transformer, the voltage at the secondary winding is greater than the voltage applied at the primary winding.
However, if this ratio is less than one, the transformer is said to be a step-down...
 01:26
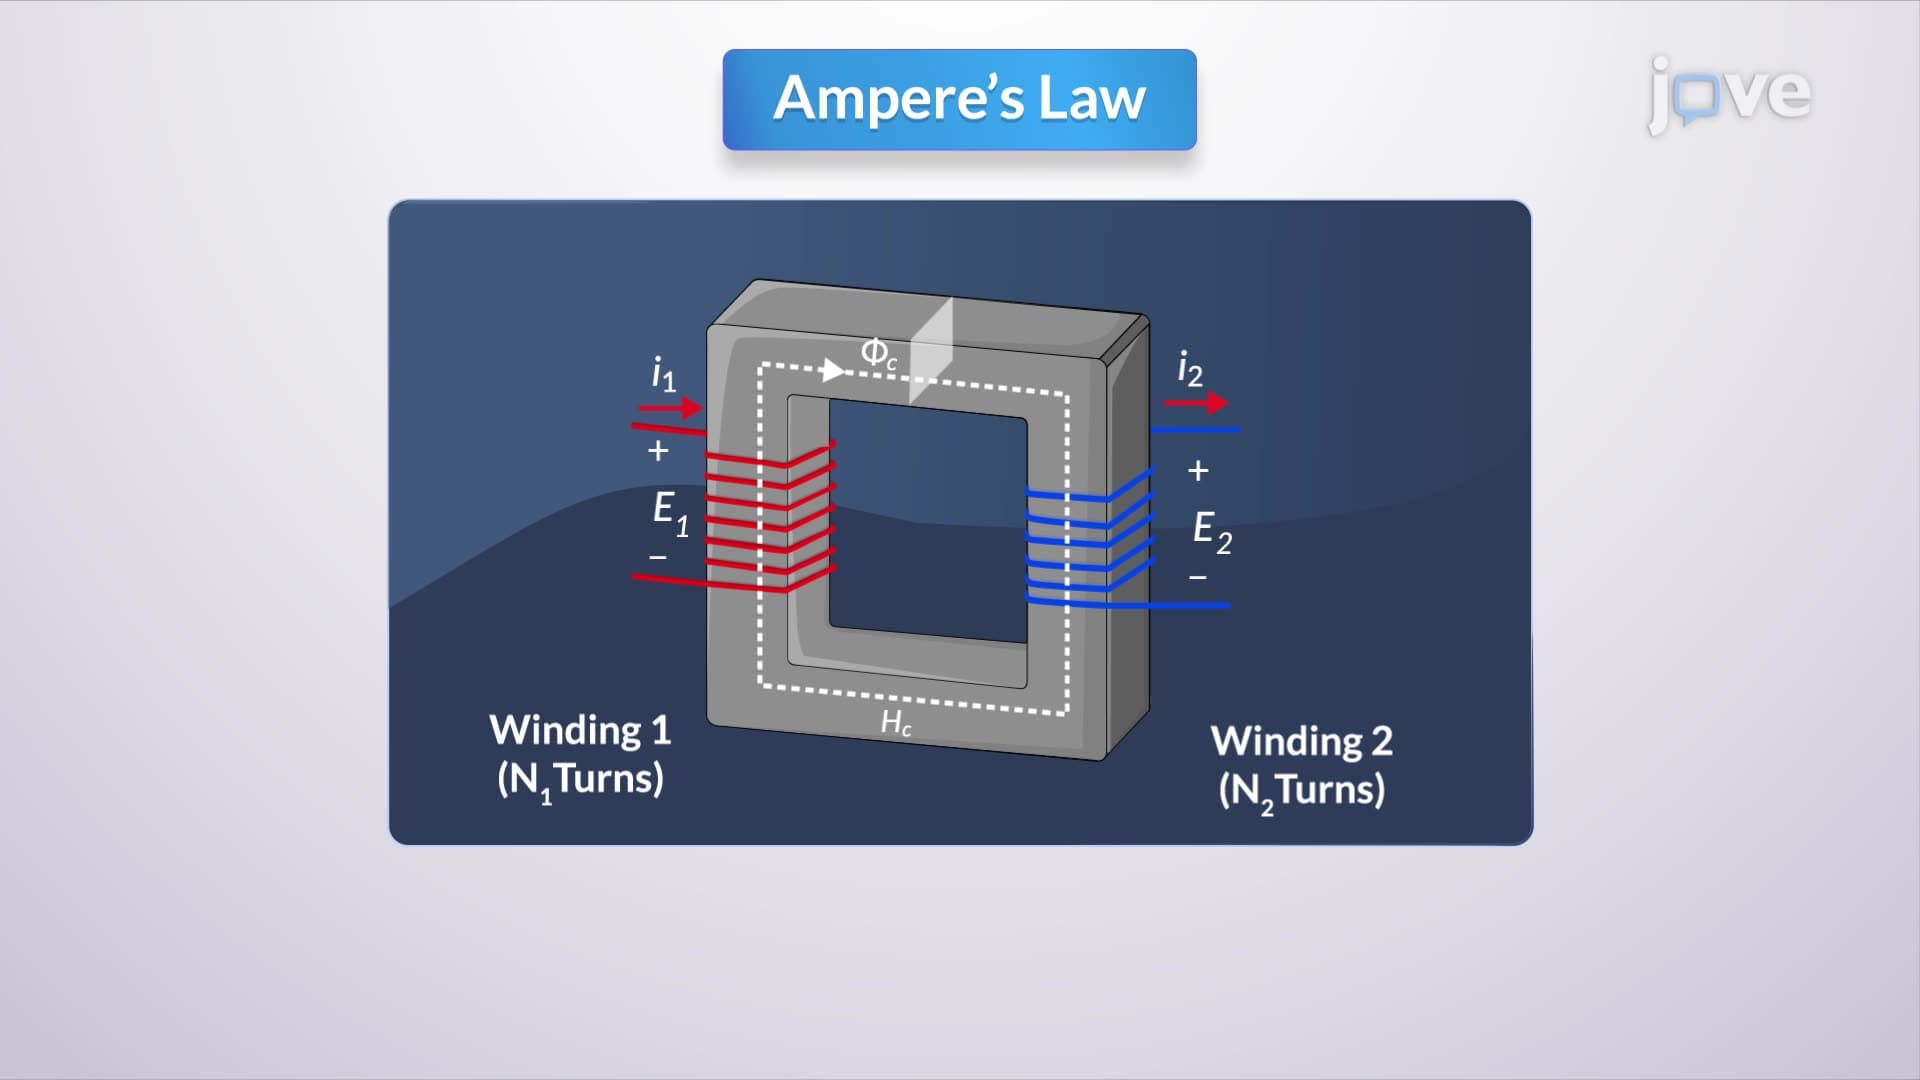
The Ideal Transformer
Ampere's Law forms the basis of understanding the magnetic field within the transformer. It states that the integral of the magnetic field intensity's...
 01:22
Multi-input and Multi-variable systems
In the absence...
 01:30
Classification of Signals
A continuous-time signal holds a value at every instant in time, representing information seamlessly. In contrast, a discrete-time signal holds values only at specific moments, often denoted as x(n), where...
 01:27
Transformers in Distribution System
Distribution substation transformers come in various ratings and typically use mineral oil for insulation and cooling. To prevent moisture and air from entering the oil, some transformers use an inert gas like nitrogen to fill the...
 01:25
Neural Circuits
Neuronal pools are collections of nerve cells with similar functions and interact through chemical and electrical signals. These pools include both interneurons (the central neural circuit nodes that...