Related Experiment Video
Updated: Sep 22, 2025

Psychophysically-anchored, Robust Thresholding in Studying Pain-related Lateralization of Oscillatory Prestimulus Activity
Published on: January 21, 2017
Why and how we should join the shift from significance testing to estimation
Daniel Berner1, Valentin Amrhein1
1Department of Environmental Sciences, Zoology, University of Basel, Basel, Switzerland.

Abstract:
A paradigm shift away from null hypothesis significance testing seems in progress. Based on simulations, we illustrate some of the underlying motivations. First, p-values vary strongly from study to study, hence dichotomous inference using significance thresholds is usually unjustified. Second, 'statistically significant' results have overestimated effect sizes, a bias declining with increasing statistical power. Third, 'statistically non-significant' results have underestimated effect sizes, and this bias gets stronger with higher statistical power. Fourth, the tested statistical hypotheses usually lack biological justification and are often uninformative. Despite these problems, a screen of 48 papers from the 2020 volume of the Journal of Evolutionary Biology exemplifies that significance testing is still used almost universally in evolutionary biology. All screened studies tested default null hypotheses of zero effect with the default significance threshold of p = 0.05, none presented a pre-specified alternative hypothesis, pre-study power calculation and the probability of 'false negatives' (beta error rate). The results sections of the papers presented 49 significance tests on average (median 23, range 0-390). Of 41 studies that contained verbal descriptions of a 'statistically non-significant' result, 26 (63%) falsely claimed the absence of an effect. We conclude that studies in ecology and evolutionary biology are mostly exploratory and descriptive. We should thus shift from claiming to 'test' specific hypotheses statistically to describing and discussing many hypotheses (possible true effect sizes) that are most compatible with our data, given our statistical model. We already have the means for doing so, because we routinely present compatibility ('confidence') intervals covering these hypotheses.
Related Concept Videos
 01:14
Decision Making: Traditional Method
First, a specific claim about the population parameter is decided based on the research question and is stated in a simple form. Further, an opposing statement to this claim is also stated. These statements can act as null and alternative hypotheses, out of which a null hypothesis would be a...
 01:04
Significance Testing: Overview
 01:09
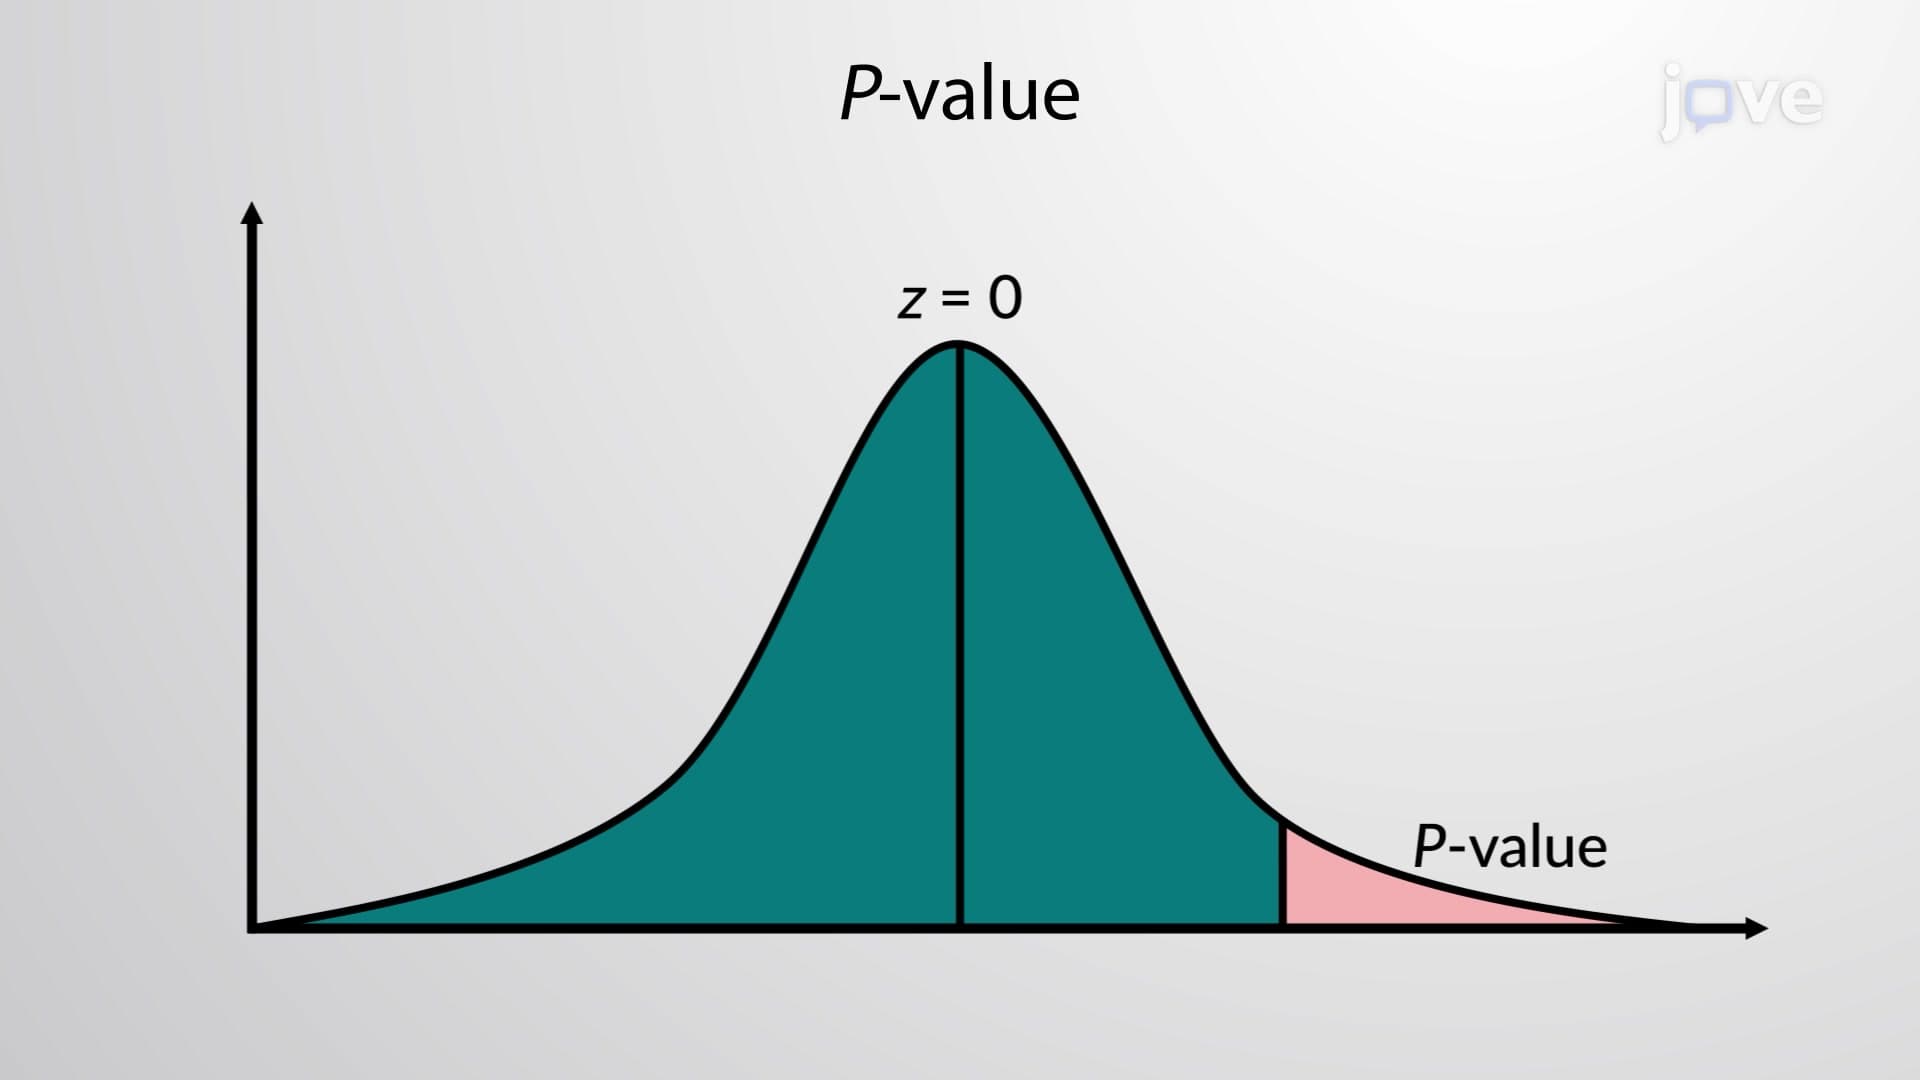
Decision Making: P-value Method
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
 01:06
What are Estimates?
The estimate for the mean of a sample is denoted by ͞x, whereas the mean of the population is designated as μ. Further, parameters such...
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...
 01:16
Statistical Hypothesis Testing
Statistical significance measures the probability that an observed result occurred by chance. If this probability, known as...