Related Experiment Video
Updated: Sep 21, 2025

Synthetic, Multi-Layer, Self-Oscillating Vocal Fold Model Fabrication
Published on: December 2, 2011
Dual-path transformer-based network with equalization-generation components prediction for flexible vibrational
Changyan Zheng1, Liguo Xu1, Xiaohu Fan1
1High-tech Institute, Fan Gong-ting South Street on the 12th, Weifang 261000, China.

Abstract:
The flexible vibrational sensor (FVS) has the potential to become a popular wearable communication device because of its natural noise shielding characteristics and soft materials. However, FVS speech faces a severe loss of frequency components. To improve speech quality, a time-domain neural network model based on the dual-path transformer combined with equalization-generation components prediction (DPT-EGNet) is proposed. More specifically, the DPT-EGNet consists of five modules, namely the pre-processing module, dual-path transformer module, equalization module, generation module, and post-processing module. The dual-path transformer module is leveraged to extract the local and global contextual relationship of long-term speech sequences, which is extremely beneficial for inferring the missing components. The equalization and generation modules are designed according to the characteristics of FVS speech, which further improve the speech quality by simulating the inversion process of the speech distortion. The experimental results demonstrate that the proposed model effectively improves the quality of FVS speech; the average perceptual evaluation of speech quality (PESQ), short-time objective intelligibility (STOI), and composite measure for overall speech quality (COVL) scores of three males and three females are relatively increased by 64.19%, 29.63%, and 101.37%, which is superior to other baseline models developed in different domains. The proposed model also has significantly lower complexity than the others.
More Related Videos
 11:44
Real-Time DC-dynamic Biasing Method for Switching Time Improvement in Severely Underdamped Fringing-field Electrostatic MEMS Actuators
Published on: August 15, 2014
 05:48
Author Spotlight: Investigating the Impact of Emotional Prosodies on Voice Recognition and Perception
Published on: August 9, 2024
Related Concept Videos
 01:10
Reconstruction of Signal using Interpolation
 01:26
Linear Approximation in Frequency Domain
In contrast, nonlinear systems do not inherently possess these properties. However, for small deviations around an operating point, a nonlinear system can often be approximated as linear....
 01:28
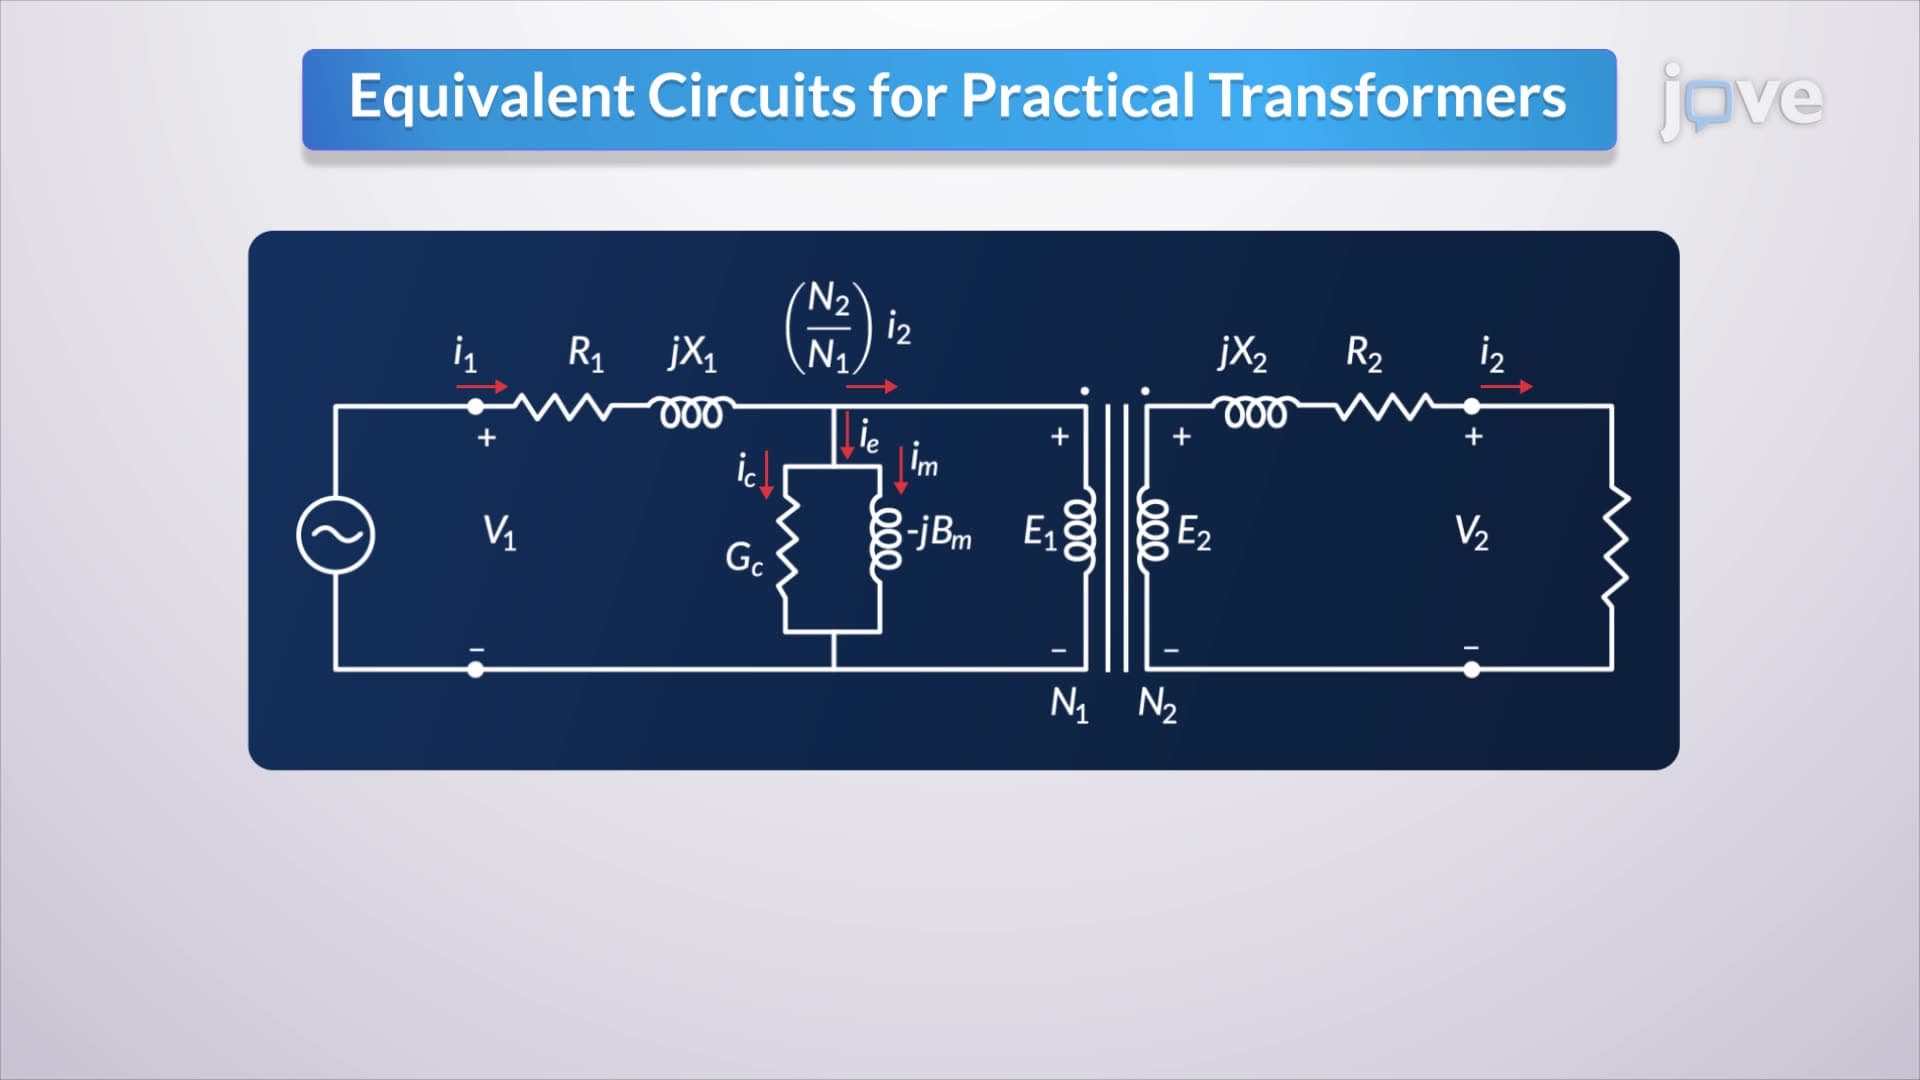
Equivalent Circuits for Practical Transformers
In a practical transformer, each winding exhibits resistance and leakage reactance. The...
 01:21
Linear Approximation in Time Domain
For a simple pendulum with a mass evenly distributed along its length and the center of mass located at half the pendulum's length,...
 01:23
Design Example
 01:16
Types Of Transformers
If the ratio of the number of turns in the secondary winding to that of the primary winding is greater than one, then the transformer is said to be a step-up transformer. In a step-up transformer, the voltage at the secondary winding is greater than the voltage applied at the primary winding.
However, if this ratio is less than one, the transformer is said to be a step-down...