Fitting Bell Curves to Data Distributions Using Visualization
Related Experiment Video
Updated: Aug 27, 2025
Visualizing Intracellular SNARE Trafficking by Fluorescence Lifetime Imaging Microscopy
Published on: December 29, 2017

Abstract:
Idealized probability distributions, such as normal or other curves, lie at the root of confirmatory statistical tests. But how well do people understand these idealized curves? In practical terms, does the human visual system allow us to match sample data distributions with hypothesized population distributions from which those samples might have been drawn? And how do different visualization techniques impact this capability? This article shares the results of a crowdsourced experiment that tested the ability of respondents to fit normal curves to four different data distribution visualizations: bar histograms, dotplot histograms, strip plots, and boxplots. We find that the crowd can estimate the center (mean) of a distribution with some success and little bias. We also find that people generally overestimate the standard deviation-which we dub the "umbrella effect" because people tend to want to cover the whole distribution using the curve, as if sheltering it from the heavens above-and that strip plots yield the best accuracy.

Related Concept Videos
 01:21
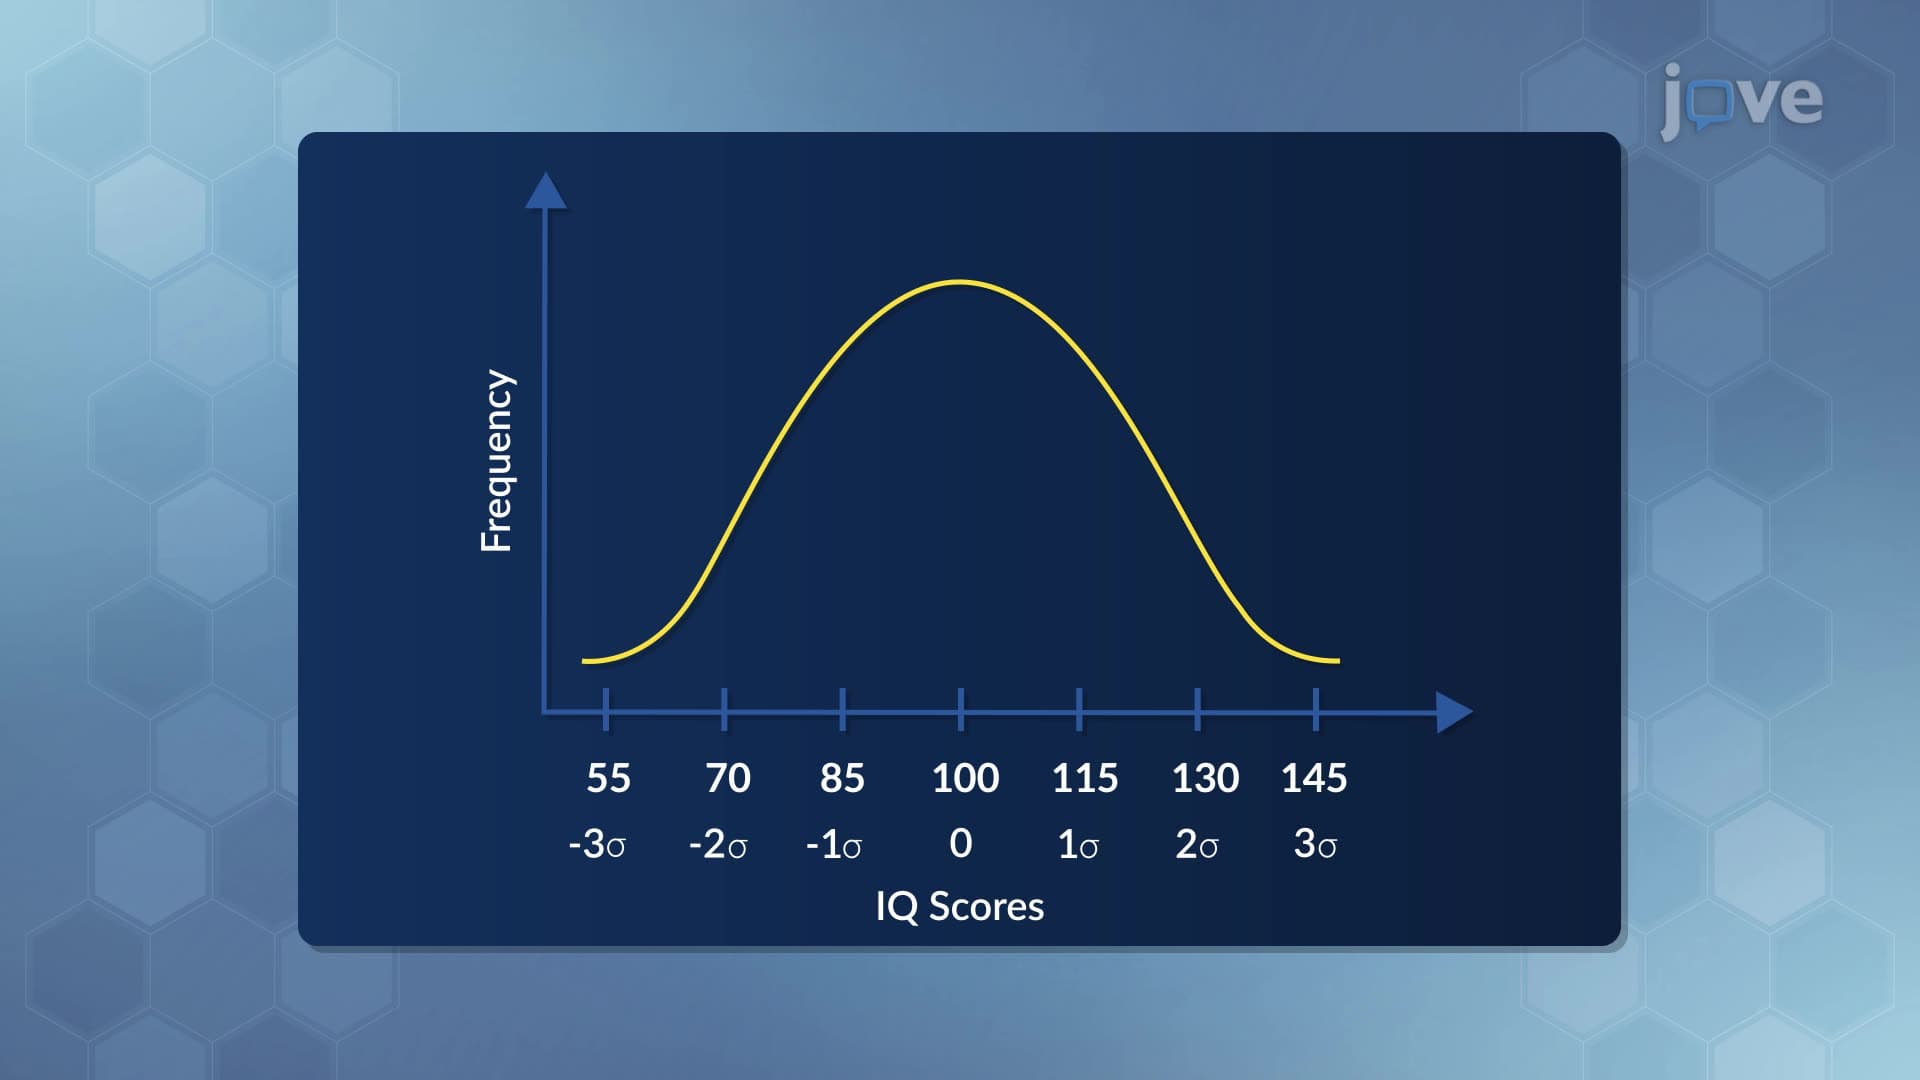
The Bell Curve
This pattern applies to many human characteristics beyond intelligence, such as height. For example, if you...
 01:18
Survival Curves
The Kaplan-Meier estimator is the most common method for constructing survival curves. This...
 01:19
Data: Types and Distribution
Distributions in...
 01:17
Probability Histograms
 00:57
Modified Boxplots
However, the box plot does not tell the reader about outliers - values that lie far from the center of the data. We can modify the standard box and whisker plot to identify the outliers and visualize the actual spread of the data in a sample.
Initially, we calculate the adjusted...
 01:24
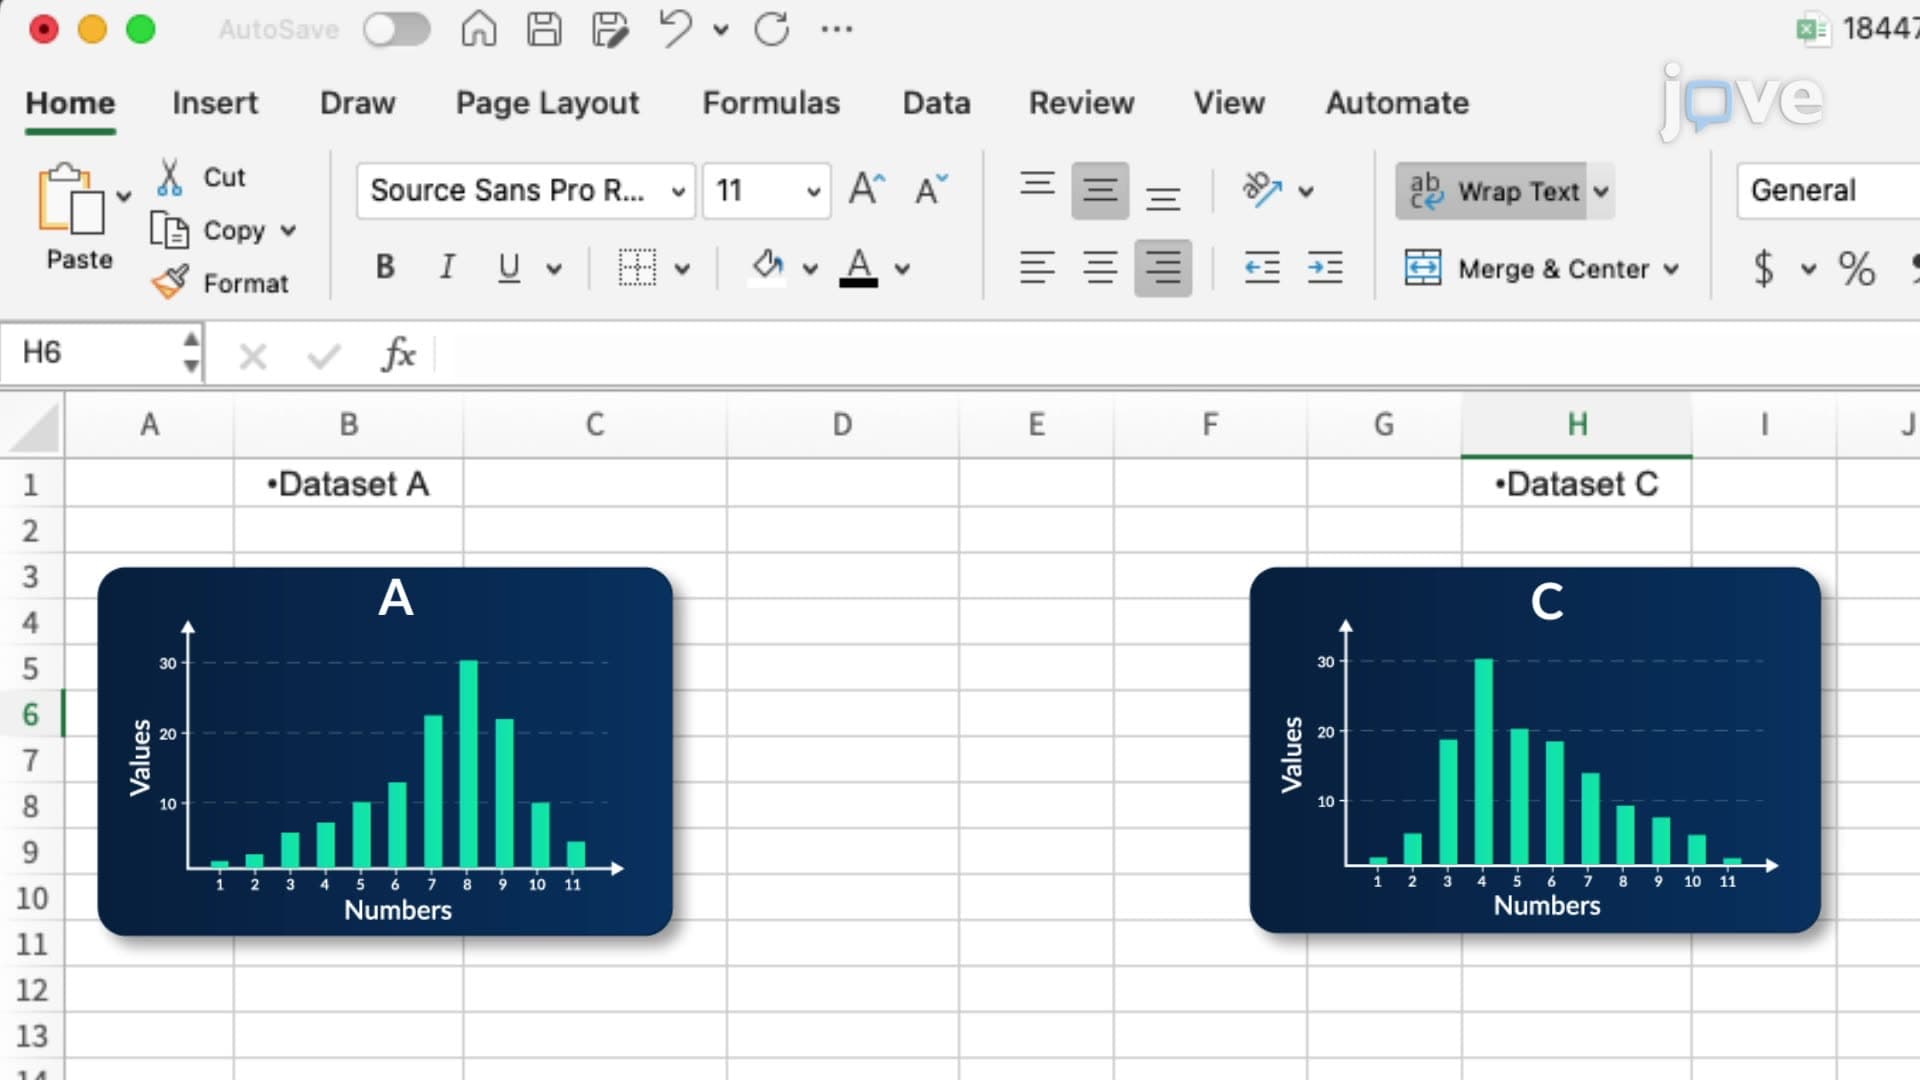
Microsoft Excel: Finding Central Tendency, Skew, and Kurtosis
Mean: The arithmetic average of all data points. It is calculated by adding all the values together and dividing by the number of values. The mean is sensitive to extreme values (outliers).
Median: The middle value when the data points are arranged in ascending or descending...