Related Experiment Video
Updated: Aug 9, 2025


Selecting Multiple Biomarker Subsets with Similarly Effective Binary Classification Performances
Published on: October 11, 2018
Variable Selection for Sparse Data with Applications to Vaginal Microbiome and Gene Expression Data
Niloufar Dousti Mousavi1, Jie Yang1, Hani Aldirawi2
1Department of Mathematics, Statistics, and Computer Science, University of Illinois at Chicago, Chicago, IL 60607, USA.

Abstract:
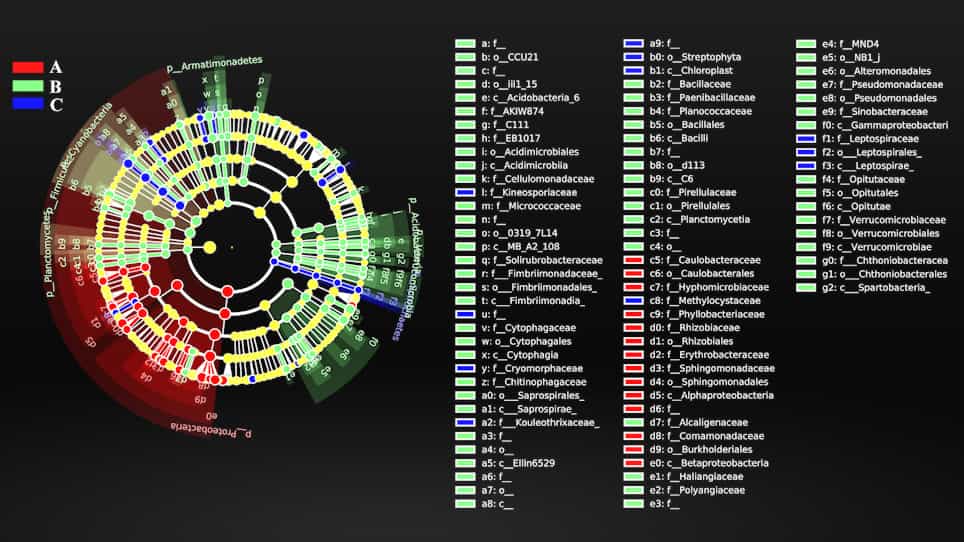
Sparse data with a high portion of zeros arise in various disciplines. Modeling sparse high-dimensional data is a challenging and growing research area. In this paper, we provide statistical methods and tools for analyzing sparse data in a fairly general and complex context. We utilize two real scientific applications as illustrations, including a longitudinal vaginal microbiome data and a high dimensional gene expression data. We recommend zero-inflated model selections and significance tests to identify the time intervals when the pregnant and non-pregnant groups of women are significantly different in terms of Lactobacillus species. We apply the same techniques to select the best 50 genes out of 2426 sparse gene expression data. The classification based on our selected genes achieves 100% prediction accuracy. Furthermore, the first four principal components based on the selected genes can explain as high as 83% of the model variability.
Related Concept Videos
 01:25
Genetic Variation
Genes exist in different versions called alleles,...
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
 02:34
DNA Microarrays
 01:21
Frequency-dependent Selection
 01:12
Statistical Software for Data Analysis and Clinical Trials
 01:11
Genome-wide Association Studies-GWAS
GWAS does not require the identification of the target gene involved in...