Related Experiment Video
Updated: Jul 29, 2025

Self-assembling Morphologies Obtained from Helical Polycarbodiimide Copolymers and Their Triazole Derivatives
Published on: February 7, 2017
Interpretable Machine Learning Models for Phase Prediction in Polymerization-Induced Self-Assembly
Yiwen Lu1, Dilek Yalcin2,3, Paul J Pigram3
1Department for Data Science and AI, Monash University, Wellington Road, Clayton, VIC 3168, Australia.

Abstract:
While polymerization-induced self-assembly (PISA) has become a preferred synthetic route toward amphiphilic block copolymer self-assemblies, predicting their phase behavior from experimental design is extremely challenging, requiring time and work-intensive creation of empirical phase diagrams whenever self-assemblies of novel monomer pairs are sought for specific applications. To alleviate this burden, we develop here the first framework for a data-driven methodology for the probabilistic modeling of PISA morphologies based on a selection and suitable adaption of statistical machine learning methods. As the complexity of PISA precludes generating large volumes of training data with in silico simulations, we focus on interpretable low variance methods that can be interrogated for conformity with chemical intuition and that promise to work well with only 592 training data points which we curated from the PISA literature. We found that among the evaluated linear models, generalized additive models, and rule and tree ensembles, all but the linear models show a decent interpolation performance with around 0.2 estimated error rate and 1 bit expected cross entropy loss (surprisal) when predicting the mixture of morphologies formed from monomer pairs already encountered in the training data. When considering extrapolation to new monomer combinations, the model performance is weaker but the best model (random forest) still achieves highly nontrivial prediction performance (0.27 error rate, 1.6 bit surprisal), which renders it a good candidate to support the creation of empirical phase diagrams for new monomers and conditions. Indeed, we find in three case studies that, when used to actively learn phase diagrams, the model is able to select a smart set of experiments that lead to satisfactory phase diagrams after observing only relatively few data points (5-16) for the targeted conditions. The data set as well as all model training and evaluation codes are publicly available through the GitHub repository of the last author.
Related Concept Videos
 01:08
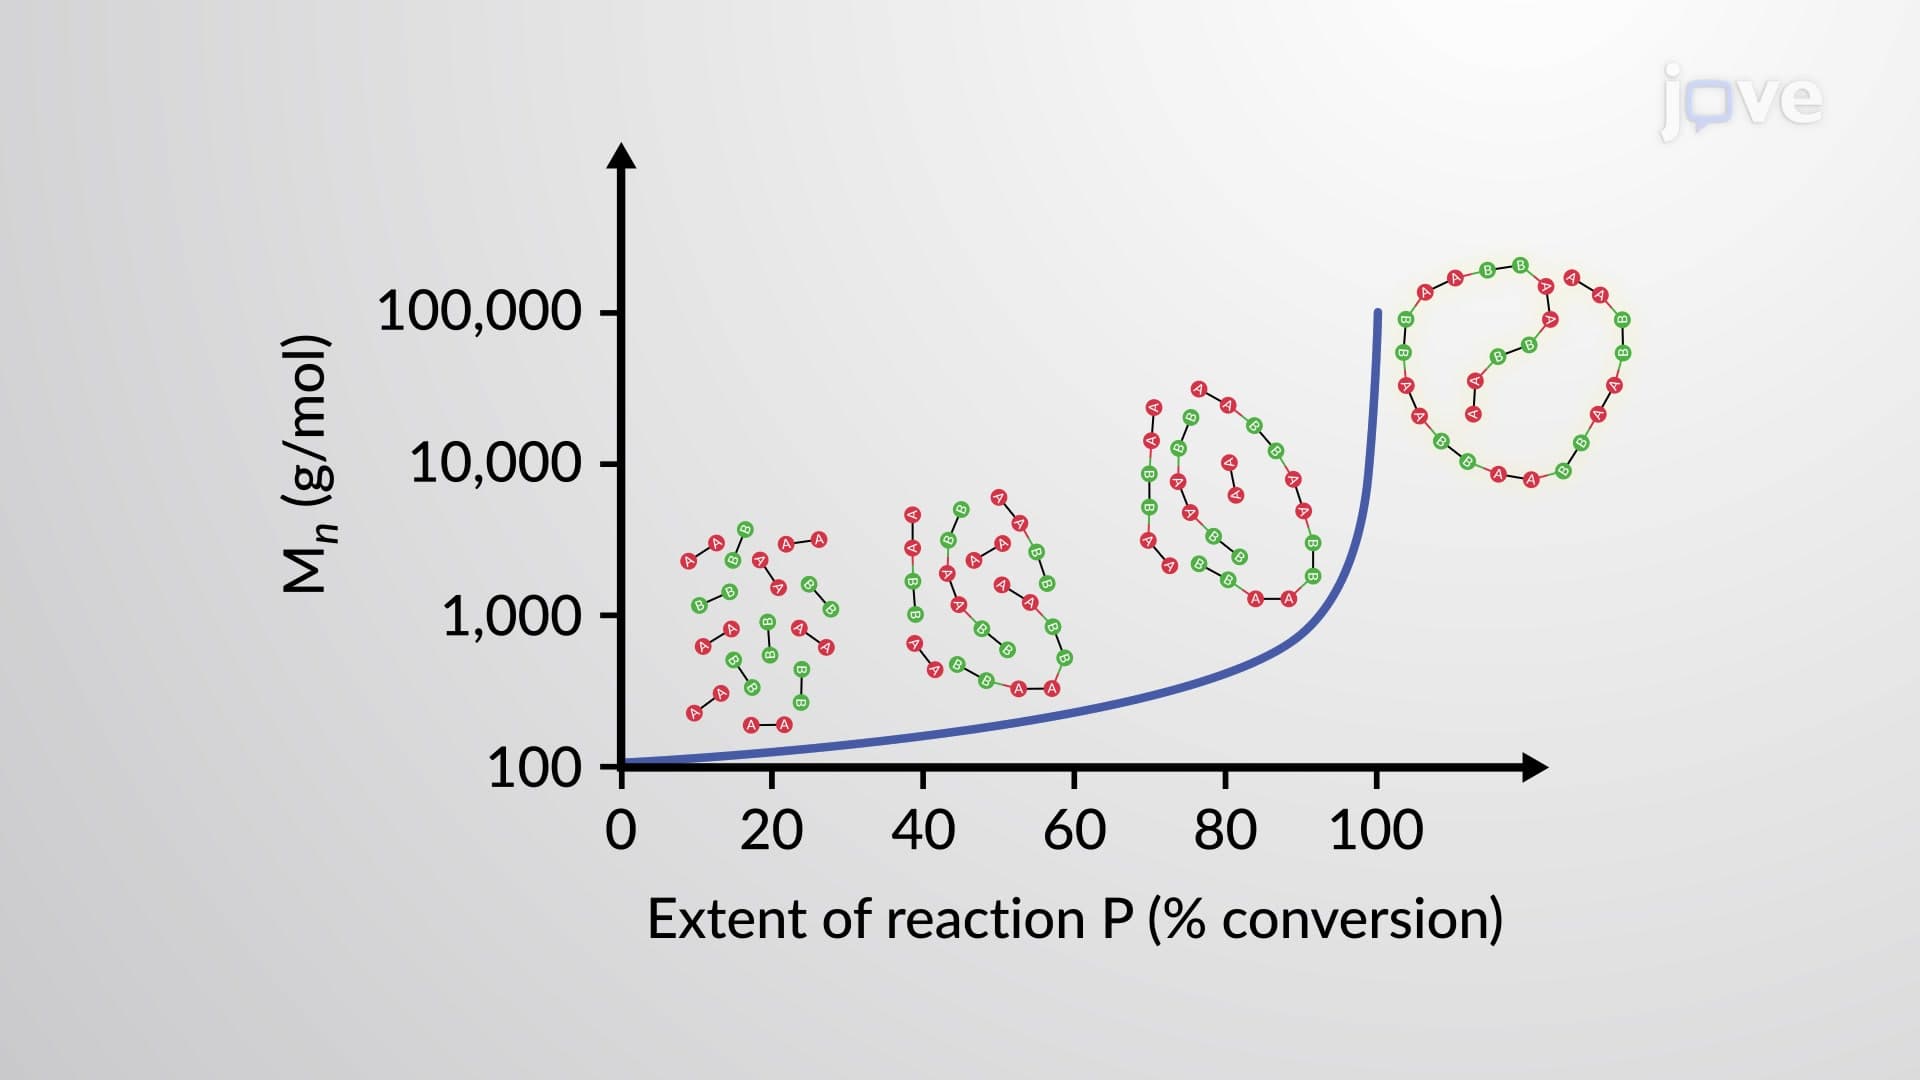
Molecular Weight of Step-Growth Polymers
As the step-growth polymerization involves step-wise condensation of monomers, the molecular weight also builds up eventually. Consequently, high molecular weight polymers are obtained at the late stages of the polymerization, where 99% of monomers have been consumed.
The extent of the...
 01:03
Step-Growth Polymerization: Overview
Many natural and synthetic polymers are produced by...
 01:21
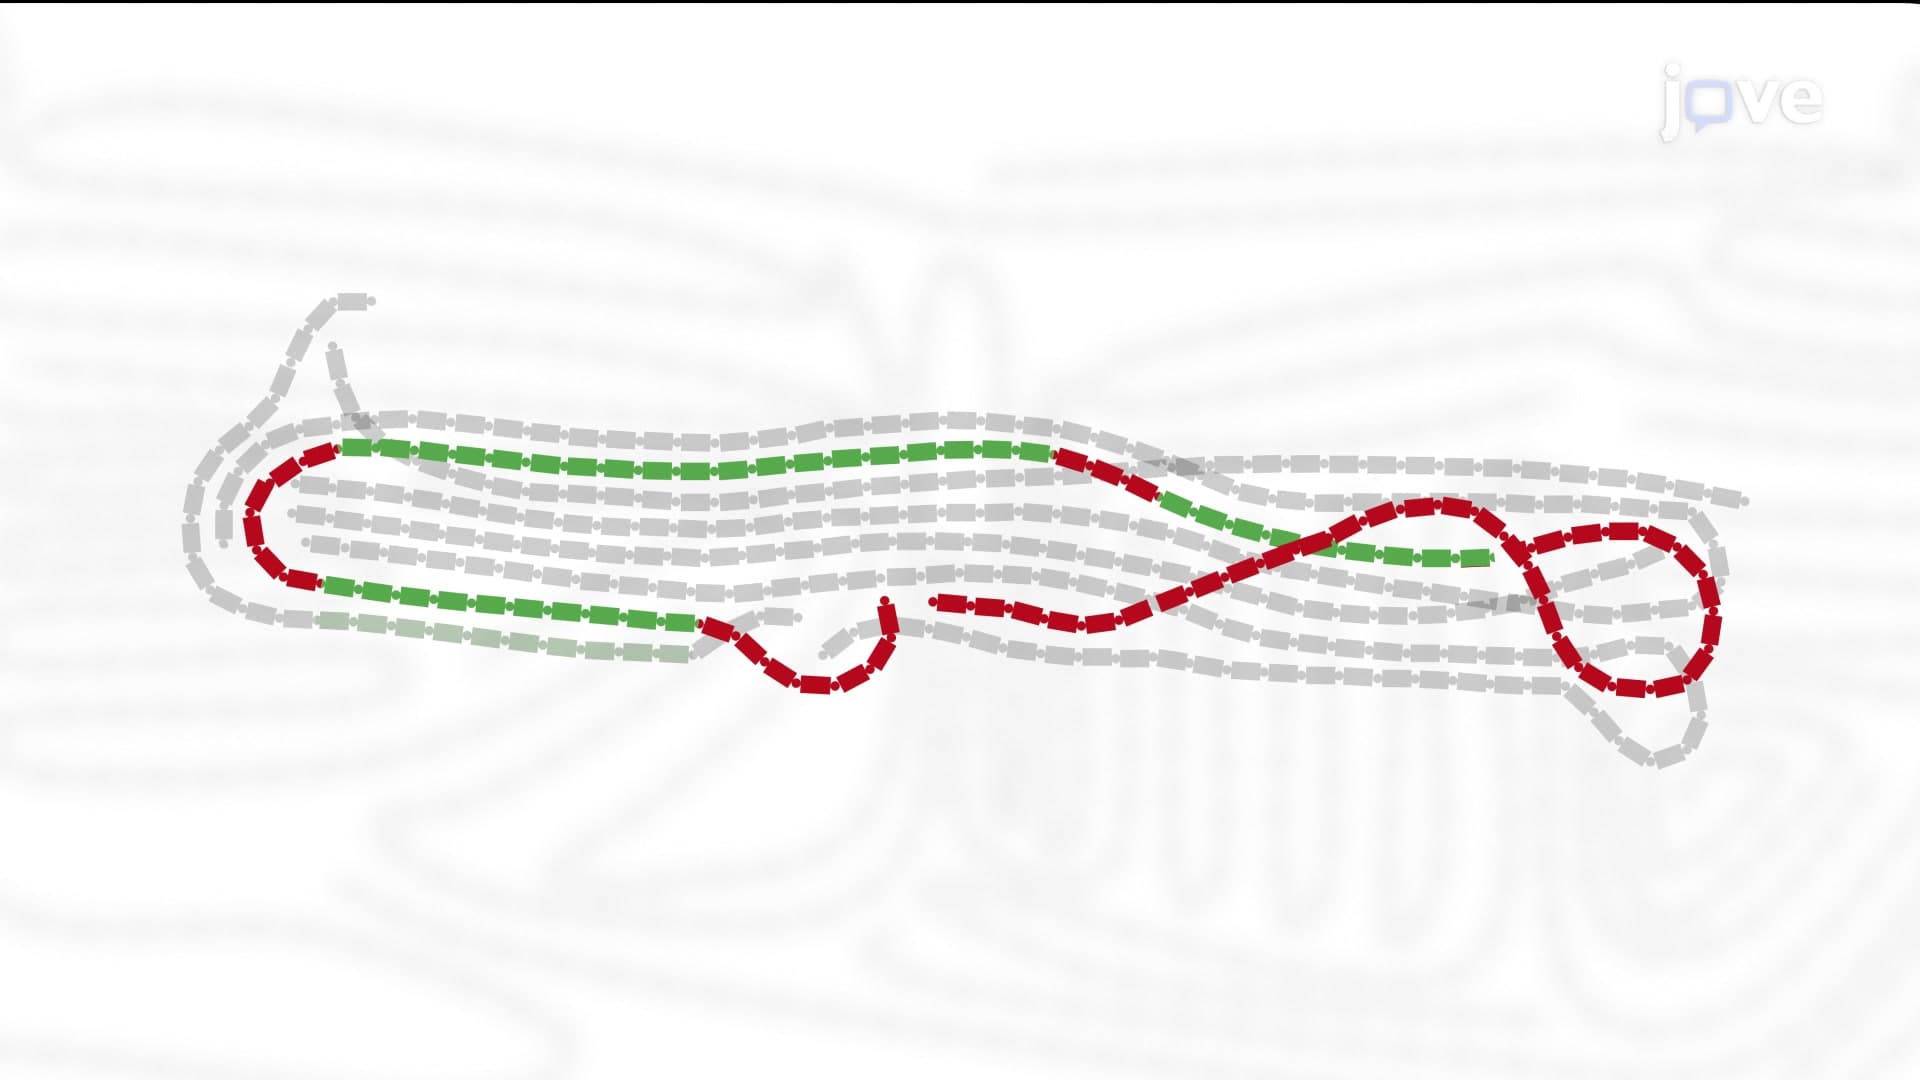
Polymer Classification: Crystallinity
Crystalline domains are the regions where polymer chains are aligned in an orderly manner and held together in proximity by intermolecular forces. For example, chains in the crystalline domains of polyethylene and nylon are bound together by van der Waals...
 01:26
Polymer Classification: Stereospecificity
 01:17
Ziegler–Natta Chain-Growth Polymerization: Overview
 01:04
Anionic Chain-Growth Polymerization: Mechanism