Related Experiment Video
Updated: Jul 27, 2025
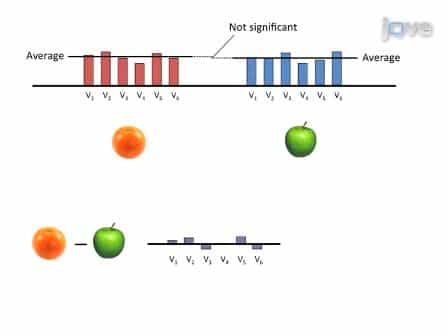

Cross-Modal Multivariate Pattern Analysis
Published on: November 9, 2011
Cross-modal hashing with missing labels
Haomin Ni1, Jianjun Zhang2, Peipei Kang2
1School of Automation, Guangdong University of Technology, No. 100 Waihuan Xi Road, Guangzhou, 510006, Guangdong, China; Guangdong Key Laboratory of IoT Information Technology (GDUT), No. 100 Waihuan Xi Road, Guangzhou, 510006, Guangdong, China.

Abstract:
Hashing-based cross-modal retrieval methods have become increasingly popular due to their advantages in storage and speed. While current methods have demonstrated impressive results, there are still several issues that have not been addressed. Specifically, many of these approaches assume that labels are perfectly assigned, despite the fact that in real-world scenarios, labels are often incomplete or partially missing. There are two reasons for this, as manual labeling can be a complex and time-consuming task, and annotators may only be interested in certain objects. As such, cross-modal retrieval with missing labels is a significant challenge that requires further attention. Moreover, the similarity between labels is frequently ignored, which is important for exploring the high-level semantics of labels. To address these limitations, we propose a novel method called Cross-Modal Hashing with Missing Labels (CMHML). Our method consists of several key components. First, we introduce Reliable Label Learning to preserve reliable information from the observed labels. Next, to infer the uncertain part of the predicted labels, we decompose the predicted labels into latent representations of labels and samples. The representation of samples is extracted from different modalities, which assists in inferring missing labels. We also propose Label Correlation Preservation to enhance the similarity between latent representations of labels. Hash codes are then learned from the representation of samples through Global Approximation Learning. We also construct a similarity matrix according to predicted labels and embed it into hash codes learning to explore the value of labels. Finally, we train linear classifiers to map original samples to a low-dimensional Hamming space. To evaluate the efficacy of CMHML, we conduct extensive experiments on four publicly available datasets. Our method is compared to other state-of-the-art methods, and the results demonstrate that our model performs competitively even when most labels are missing.


Related Concept Videos
 01:06
Collisions in Multiple Dimensions: Problem Solving
A small car of mass 1,200 kg traveling east at 60 km/h collides at an intersection with a truck of mass 3,000 kg traveling due north at 40 km/h. The two vehicles are locked together. What is the...
 01:05
Collisions in Multiple Dimensions: Introduction
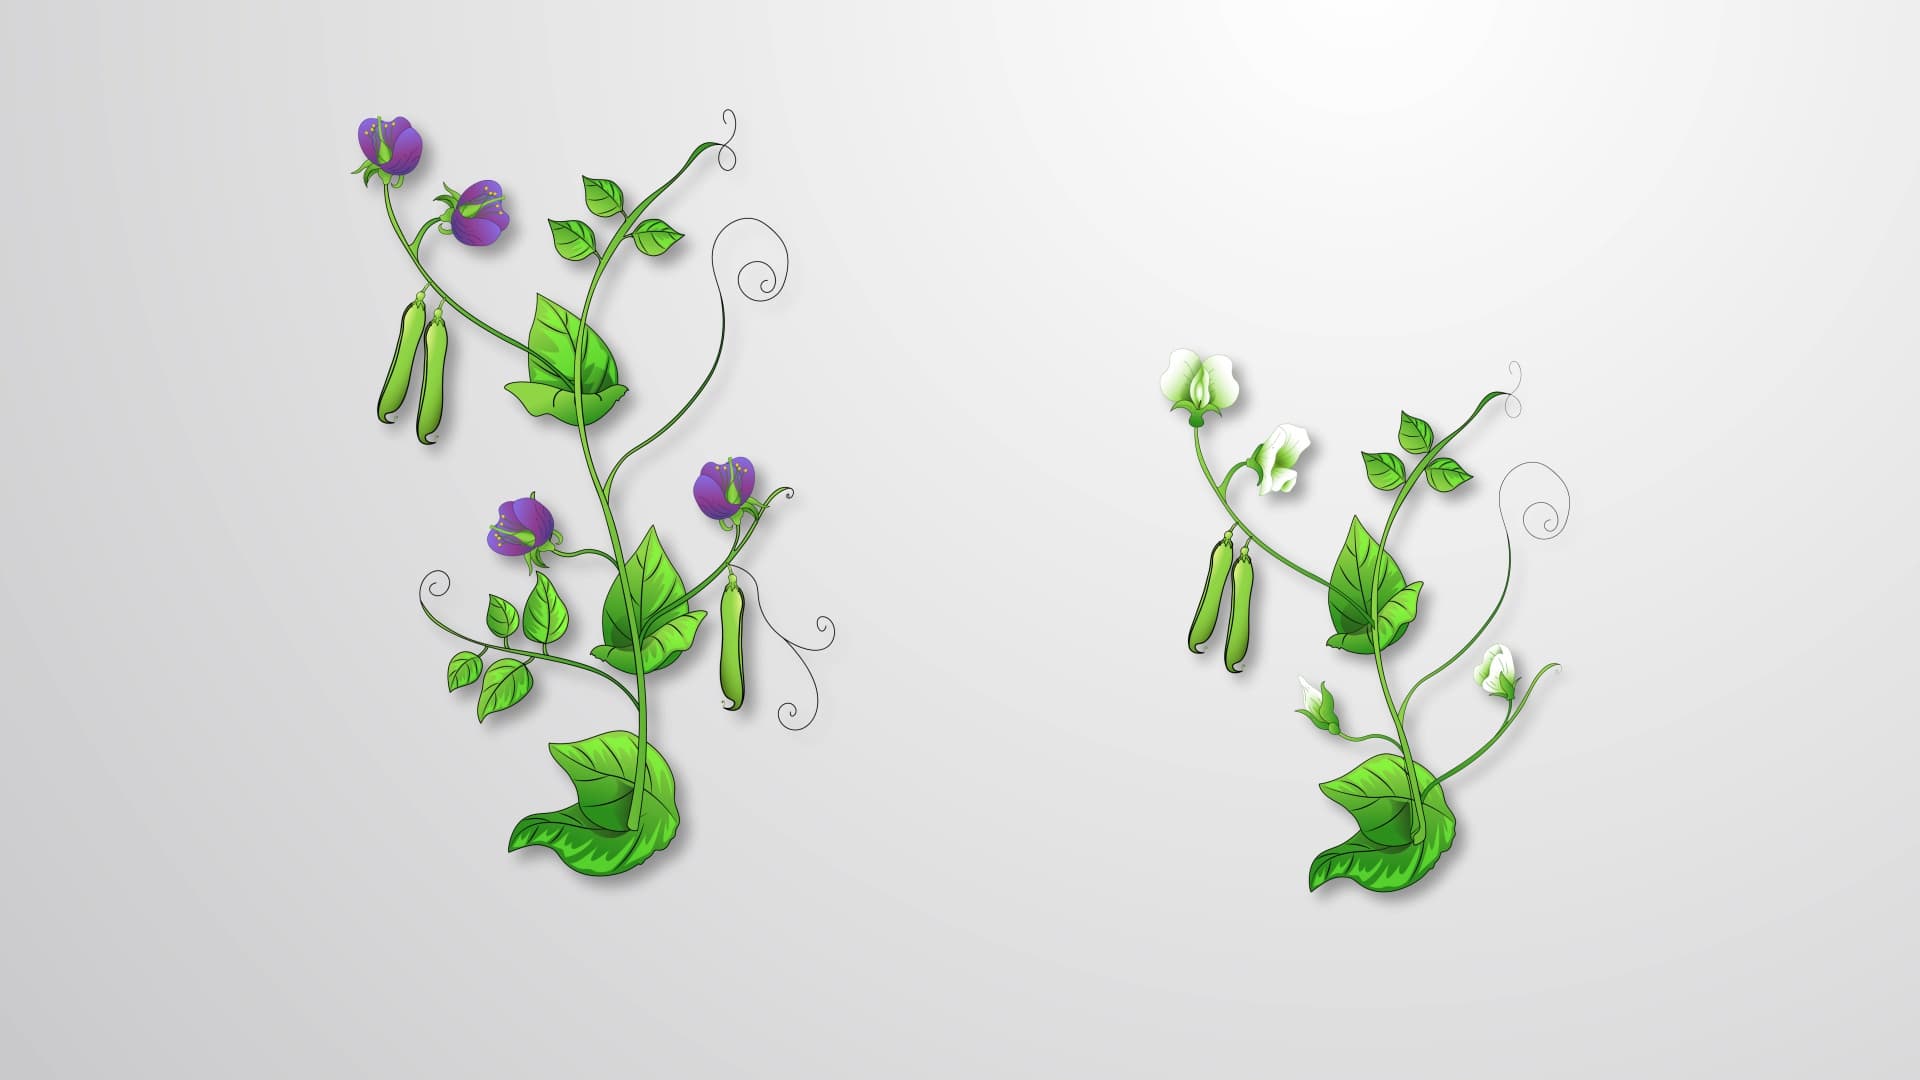 02:03
Law of Independent Assortment
 01:20
Cluster Sampling Method
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
 01:15
Elastic Collisions: Case Study
 01:27
Associative Learning
Classical conditioning, also known...