Related Experiment Video
Updated: Jul 16, 2025


Author Spotlight: A Computational Approach to Decipher Amino Acid Preferences in Multispecific Protein-Protein Interactions
Published on: January 26, 2024
DataDTA: a multi-feature and dual-interaction aggregation framework for drug-target binding affinity prediction
Yan Zhu1, Lingling Zhao1, Naifeng Wen2
1Faculty of Computing, Harbin Institute of Technology, Harbin 150001, China.

Motivation:
Accurate prediction of drug-target binding affinity (DTA) is crucial for drug discovery. The increase in the publication of large-scale DTA datasets enables the development of various computational methods for DTA prediction. Numerous deep learning-based methods have been proposed to predict affinities, some of which only utilize original sequence information or complex structures, but the effective combination of various information and protein-binding pockets have not been fully mined. Therefore, a new method that integrates available key information is urgently needed to predict DTA and accelerate the drug discovery process.
Results:
In this study, we propose a novel deep learning-based predictor termed DataDTA to estimate the affinities of drug-target pairs. DataDTA utilizes descriptors of predicted pockets and sequences of proteins, as well as low-dimensional molecular features and SMILES strings of compounds as inputs. Specifically, the pockets were predicted from the three-dimensional structure of proteins and their descriptors were extracted as the partial input features for DTA prediction. The molecular representation of compounds based on algebraic graph features was collected to supplement the input information of targets. Furthermore, to ensure effective learning of multiscale interaction features, a dual-interaction aggregation neural network strategy was developed. DataDTA was compared with state-of-the-art methods on different datasets, and the results showed that DataDTA is a reliable prediction tool for affinities estimation. Specifically, the concordance index (CI) of DataDTA is 0.806 and the Pearson correlation coefficient (R) value is 0.814 on the test dataset, which is higher than other methods.
Availability And Implementation:
The codes and datasets of DataDTA are available at https://github.com/YanZhu06/DataDTA.
More Related Videos
 08:49
Incorporating Target Protein Structure Flexibility and Dynamics in Computational Drug Discovery Using Ensemble-Based Docking Analysis
Published on: June 20, 2025
 10:21
Author Spotlight: Streamlining Protein Target Prediction and Validation via Molecular Docking and CETSA
Published on: February 23, 2024
Related Concept Videos
 01:30
Quantitative Aspects of Drug-Receptor Interaction
 02:04
Protein-protein Interfaces
 01:28
Structure-Activity Relationships and Drug Design
SAR studies the intricate relationship between a drug's chemical structure and biological activity. It focuses on understanding how modifications to a drug's structure can influence...
 02:40
Ligand Binding Sites
Protein-ligand interactions are quite specific; even though numerous potential ligands surround a cellular protein at any given time, only a particular ligand can bind to that protein. Moreover, a ligand binds only to a dedicated area on the surface of the protein, known as the...
 01:16
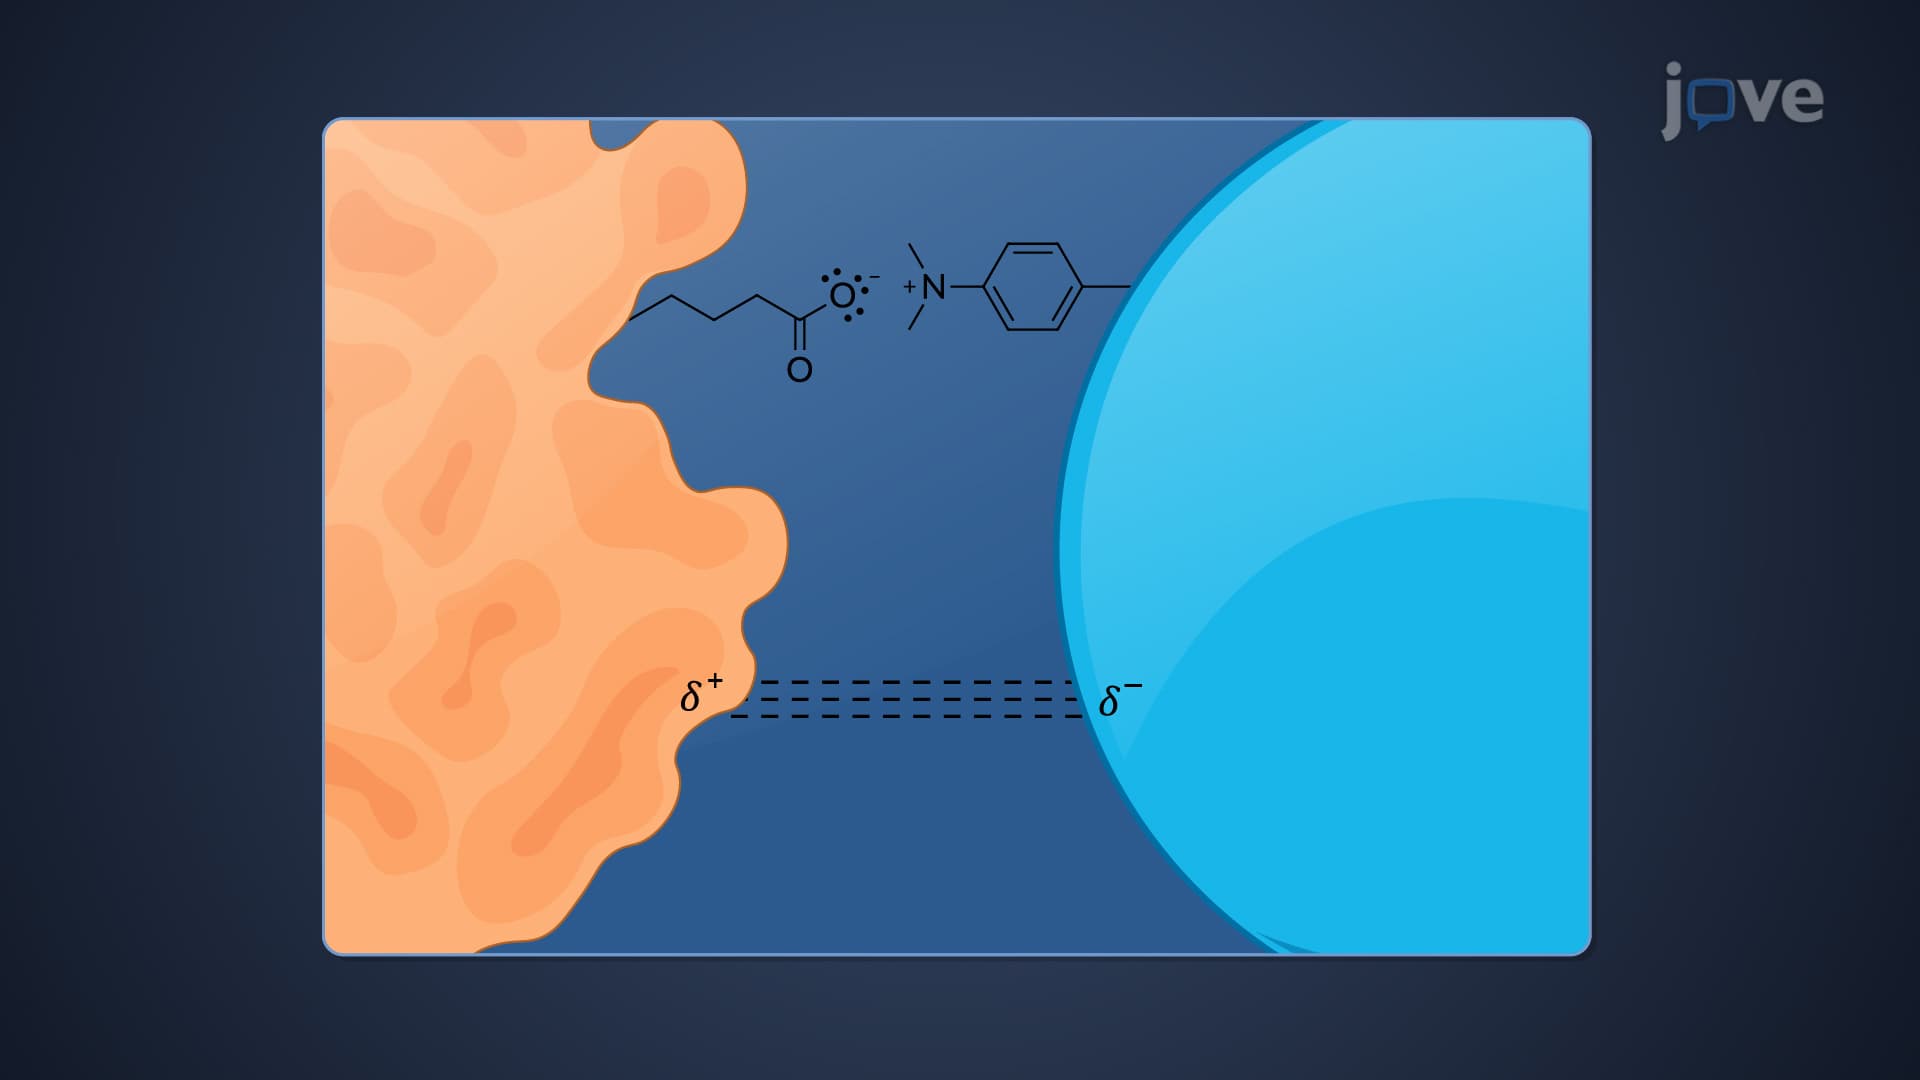
Protein-Drug Binding: Mechanism and Kinetics
Various forces drive these interactions, including hydrogen bonds, hydrophobic interactions, ionic bonds, electrostatic interactions, and van der Waals forces. These bonds enable drugs to bind to specific sites on proteins,...
 01:22
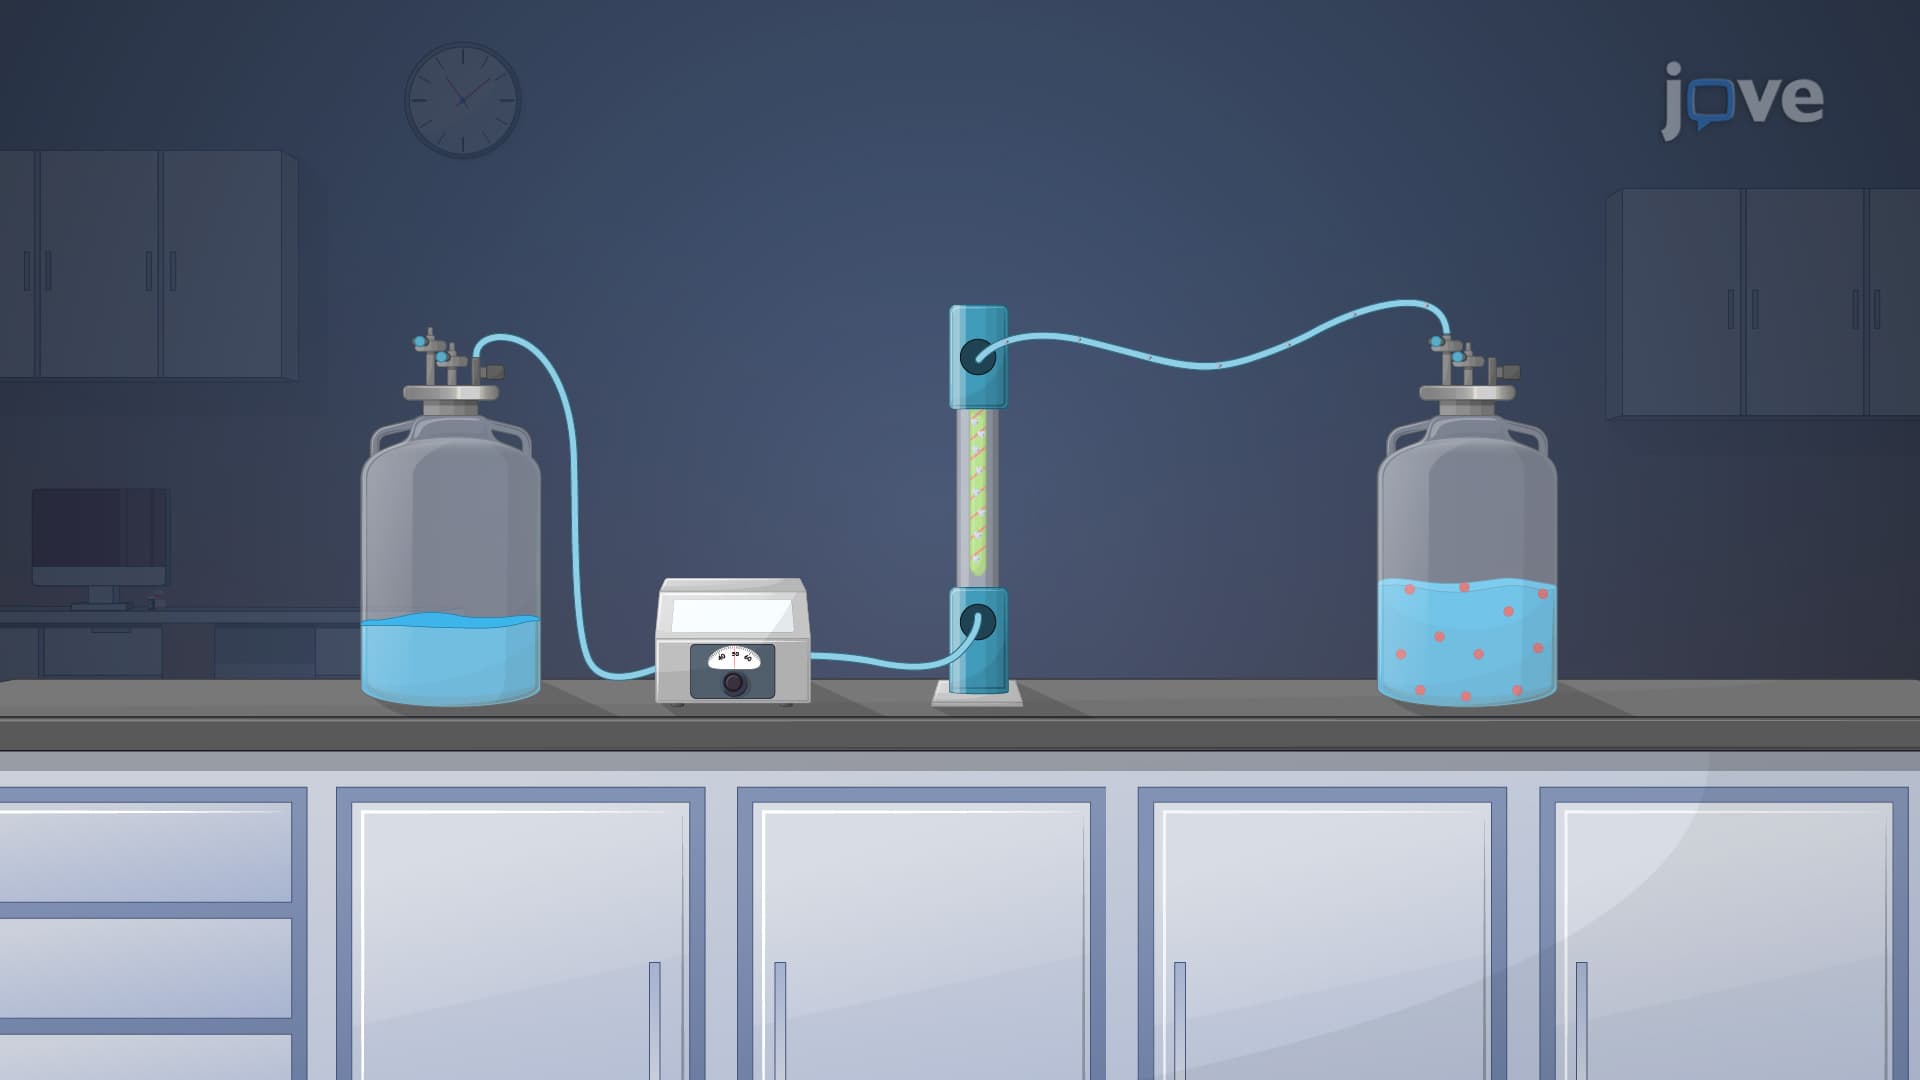
Protein-Drug Binding: Determination Methods
Indirect methods involve isolating the bound drug from its free form in biological samples such as blood, serum, or plasma. These techniques aim to measure the percentage of drugs bound to proteins. Equilibrium dialysis is a commonly used method where the free drug concentration at equilibrium is measured by separating the bound...