Related Experiment Video
Updated: Jul 15, 2025


Closed-loop Neuro-robotic Experiments to Test Computational Properties of Neuronal Networks
Published on: March 2, 2015
Dynamic sparse coding-based value estimation network for deep reinforcement learning
Haoli Zhao1, Zhenni Li2, Wensheng Su2
1School of Automation, Guangdong University of Technology, Guangzhou, 510006, China; Guangdong-HongKong-Macao Joint Laboratory for Smart Discrete Manufacturing, Guangzhou 510006, China.

Abstract:
Deep Reinforcement Learning (DRL) is one powerful tool for varied control automation problems. Performances of DRL highly depend on the accuracy of value estimation for states from environments. However, the Value Estimation Network (VEN) in DRL can be easily influenced by the phenomenon of catastrophic interference from environments and training. In this paper, we propose a Dynamic Sparse Coding-based (DSC) VEN model to obtain precise sparse representations for accurate value prediction and sparse parameters for efficient training, which is not only applicable in Q-learning structured discrete-action DRL but also in actor-critic structured continuous-action DRL. In detail, to alleviate interference in VEN, we propose to employ DSC to learn sparse representations for accurate value estimation with dynamic gradients beyond the conventional ℓ1 norm that provides same-value gradients. To avoid influences from redundant parameters, we employ DSC to prune weights with dynamic thresholds more efficiently than static thresholds like ℓ1 norm. Experiments demonstrate that the proposed algorithms with dynamic sparse coding can obtain higher control performances than existing benchmark DRL algorithms in both discrete-action and continuous-action environments, e.g., over 25% increase in Puddle World and about 10% increase in Hopper. Moreover, the proposed algorithm can reach convergence efficiently with fewer episodes in different environments.
More Related Videos
Related Concept Videos
 01:23
Reinforcement
Positive reinforcement occurs when a behavior is followed by the presentation of a rewarding stimulus, increasing the frequency of that behavior. For example:
 01:15
Expected Value
 01:24
Reinforcement Schedules
Once a behavior is learned,...
 01:12
Observational Learning
 01:09
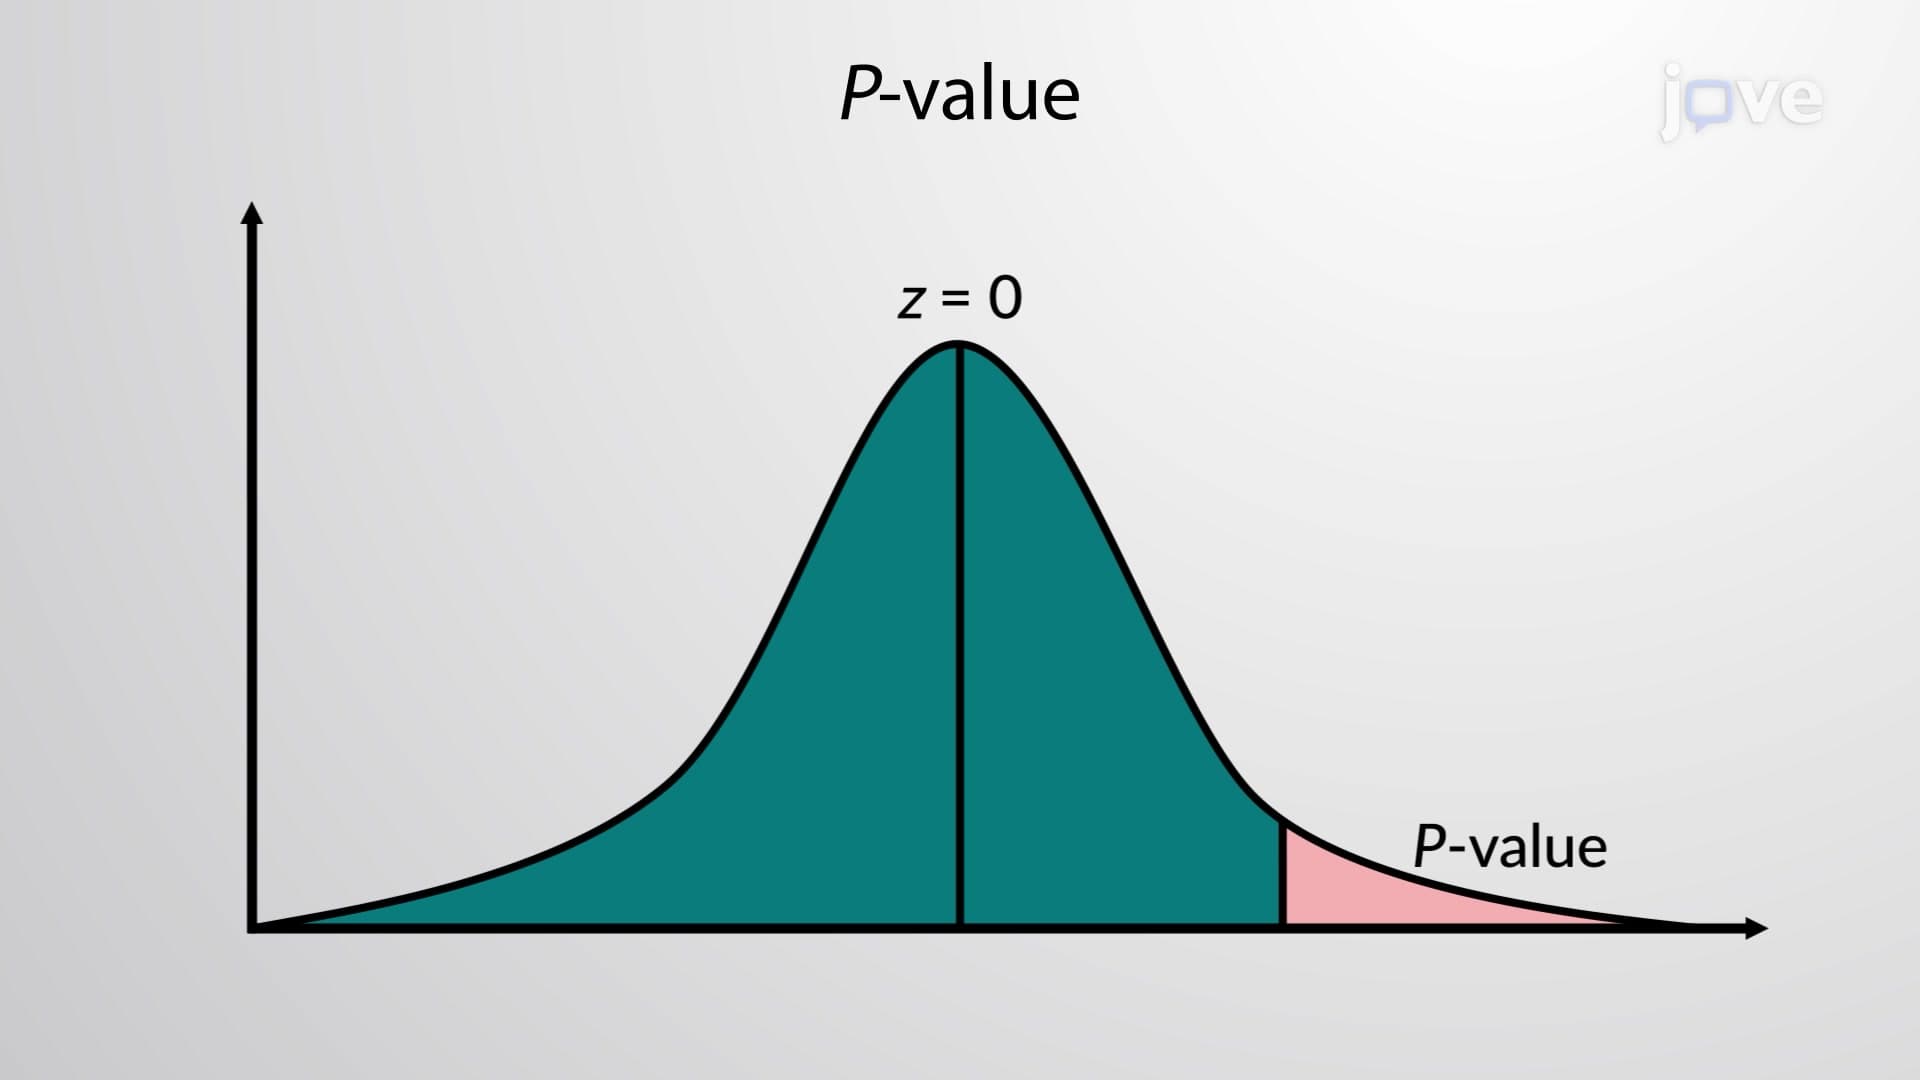
Decision Making: P-value Method
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
On...