Related Experiment Video
Updated: Jul 6, 2026

A Networked Desktop Virtual Reality Setup for Decision Science and Navigation Experiments with Multiple Participants
Published on: August 26, 2018
Safe Adaptive Policy Transfer Reinforcement Learning for Distributed Multiagent Control

Abstract:
Multiagent reinforcement learning (RL) training is usually difficult and time-consuming due to mutual interference among agents. Safety concerns make an already difficult training process even harder. This study proposes a safe adaptive policy transfer RL approach for multiagent cooperative control. Specifically, a pioneer and follower off-policy policy transfer learning (PFOPT) method is presented to help follower agents acquire knowledge and experience from a single well-trained pioneer agent. Notably, the designed approach can transfer both the policy representation and sample experience provided by the pioneer policy in the off-policy learning. More importantly, the proposed method can adaptively adjust the learning weight of prior experience and exploration according to the Wasserstein distance between the policy probability distributions of the pioneer and the follower. Case studies show that the distributed agents trained by the proposed method can complete a collaborative task and acquire the maximum rewards while minimizing the violation of constraints. Moreover, the proposed method can also achieve satisfactory performance in terms of learning speed and success rate.


Related Concept Videos
 01:21
Distributed Loads: Problem Solving
 01:21
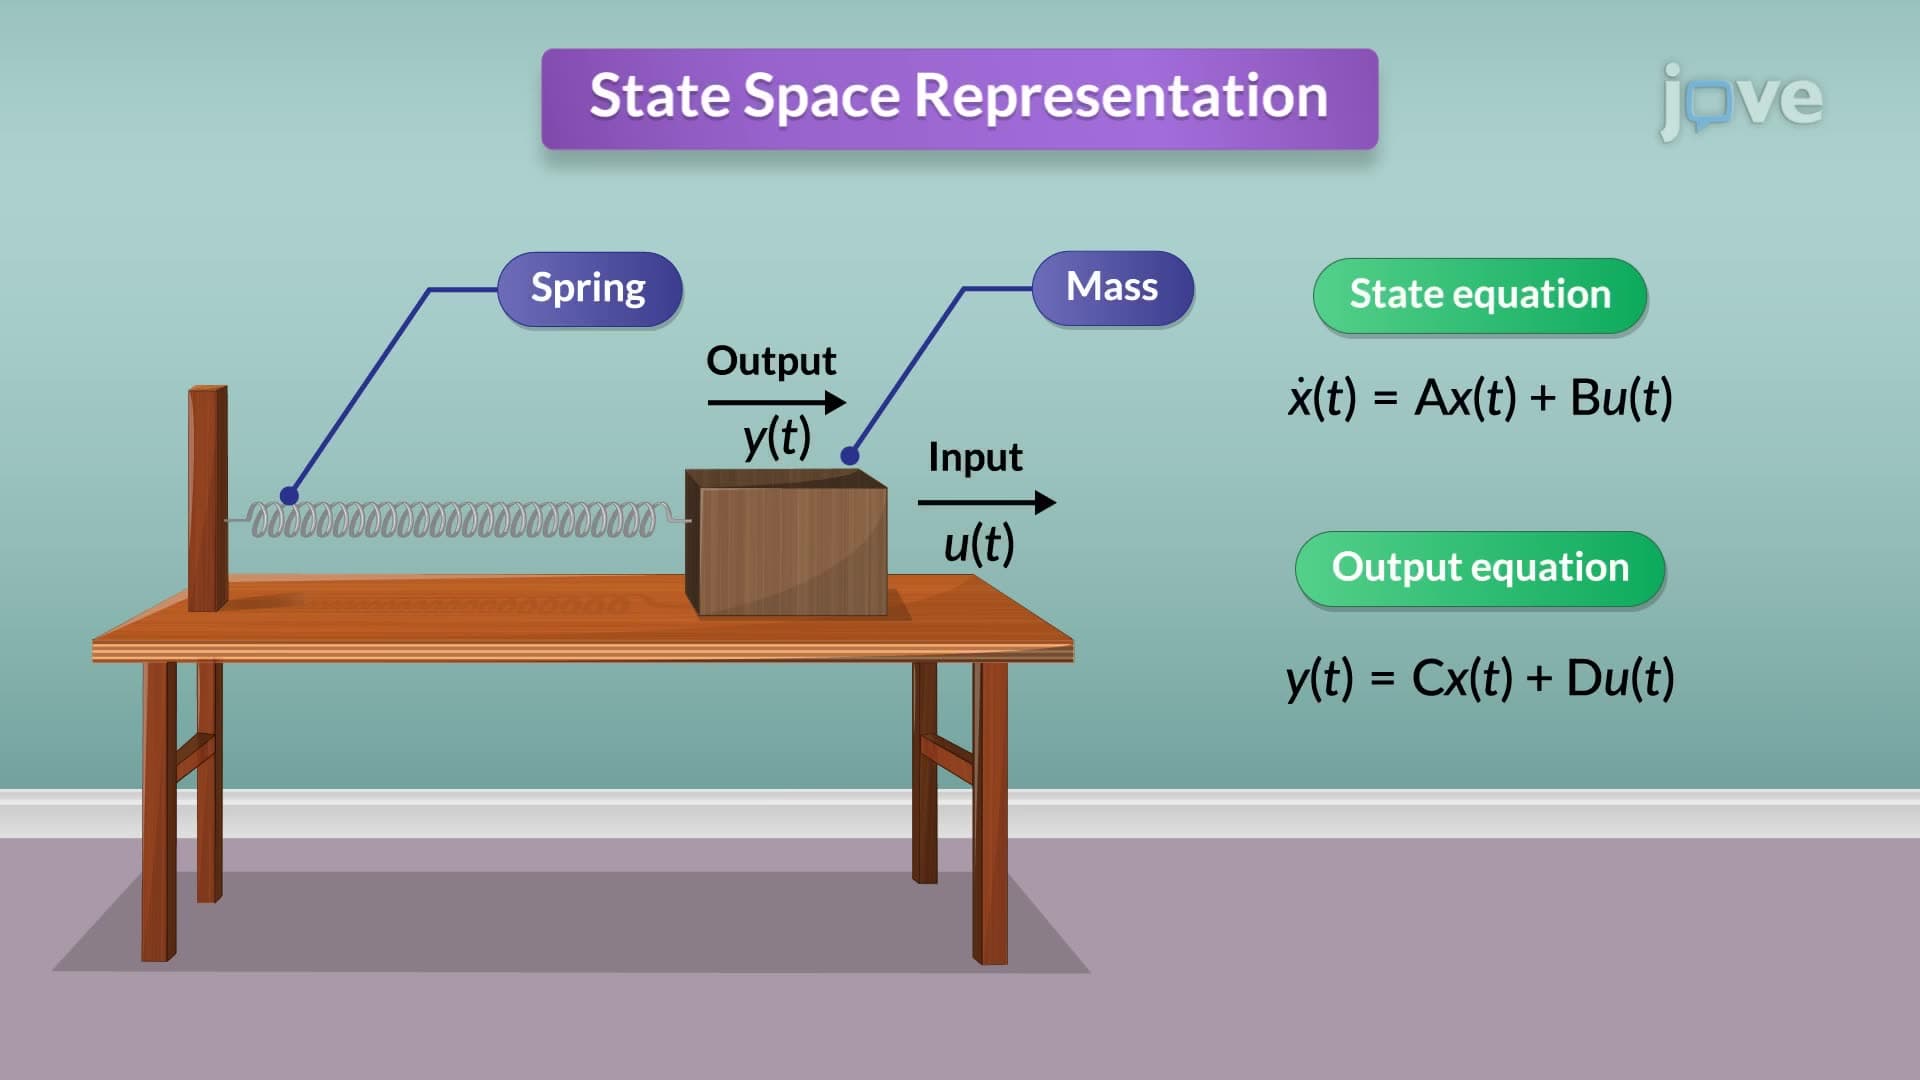
State Space to Transfer Function
The transformation process begins with the state-space representation, characterized by the state equation and the output equation. These equations are typically represented as:
 01:22
Multi-input and Multi-variable systems
In the absence of...
 01:25
Distribution Reliability and Automation
 01:23
Reinforcement
Positive reinforcement occurs when a behavior is followed by the presentation of a rewarding stimulus, increasing the frequency of that behavior. For example:
 01:12
Observational Learning