Hypergraph-Based Multi-Modal Representation for Open-Set 3D Object Retrieval
Related Experiment Video
Updated: Jul 11, 2025

Author Spotlight: Insights into the Analysis of Human Interaction with 3D Virtual Objects
Published on: October 18, 2024

Abstract:
The traditional 3D object retrieval (3DOR) task is under the close-set setting, which assumes the categories of objects in the retrieval stage are all seen in the training stage. Existing methods under this setting may tend to only lazily discriminate their categories, while not learning a generalized 3D object embedding. Under such circumstances, it is still a challenging and open problem in real-world applications due to the existence of various unseen categories. In this paper, we first introduce the open-set 3DOR task to expand the applications of the traditional 3DOR task. Then, we propose the Hypergraph-Based Multi-Modal Representation (HGM 2 R) framework to learn 3D object embeddings from multi-modal representations under the open-set setting. The proposed framework is composed of two modules, i.e., the Multi-Modal 3D Object Embedding (MM3DOE) module and the Structure-Aware and Invariant Knowledge Learning (SAIKL) module. By utilizing the collaborative information of modalities derived from the same 3D object, the MM3DOE module is able to overcome the distinction across different modality representations and generate unified 3D object embeddings. Then, the SAIKL module utilizes the constructed hypergraph structure to model the high-order correlation among 3D objects from both seen and unseen categories. The SAIKL module also includes a memory bank that stores typical representations of 3D objects. By aligning with those memory anchors in the memory bank, the aligned embeddings can integrate the invariant knowledge to exhibit a powerful generalized capacity toward unseen categories. We formally prove that hypergraph modeling has better representative capability on data correlation than graph modeling. We generate four multi-modal datasets for the open-set 3DOR task, i.e., OS-ESB-core, OS-NTU-core, OS-MN40-core, and OS-ABO-core, in which each 3D object contains three modality representations: multi-view, point clouds, and voxel. Experiments on these four datasets show that the proposed method can significantly outperform existing methods. In particular, the proposed method outperforms the state-of-the-art by 12.12%/12.88% in terms of mAP on the OS-MN40-core/OS-ABO-core dataset, respectively. Results and visualizations demonstrate that the proposed method can effectively extract the generalized 3D object embeddings on the open-set 3DOR task and achieve satisfactory performance.


Related Concept Videos
 01:06
Collisions in Multiple Dimensions: Problem Solving
A small car of mass 1,200 kg traveling east at 60 km/h collides at an intersection with a truck of mass 3,000 kg traveling due north at 40 km/h. The two vehicles are locked together. What is the...
 01:10
Vector Algebra: Graphical Method
We use the laws of geometry to construct resultant vectors, followed by trigonometry to find vector magnitudes and directions. For a geometric construction of the sum of two vectors in a plane, we follow the parallelogram rule. Suppose two vectors are at arbitrary positions. Translate either one of...
 01:29
Levels of Use of a GIS
 01:30
Three-Dimensional Force System:Problem Solving
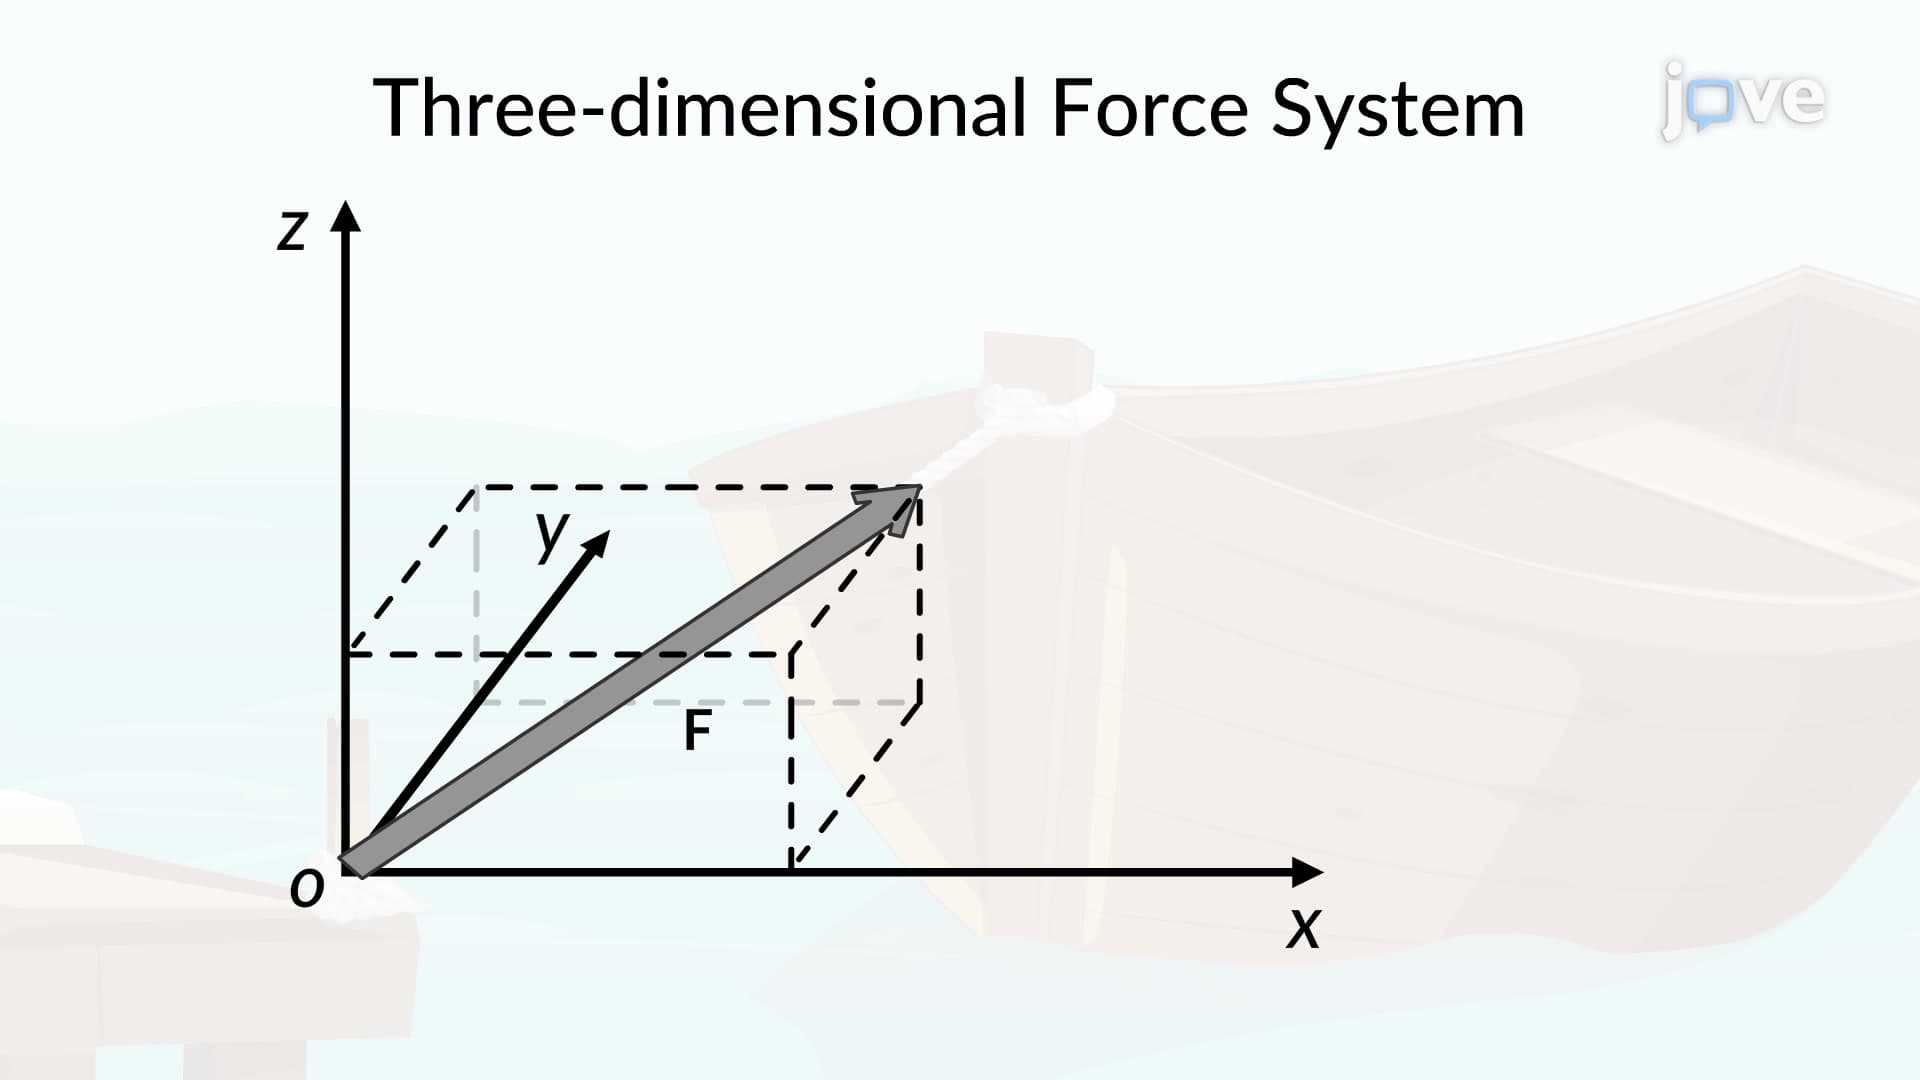
To solve a three-dimensional force system, first resolve each force into its respective scalar components. Do this using...
 01:30
Three-Dimensional Force System
 01:06
Three-Compartment Open Model