Related Experiment Video
Updated: Jul 2, 2025


Selecting Multiple Biomarker Subsets with Similarly Effective Binary Classification Performances
Published on: October 11, 2018
The Use of Information Entropy and Expert Opinion in Maximizing the Discriminating Power of Composite Indicators
Matheus Pereira Libório1, Roxani Karagiannis2, Alexandre Magno Alvez Diniz3
1Graduate Program in Computer Science, Pontifical Catholic University of Minas Gerais, Belo Horizonte 30535-901, Brazil.

Abstract:
This research offers a solution to a highly recognized and controversial problem within the composite indicator literature: sub-indicators weighting. The research proposes a novel hybrid weighting method that maximizes the discriminating power of the composite indicator with objectively defined weights. It considers the experts' uncertainty concerning the conceptual importance of sub-indicators in the multidimensional phenomenon, setting maximum and minimum weights (constraints) in the optimization function. The hybrid weighting scheme, known as the SAW-Max-Entropy method, avoids attributing weights that are incompatible with the multidimensional phenomenon's theoretical framework. At the same time, it reduces the influence of assessment errors and judgment biases on composite indicator scores. The research results show that the SAW-Max-Entropy weighting scheme achieves greater discriminating power than weighting schemes based on the Entropy Index, Expert Opinion, and Equal Weights. The SAW-Max-Entropy method has high application potential due to the increasing use of composite indicators across diverse areas of knowledge. Additionally, the method represents a robust response to the challenge of constructing composite indicators with superior discriminating power.


Related Concept Videos
 00:57
Weighted Mean
For example, consider the number of goals scored in the matches of a tournament. While computing the average number of goals scored in the tournament, it may be more important to...
 01:19
Expected Frequencies in Goodness-of-Fit Tests
 01:09
Decision Making: P-value Method
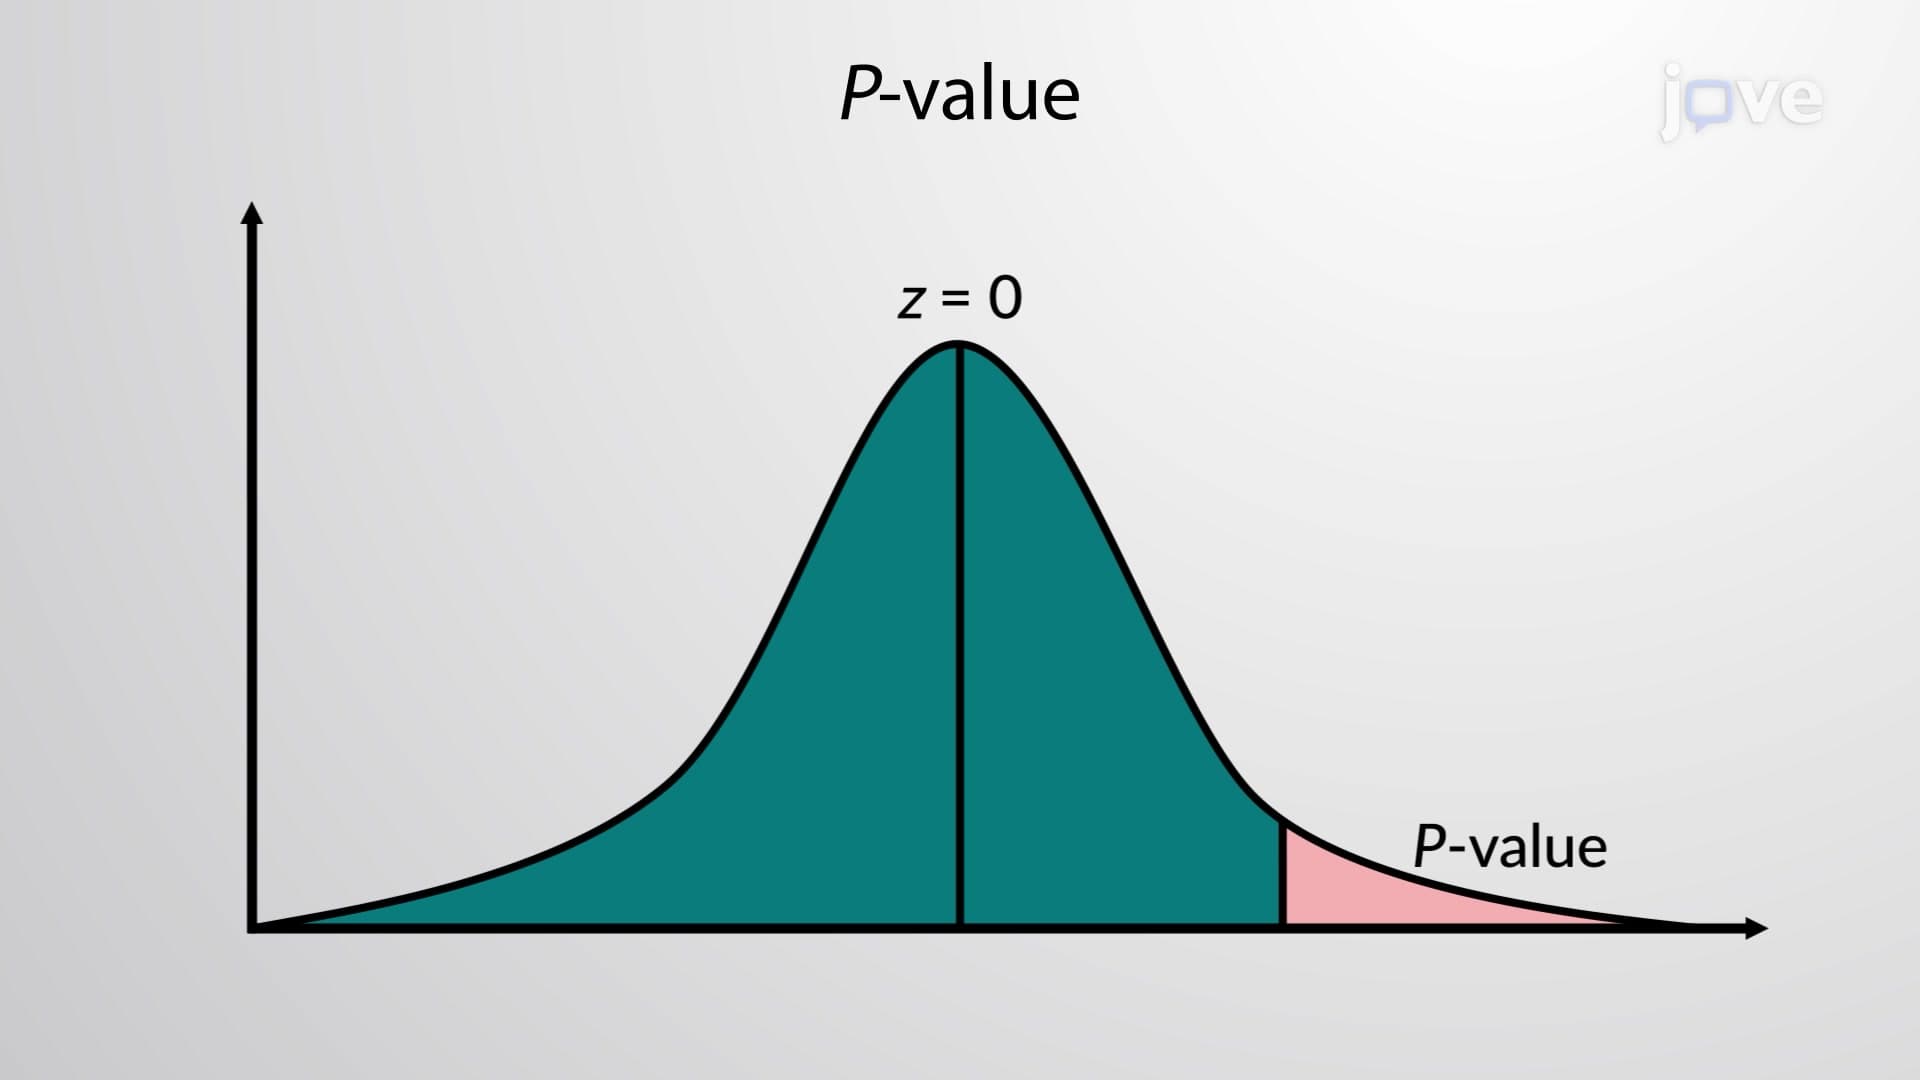
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
 01:10
Review and Preview
Percentiles are a type of fractile that partition data into...
 01:11
Statistical Analysis: Overview
One of the most commonly used statistical quantifiers is the mean, which is the ratio between the sum of the numerical values of all results and the...
 01:13
Sensitivity, Specificity, and Predicted Value
Sensitivity is the...