Related Experiment Video
Updated: Jul 2, 2025

Assisted Selection of Biomarkers by Linear Discriminant Analysis Effect Size LEfSe in Microbiome Data
Published on: May 16, 2022
Numerically stable locality-preserving partial least squares discriminant analysis for efficient dimensionality
1School of Mathematical Sciences, Universiti Sains Malaysia, 11800, Penang, Malaysia.

Abstract:
Dimensionality reduction plays a pivotal role in preparing high-dimensional data for classification and discrimination tasks by eliminating redundant features and enhancing the efficiency of classifiers. The effectiveness of a dimensionality reduction algorithm hinges on its numerical stability. When data projections are numerically stable, they lead to enhanced class separability in the lower-dimensional embedding, consequently yielding higher classification accuracy. This paper investigates the numerical attributes of dimensionality reduction and discriminant subspace learning, with a specific focus on Locality-Preserving Partial Least Squares Discriminant Analysis (LPPLS-DA). High-dimensional data frequently introduce singularity in the scatter matrices, posing a significant challenge. To tackle this issue, the paper explores two robust implementations of LPPLS-DA. These approaches not only optimize data projections but also capture more discriminative features, resulting in a marked improvement in classification accuracy. Empirical evidence supports these findings through numerical experiments conducted on synthetic and spectral datasets. The results demonstrate the superior performance of the proposed methods when compared to several state-of-the-art dimensionality reduction techniques in terms of both classification accuracy and dimension reduction.

Related Concept Videos
 01:11
Residuals and Least-Squares Property
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
 01:11
How Data are Classified: Categorical Data
Data are classified based on whether they are measurable or not. Categorical data cannot be measured; instead, it can be divided into categories. For example, if Y denotes a person's party affiliation, some examples of Y include...
 01:31
Classification of Systems-II
 01:29
Mechanistic Models: Compartment Models in Algorithms for Numerical Problem Solving
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...
 01:26
Classification of Systems-I
Homogeneity dictates that if an input x(t) is multiplied by a constant c, the output y(t) is multiplied by the same constant. Mathematically, this is expressed as:
 01:14
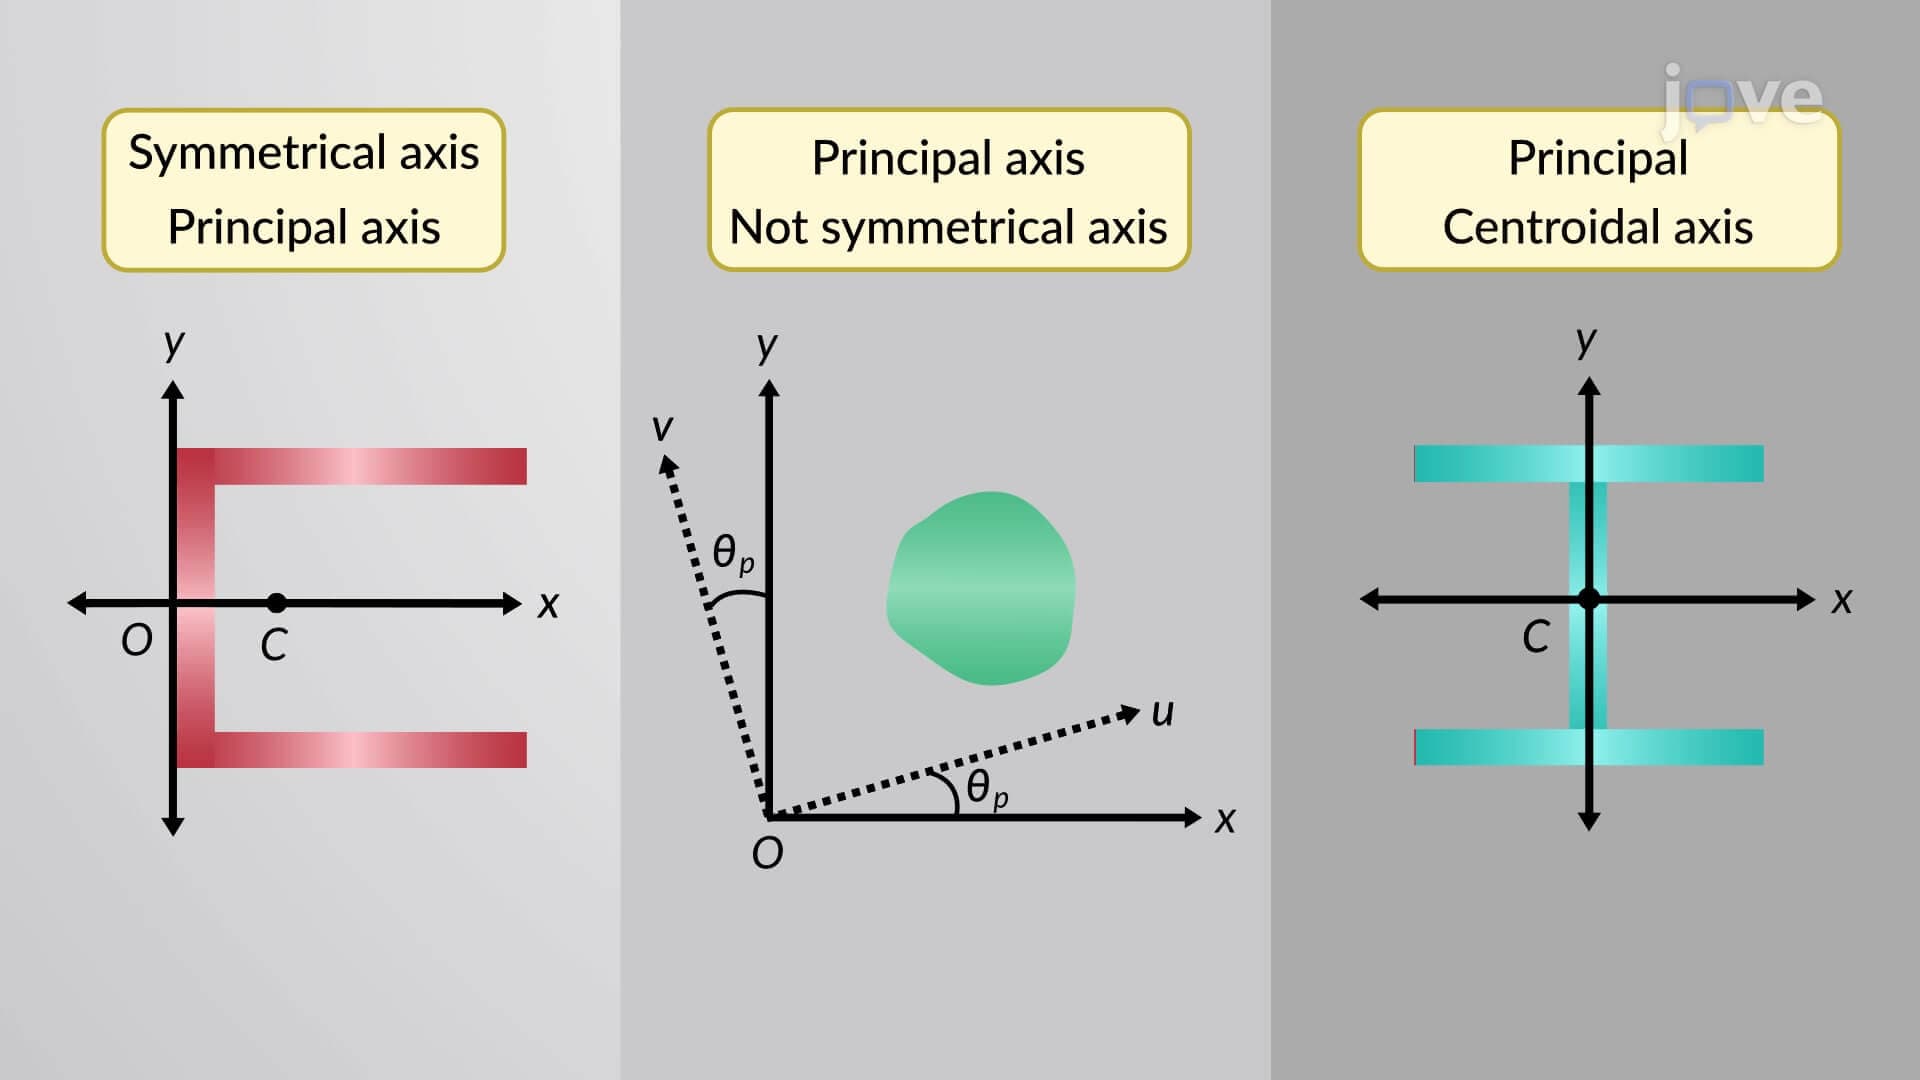
Principal Moments of Area
The principal moment of inertia axes are the...